Historical evidence boundary — checked October 13, 2026: This page remains the original August 8–9 consumer-web report. The frozen prompts, first and repeat outputs, blind-grader assignments and score sheets, alpha files, timing logs, account-gate receipts, and captured Arena pages were not recovered in this maintenance pass. The published scores and workflow conclusions are preserved as the original dated report, not independently reproduced. The “choose” guidance remains historical to those tested surfaces and is not a current-generation buying recommendation. The later October 7 source updates retain their own dated scope; their prices, availability and successor-model statements have not been recertified as current offers.
Separate October 15 test, linked October 22: For newer hosted API evidence, see our 516-image comparison including Grok Imagine Image 2.0, GPT Image 2/2.5 and Nano Banana 2.1. It uses 16 generation prompts with two draws per configuration and an automated four-check rubric, with settings differences and no independent human panel. Its scores are separate from this August consumer-web report; they do not recover or validate the older evidence. Read the later comparison’s method and limitations beside its results.
Verdict in the original August 8 report: GPT Image 2 led the reported results for text-heavy graphics, packaging, references and visual-world consistency. Nano Banana 2 was the report’s speed-first choice for frequent drafts. Grok Imagine Image 2.0 had the most intriguing editing feature list and appeared second on the August 8 Arena snapshots; those positions do not establish a current winner. Its original Quality submission and an unscored Speed check were reported as gated; a later signed-in Quality follow-up completed one frozen Test 1 prompt, unscored and not a comparable rerun.
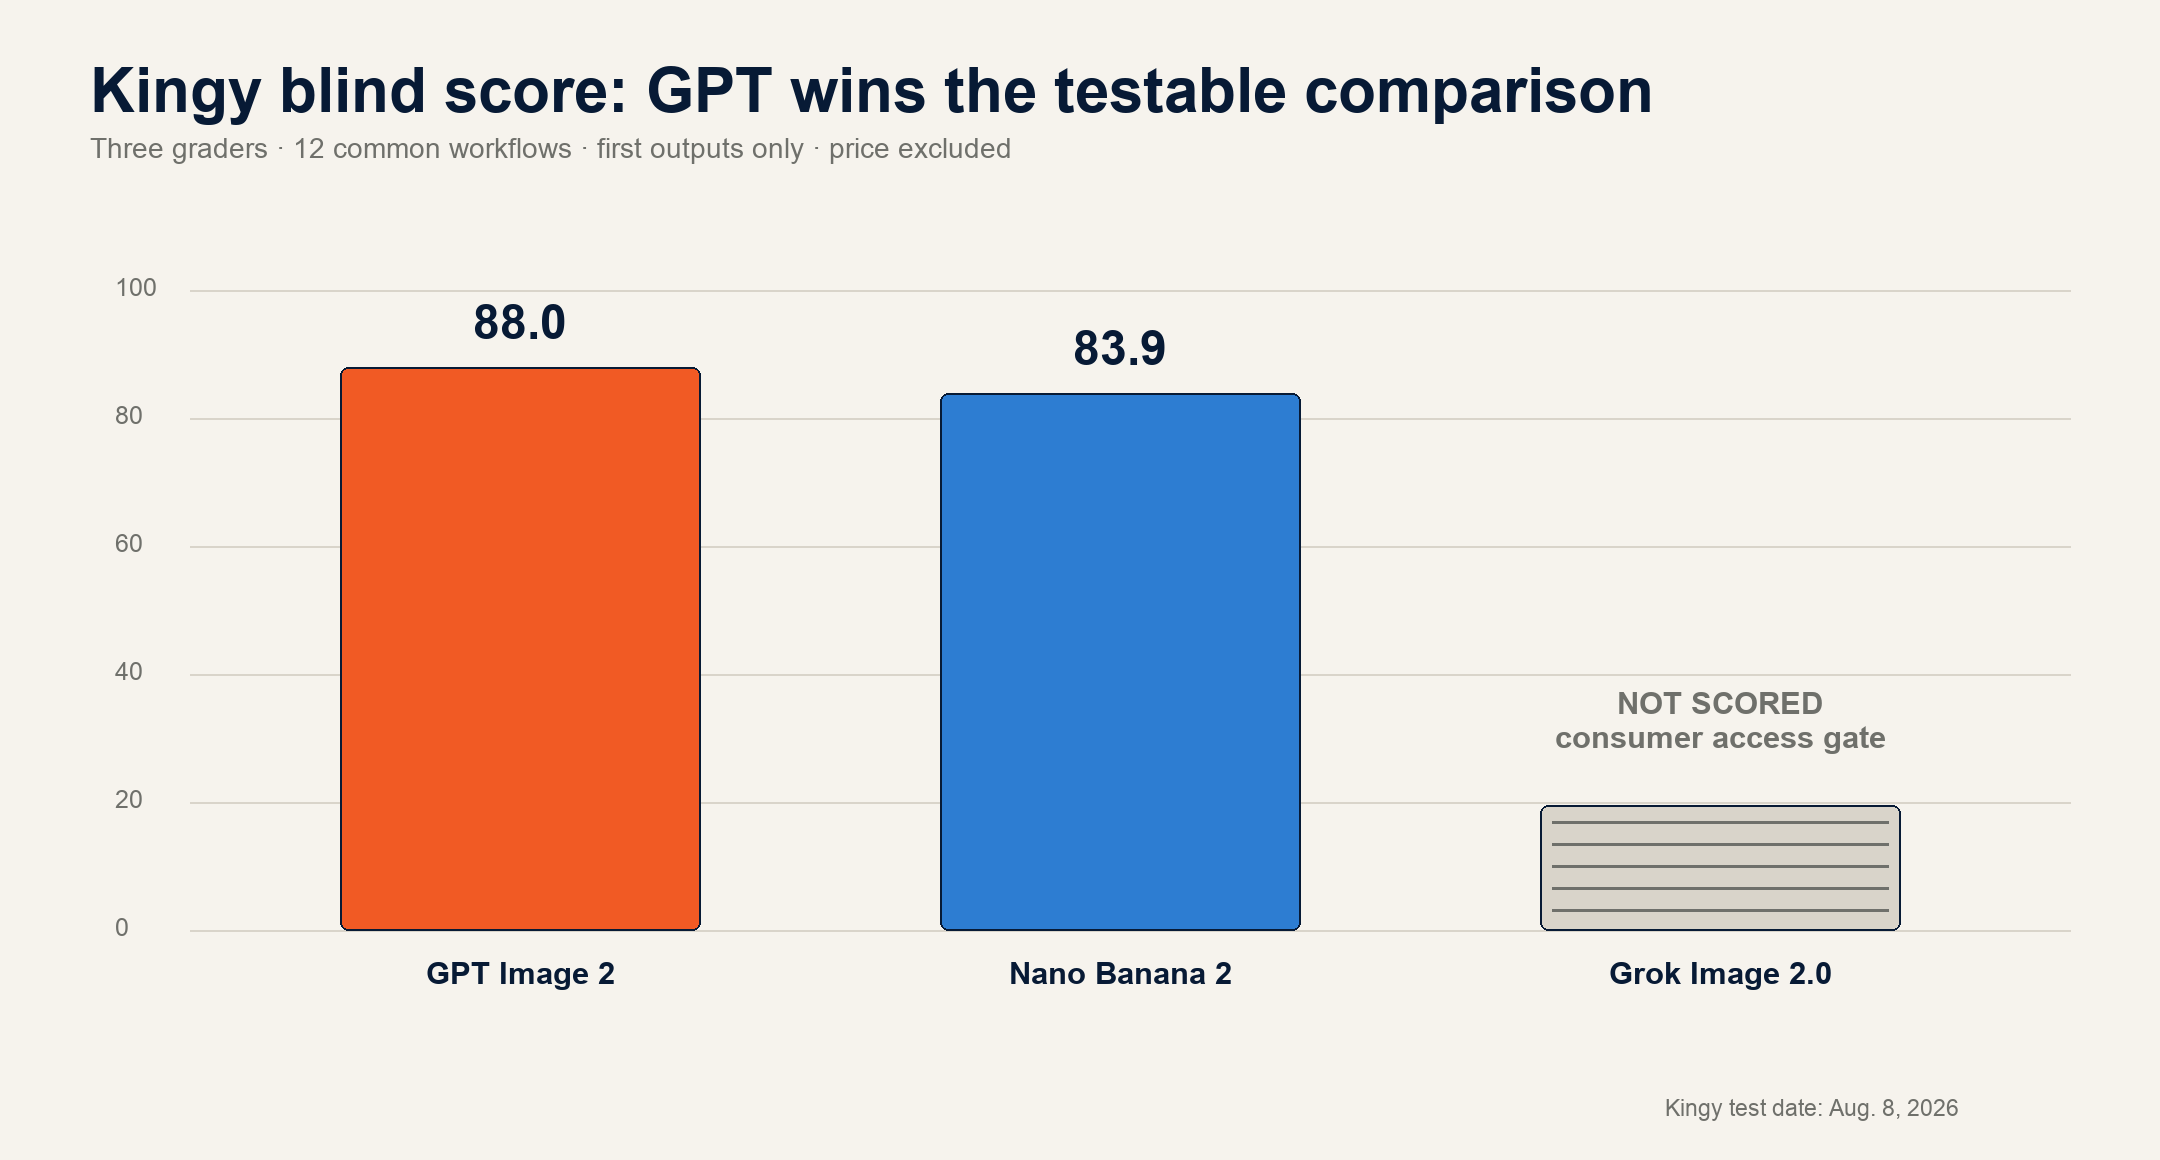
The original article reports that it attempted 15 real-world workflows on August 8, 2026, saved the first output, repeated six critical tests, and had three graders score randomized GPT and Nano results before revealing model names. It reports scores of 88.0/100 for GPT Image 2 and 83.9/100 for Nano Banana 2, with price excluded, and no Kingy quality score for Grok. The original outputs, grader files, and timing logs were not recovered for this review; these remain dated published results, not independently reproduced measurements.
At the August 8 cutoff, the original report recommended GPT Image 2 for finished creative and Nano Banana 2 for fast iteration, while treating Grok Image 2.0 as promising but unscored pending a comparable rerun. This is the report’s historical conclusion, not current purchase advice.
Testing disclosure: We used signed-in ChatGPT Pro, Gemini Free and Grok Free consumer web access on macOS/Chrome. No plan was upgraded, no credits were bought and no trial was started. ChatGPT and Gemini completed the common tests. Grok’s Quality submission opened an upgrade dialog before producing an image. A later, explicitly unscored Speed check reached the same gate and produced no output. After publication, a signed-in Grok Imagine Quality follow-up completed the exact frozen Test 1 prompt; that one output remains outside the original scores.
API migration update: act before November 2, 2026
Checked October 29, 2026: If your application uses xAI’s legacy grok-imagine-image-quality model ID, review its configuration before November 2. According to xAI’s migration notice, requests to /v1/images/generations and /v1/images/edits using that ID will be redirected to grok-imagine-image-2.0 with quality set to low. The old ID will continue to resolve, but it will select the replacement model. The indirect pro alias follows the redirect too; the separate 1.0 model ID is unaffected.
xAI says request and response shapes and parameters remain unchanged. We have not tested the migration against the provider’s API, so that statement is the provider’s claim, not our compatibility result. The notice gives November 2 as the date; it does not specify an exact cutover time or time zone. Make changes before that date rather than relying on a particular hour.
Make the model and quality explicit
Search configuration files, environment-specific settings, SDK wrappers and job definitions for the legacy ID and the pro alias. For predictable selection, we recommend specifying the replacement model and low quality explicitly. These illustrative JSON fragments show the relevant fields for a generation request; replace the example prompt with your own. They are configuration examples, not API calls.
Before:
{
  "model": "grok-imagine-image-quality",
  "prompt": "Example prompt"
}
After:
{
  "model": "grok-imagine-image-2.0",
  "quality": "low",
  "prompt": "Example prompt"
}
Do not assume an omitted quality field always selects low. xAI documents auto as low for generation and medium for editing under current behavior. If you want a different quality setting, choose it deliberately and assess it for your use case.
Test and roll out
When you have authorized any provider charges, test the explicit configuration in staging for both generation and editing where your application uses them. Inspect the returned model information where available, and record the requested quality, errors, output dimensions and size, latency and observed cost. Compare outputs against your own acceptance criteria. We have not run those paid tests, and the historical consumer-web comparison below does not establish how the replacement will perform in your integration.
Roll out gradually and watch production logs. If results fail your checks, return to an explicit last-known-working 2.0 configuration, or queue or disable the affected function while you investigate. After cutover, switching back to the retired alias cannot restore the old model.
Follow the AI Stack Change Radar for documented provider changes. The original August results and API availability statements below describe their dates; they are not current API status or a new model ranking.
Evidence and checks: Our first archived capture of this notice was October 28, 2026 at 16:25:23 UTC; the October 29 capture at 21:35:22 UTC contains the same notice. Those observations do not establish when xAI edited it, and we have no earlier tracker baseline. The tracker data retains the source and snapshot identities. The JSON examples above passed local syntax checks; no provider request was sent. This dated addition updates the API guidance while retaining the original article and its earlier dated source notes.
Reported workflow results from August 8
| Workflow | Best choice | Why |
|---|---|---|
| Dense infographics | GPT Image 2 | Cleaner hierarchy and more faithful microcopy |
| Small-text advertising | Tie | Both produced credible posters; each missed some tiny details |
| Multilingual typography | GPT Image 2, narrowly | Slightly stronger overall compliance; both were impressive |
| Counting and spatial logic | GPT Image 2 | Better object count and placement fidelity |
| Portraits and anatomy | GPT Image 2 | More natural hands, face and material detail |
| Reflections and physical logic | GPT Image 2 | More coherent condensation, glass and mirrored objects |
| Packaging and labels | GPT Image 2 | Stronger brand block, text hierarchy and shelf-ready finish |
| Precise local edits | GPT Image 2, with caveats | Better target change, but neither preserved the source pixel-for-pixel |
| Preservation outside edits | GPT Image 2, with caveats | Lower collateral change; still a regeneration, not a surgical edit |
| Character consistency | GPT Image 2 | More stable costume, face and narrative continuity |
| Visual-world consistency | GPT Image 2 | Stronger reuse of the supplied palette and graphic grammar |
| Smart resize/outpainting | Nano Banana 2, narrowly | Preserved more source content, though it introduced duplication |
| Fast iterative drafting | Nano Banana 2 | Approx. 14.5s median vs 34.6s for GPT in recorded common/repeat runs |
| True transparent PNG in our consumer test | GPT Image 2 | Alpha channel measured 0–254; Nano baked in a checkerboard |
| Grok-only compositing/local tools | Unverified by Kingy | xAI advertises up to five inputs and Magic Wand; access gate blocked our run |
Three evidence layers—and why they do not say the same thing
This comparison keeps three kinds of evidence separate.
Vendor claims: xAI says Imagine Image 2.0 improves instruction following, typography, small text, editing preservation and feature breadth. Its official launch post describes Magic Wand localized edits, segmentation, transparent background removal, up to five reference inputs and Smart Resize across nine aspect ratios. OpenAI and Google make their own capability claims in their model documentation. These are useful specifications, not Kingy findings.
Arena evidence: anonymous preference voting at the August 8 cutoff placed GPT first and Grok second. It measures broad human preference under Arena’s conditions; it is not our workflow rubric and it does not prove a specific consumer plan will expose a model.
Kingy test results: our controlled consumer-web comparison covers only outputs we actually generated and preserved. It measures first-output utility on 12 shared workflows, plus three ceiling tests. This layer can support a GPT-versus-Nano score. The later Grok follow-up supports a hands-on example and verified account access, but one unscored output still cannot support a Grok quality score.
That distinction also prevents a naming error. At the August 8 cutoff, grok-imagine-image-2.0 was not yet available through the API and no 2.0 API price had been published. The October 7 source note reported that SpaceXAI offered that exact model through the API and listed image input at $0.01 each and output pricing from $0.04 per image, varying by quality and resolution. The source snapshot was not recovered here, so these are October 7 reported terms, not current prices. Those later API terms do not change the frozen consumer-web test.
Arena standings captured August 8, 2026
The text-to-image leaderboard and image-edit leaderboard were dated August 7, 2026 and checked August 8 at 18:55 PDT. Variant names matter: GPT appears as medium, Grok as low, and Nano Banana 2 as the web-search variant.
| Board | Model variant | Rank | Score and interval | Votes | Rank spread |
|---|---|---|---|---|---|
| Text-to-image | gpt-image-2 (medium) | 1 | 1380 ± 5 | 69,194 | 1–1 |
| Text-to-image | grok-imagine-image-2.0 (low) | 2 | 1320 ± 12 | 2,722 | 2–3, preliminary |
| Text-to-image | gemini-3.1-flash-image (nano-banana-2) [web-search] | 6 | 1263 ± 5 | 27,910 | 5–9 |
| Single Image Edit | gpt-image-2 (medium) | 1 | 1463 ± 4 | 184,189 | 1–1 |
| Single Image Edit | grok-imagine-image-2.0 (low) | 2 | 1439 ± 8 | 5,931 | 2–2, preliminary |
| Single Image Edit | Nano Banana 2 [web-search] | 10 | 1385 ± 4 | 102,657 | 5–10 |
The boards displayed 5,895,429 text-to-image votes across 76 models and 28,831,297 image-edit votes across 53 models. Grok’s intervals are wider because its new variant has far fewer votes. Treat second place as strong early evidence, not a settled long-run rank.
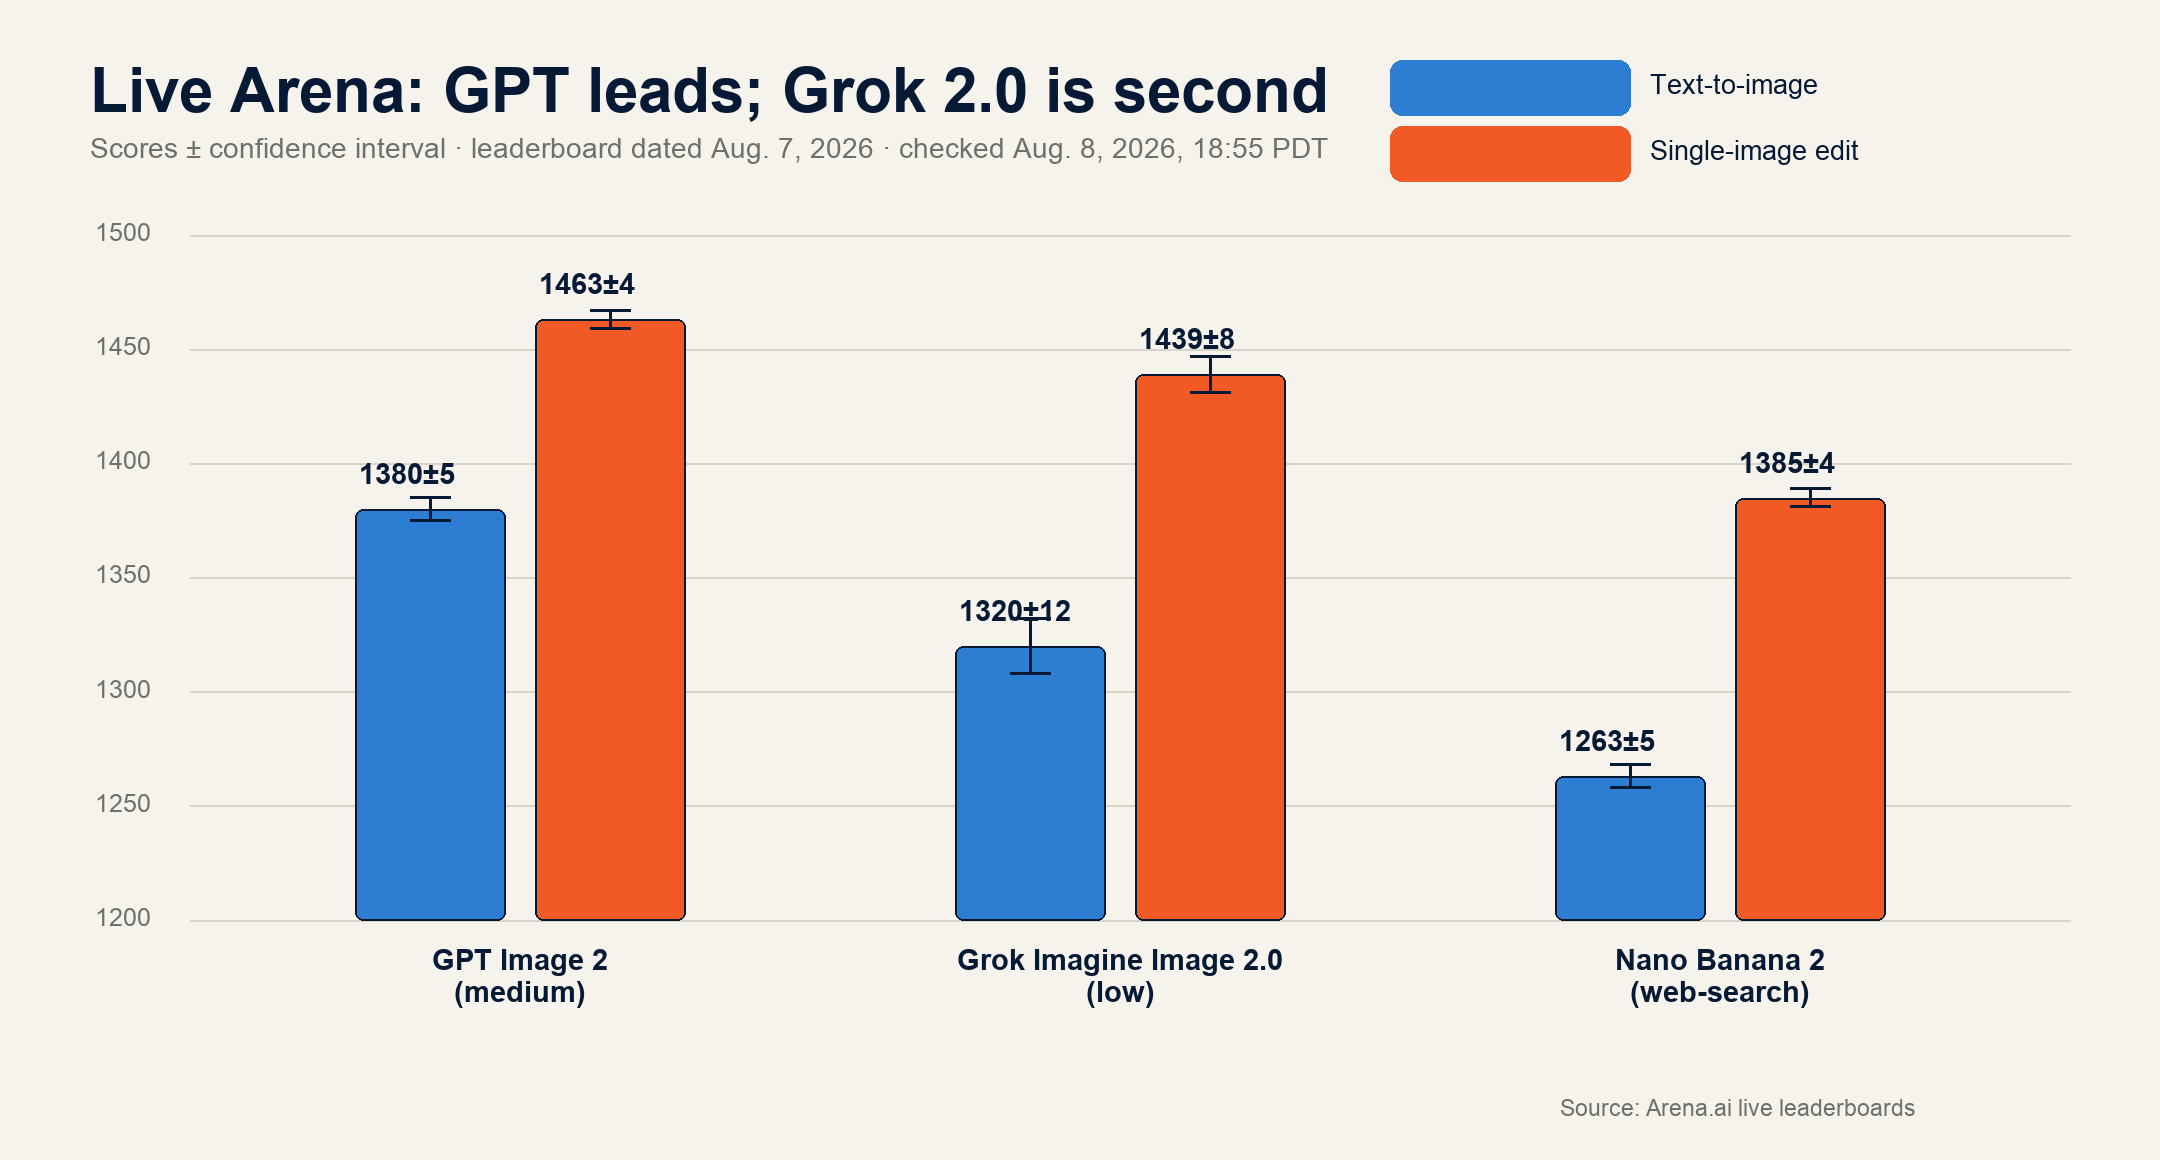
If you saw our original GPT Image 2 benchmark coverage, this table preserves the August 8 snapshot. Arena standings can change; these scores should not be presented as current.
How we tested
We froze the protocol before generation. Twelve common tests used the same prompt, input, aspect ratio and closest available consumer setting. Tests covered dense English infographics, small advertising text, multilingual typography, counting and spatial relationships, portrait anatomy, physical logic, package labels, local edits, preservation, reference consistency, style consistency, and outpainting.
Three feature-ceiling tests then examined Grok five-reference compositing, transparent-background removal, and each rival’s strongest practical workflow. Six critical prompts—tests 1, 2, 4, 7, 8 and 10—were repeated exactly once to check consistency.
We saved the first output from every completed run. There was no aesthetic rerolling. The record includes timestamp, platform, settings, elapsed time, retries, errors, dimensions and decoded alpha. One ChatGPT upload-control retry occurred before generation; it is logged. All 18 common and repeat generation jobs completed on both ChatGPT and Gemini.
The blind packets randomized GPT and Nano into A/B positions with a fixed seed. Three grading subagents scored them independently before we revealed the mapping. The pre-registered weights were:
- 25% prompt compliance
- 15% text and layout accuracy
- 15% edit locality and preservation
- 15% reference consistency
- 10% realism and physical coherence
- 10% composition
- 5% resize/alpha correctness
- 5% reliability and latency
Price was kept out of quality. The published article said a protocol, raw grader files, label reveal, run log and original files existed in an evidence pack; that pack was not recovered for this review, so those materials were not independently checked.
Results from all 12 common tests
| # | Test | GPT | Nano | Winner | What decided it |
|---|---|---|---|---|---|
| 1 | Dense English infographic | 9.76 | 8.61 | GPT | Denser copy and cleaner hierarchy |
| 2 | Small-text advertising poster | 9.68 | 9.64 | Tie | 0.05-point difference |
| 3 | Multilingual typography | 9.81 | 9.64 | GPT, narrow | 0.17-point difference |
| 4 | Counting/spatial relationships | 9.30 | 8.79 | GPT | More exact object structure |
| 5 | Portrait/anatomy | 9.01 | 8.49 | GPT | More coherent portrait detail |
| 6 | Materials/reflections | 9.21 | 9.00 | GPT | Better physical cues |
| 7 | Packaging/label fidelity | 9.78 | 9.35 | GPT | More finished, faithful label system |
| 8 | Precise local editing | 8.74 | 7.86 | GPT | Better edit target; both changed outside region |
| 9 | Outside-region preservation | 8.90 | 8.14 | GPT | Less collateral drift; neither was pixel-locked |
| 10 | Character/reference consistency | 9.47 | 8.74 | GPT | Better identity and costume continuity |
| 11 | Visual-world style consistency | 9.72 | 8.53 | GPT | Stronger shared visual grammar |
| 12 | Smart resize/outpainting | 7.21 | 7.48 | Nano, narrow | More source preservation; both had defects |
The row scores are workflow-specific grader aggregates on a 0–10 scale. The overall 88.0 and 83.9 scores additionally include the pre-registered reliability/latency dimension.
Tests 1–4: text, language and counting
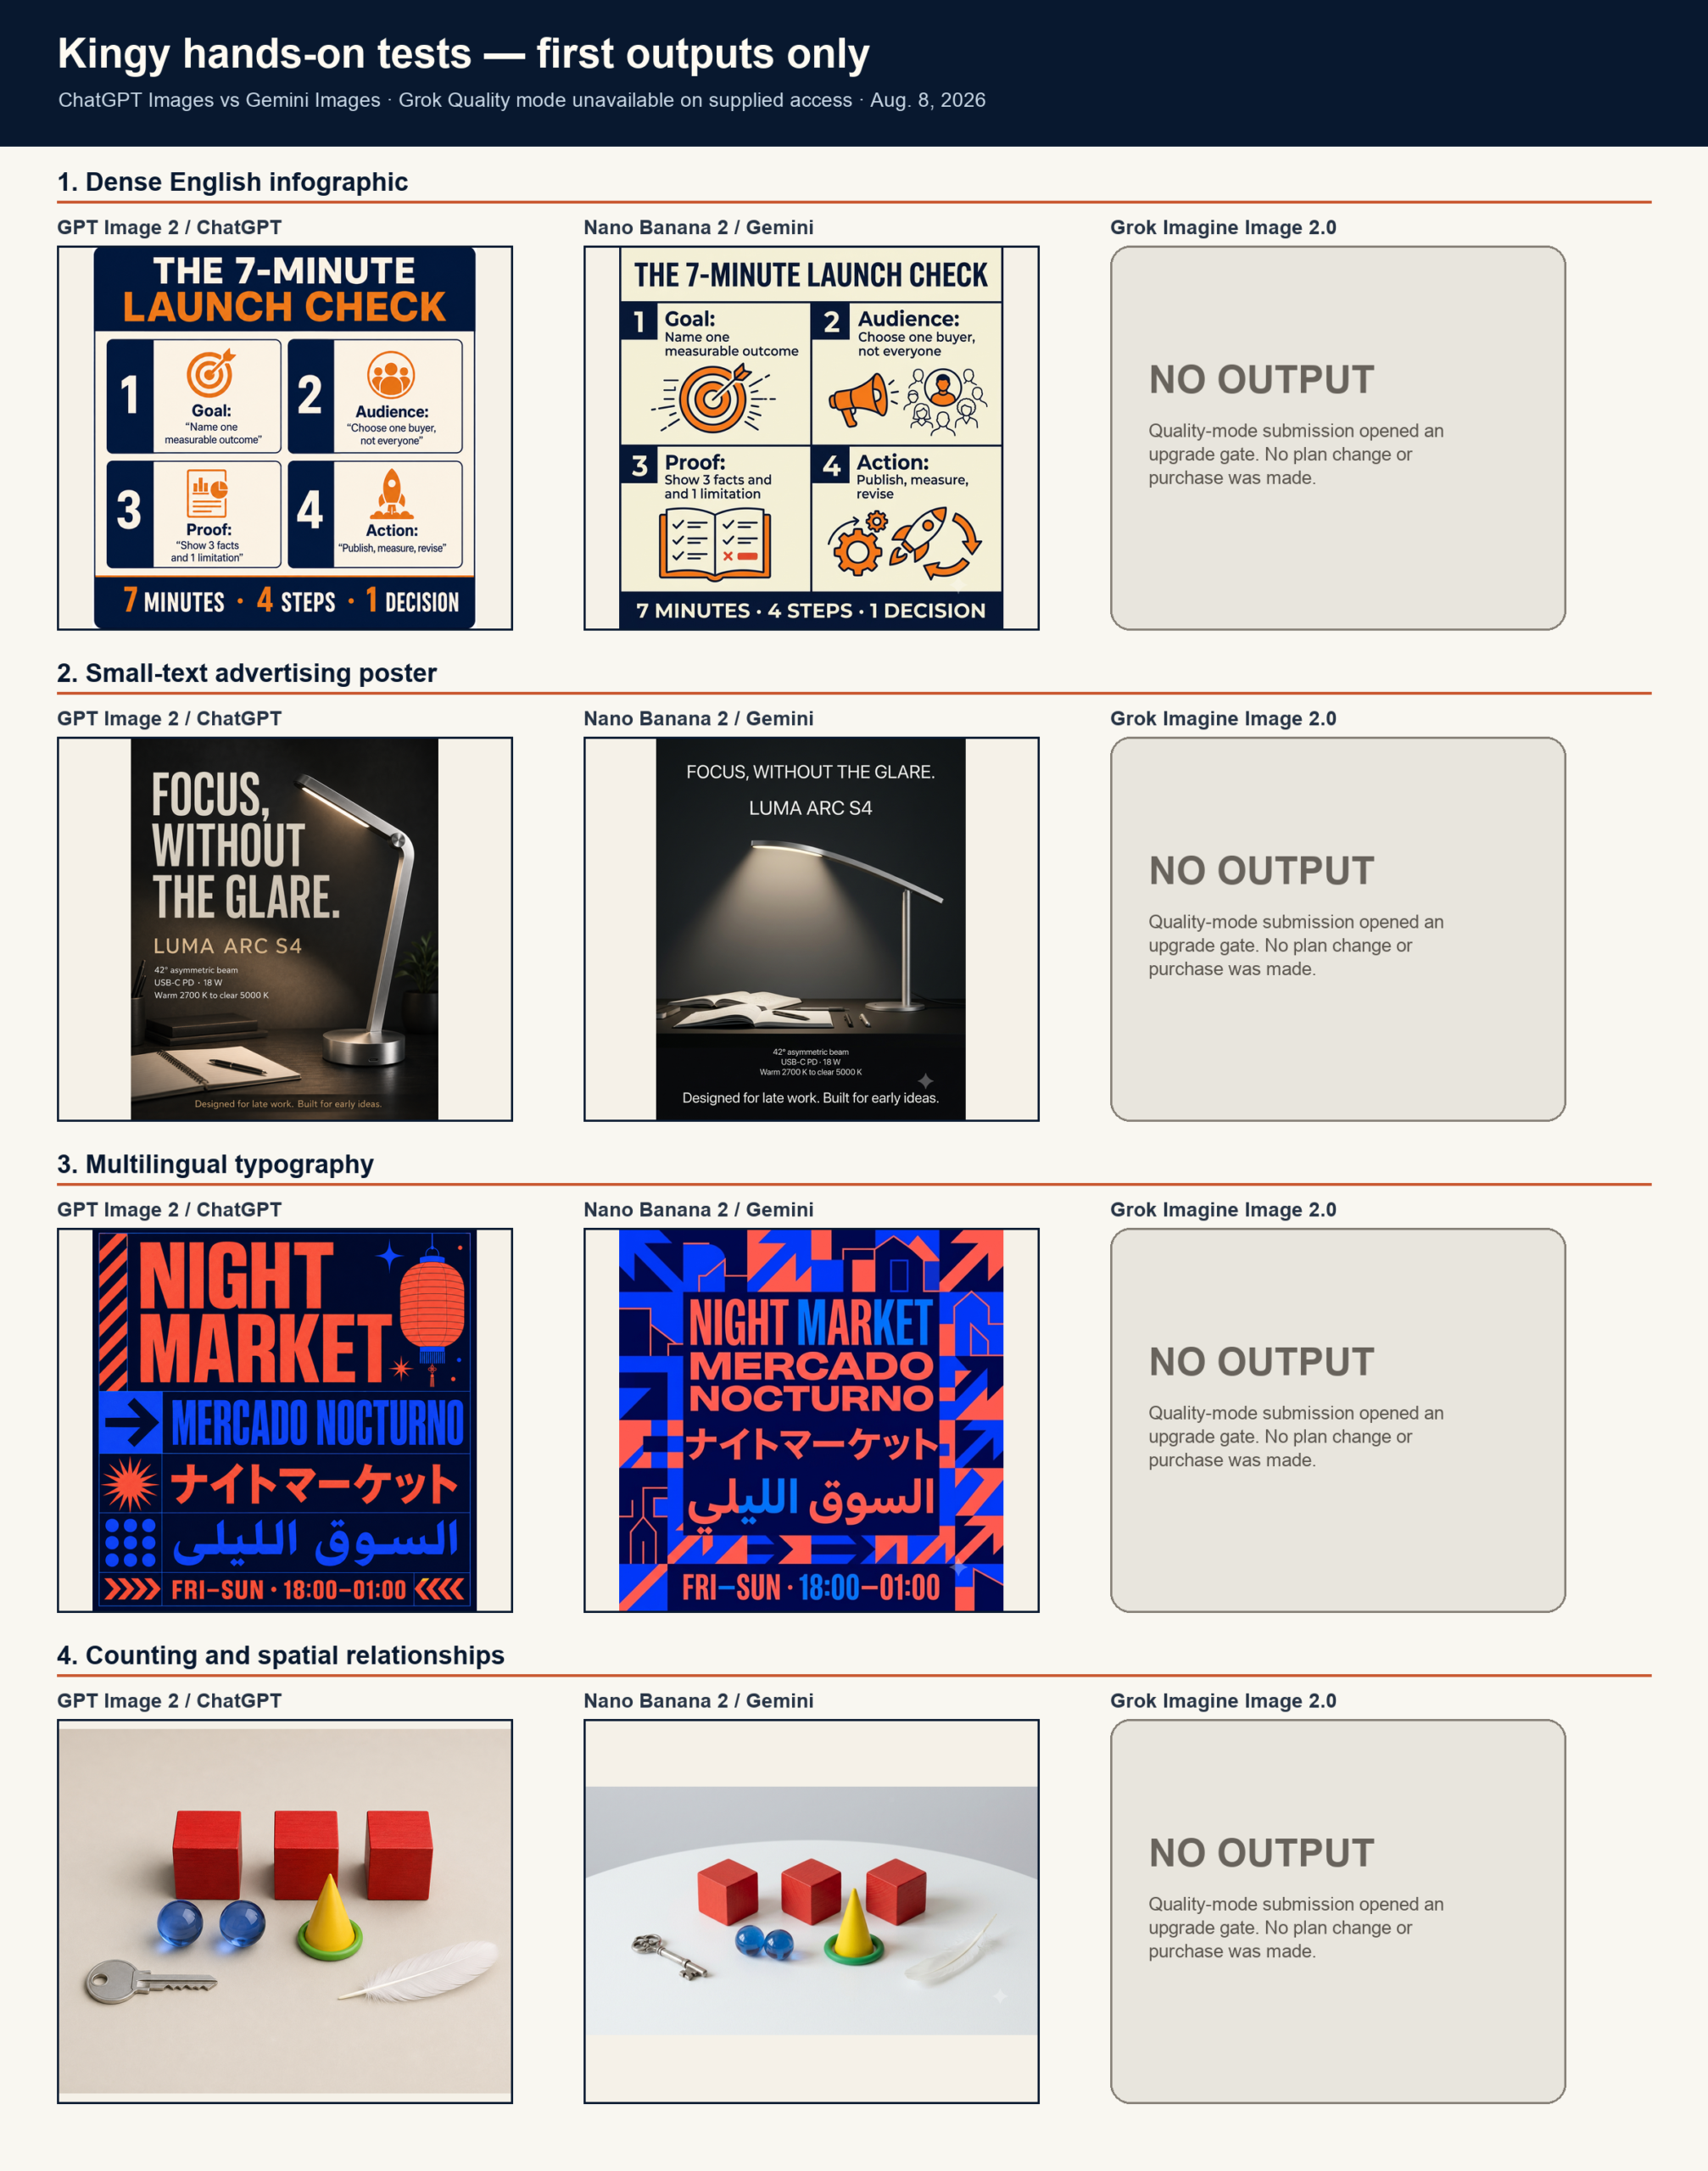
GPT’s dense infographic was the clearest separation: stronger hierarchy, more of the requested microcopy and a convincing information-design rhythm. Nano’s poster was attractive but simplified. The small-text ad was effectively a tie. Both models correctly handled a surprising amount of Spanish, Japanese and Arabic display text, although neither should replace human proofreading.
The counting scene exposed why “looks right” is not enough. Both produced polished tabletop photography, but GPT adhered more closely to the specified object inventory and relationships. For ecommerce diagrams, classroom materials or safety instructions, count every object before publishing.
Tests 5–8: realism, packaging and local edits
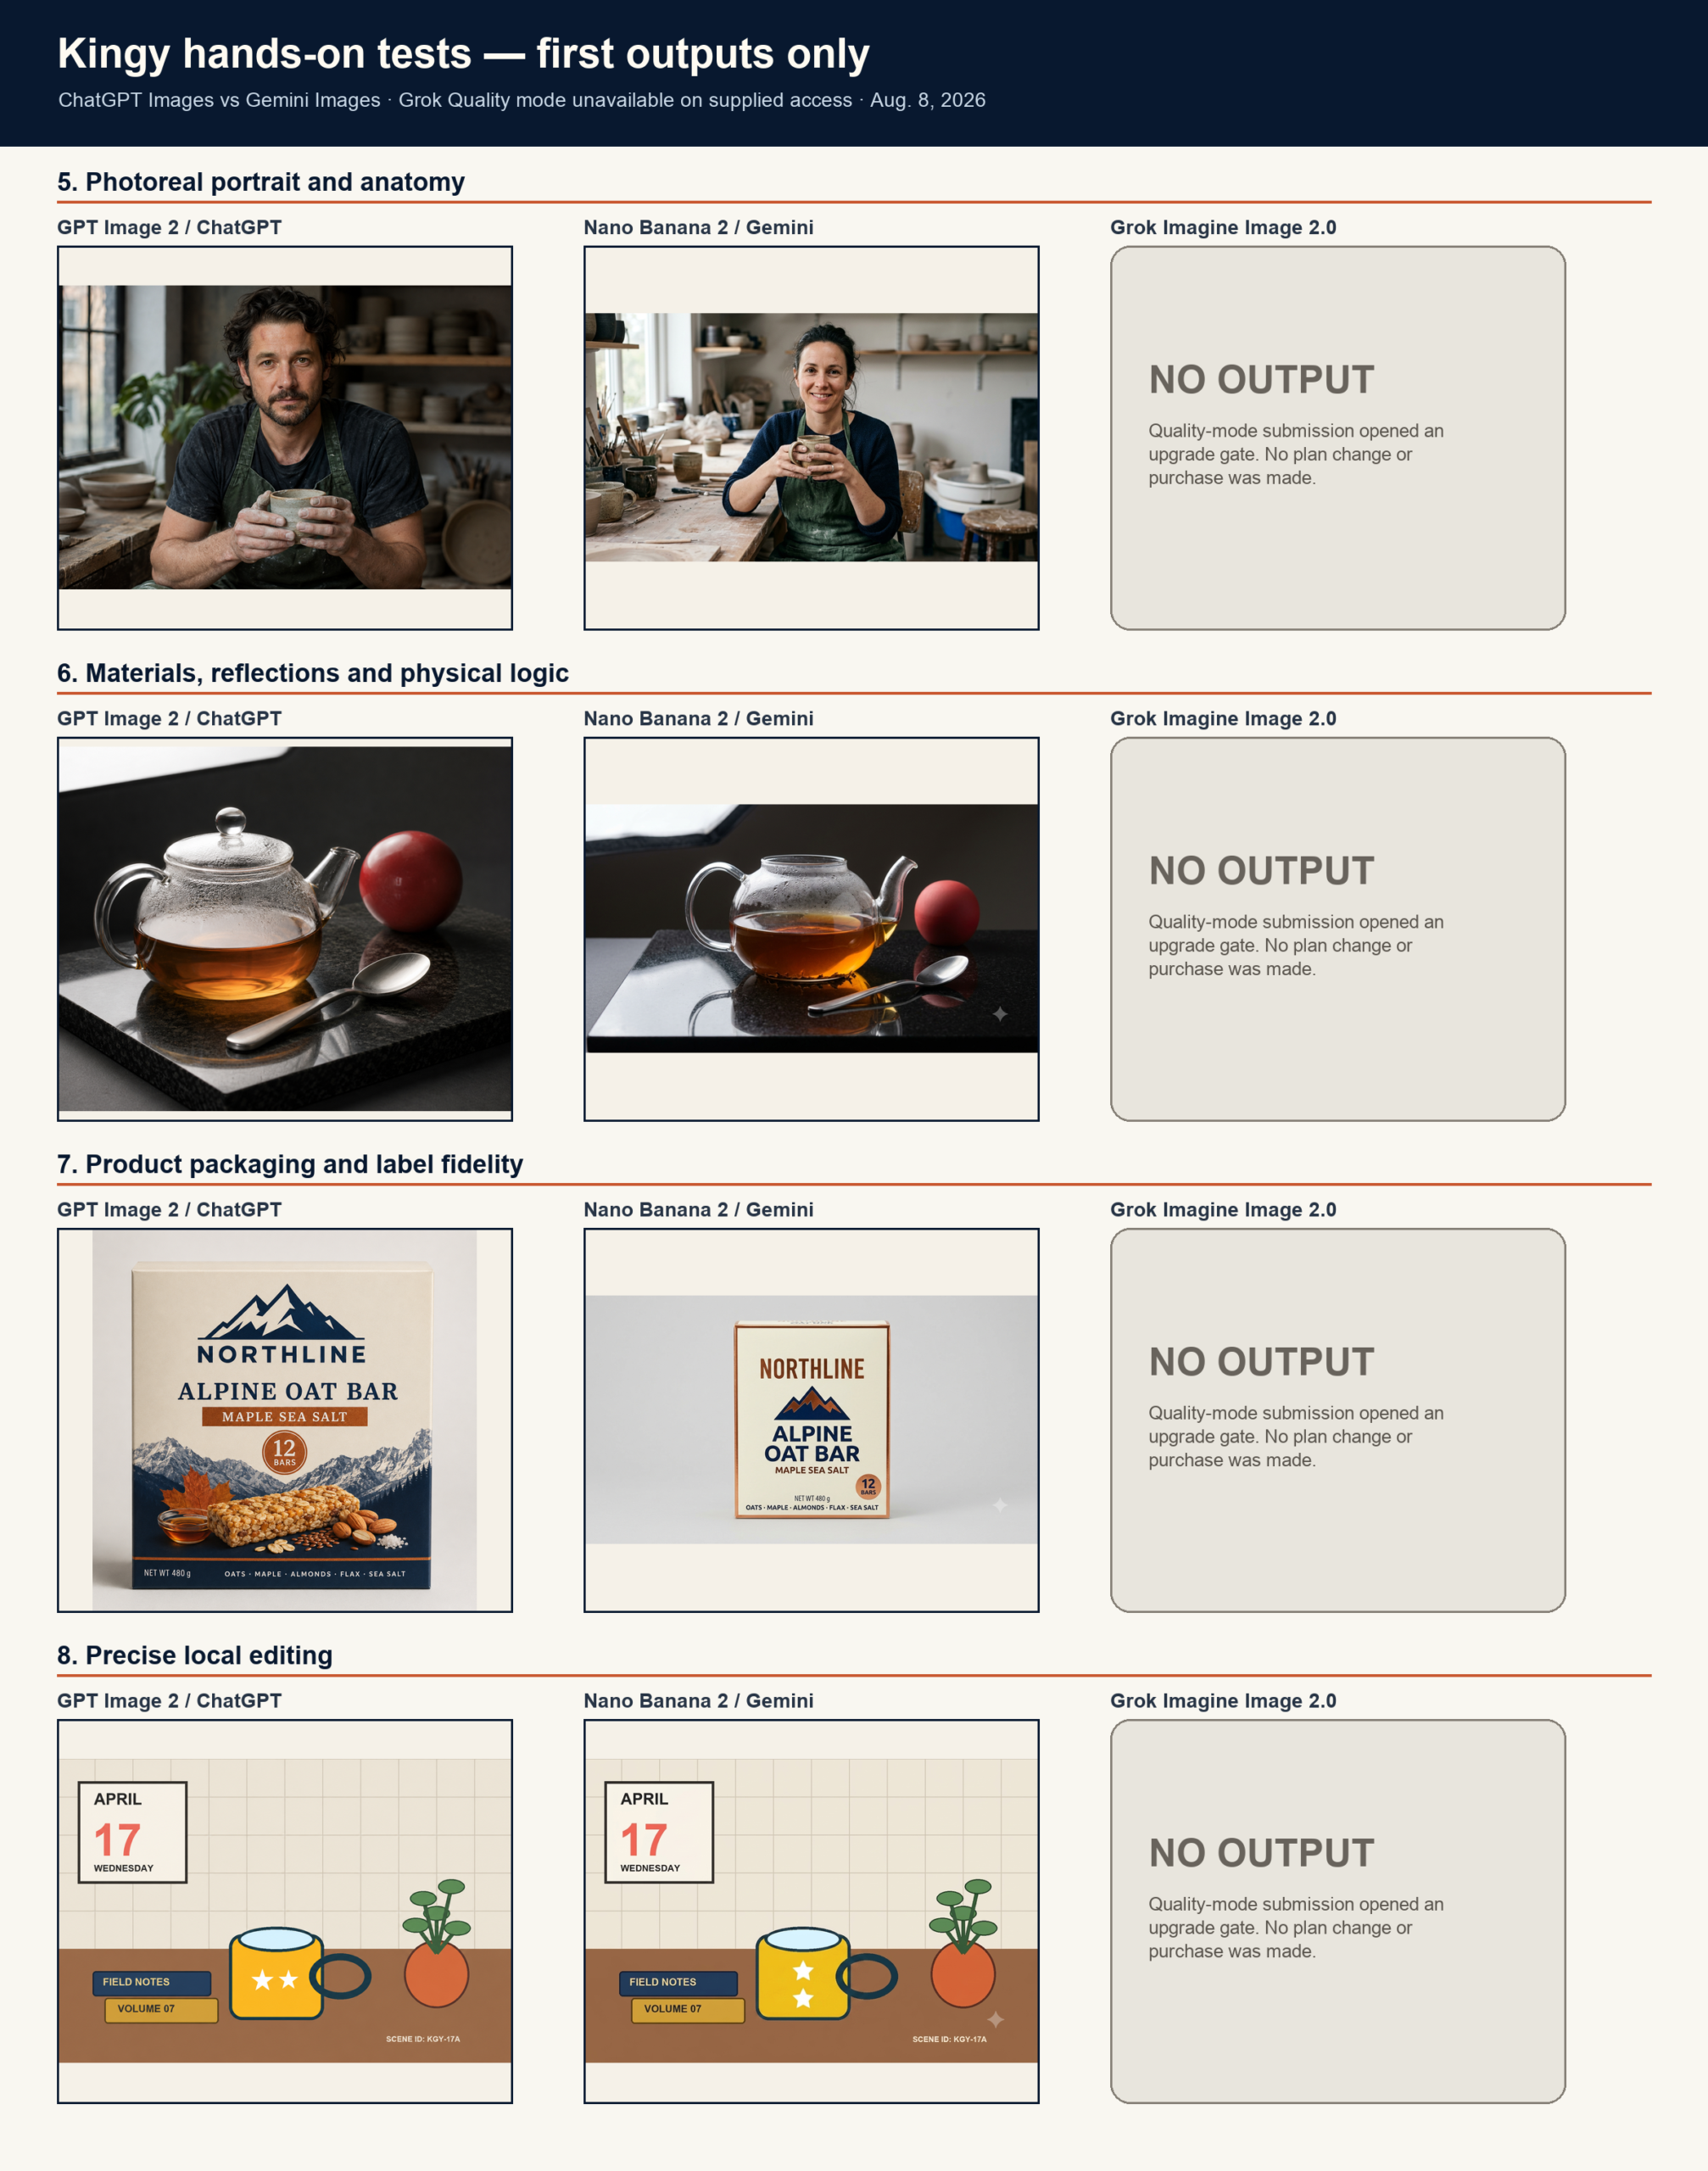
GPT held a modest but consistent lead in the portrait and materials tests. Its potter portrait looked less staged, while glass, condensation, tea and reflections formed a more coherent physical scene. Nano remained strong enough for concept work and social content.
Packaging was more decisive. GPT built a more integrated Northline Alpine Oat Bar identity and retained more requested label structure. That does not make either output legally production-ready: ingredients, weights, allergens and claims still require exact source artwork and human review.
Local editing was the uncomfortable result. Both systems performed the requested mug change, yet both regenerated surrounding pixels. GPT changed less and scored higher, but neither behaved like a deterministic layer editor. If unchanged regions must remain for compliance, product approval or version control, use a mask-based graphics tool and compare pixels—not just appearance.
Tests 9–12: preservation, consistency and outpainting
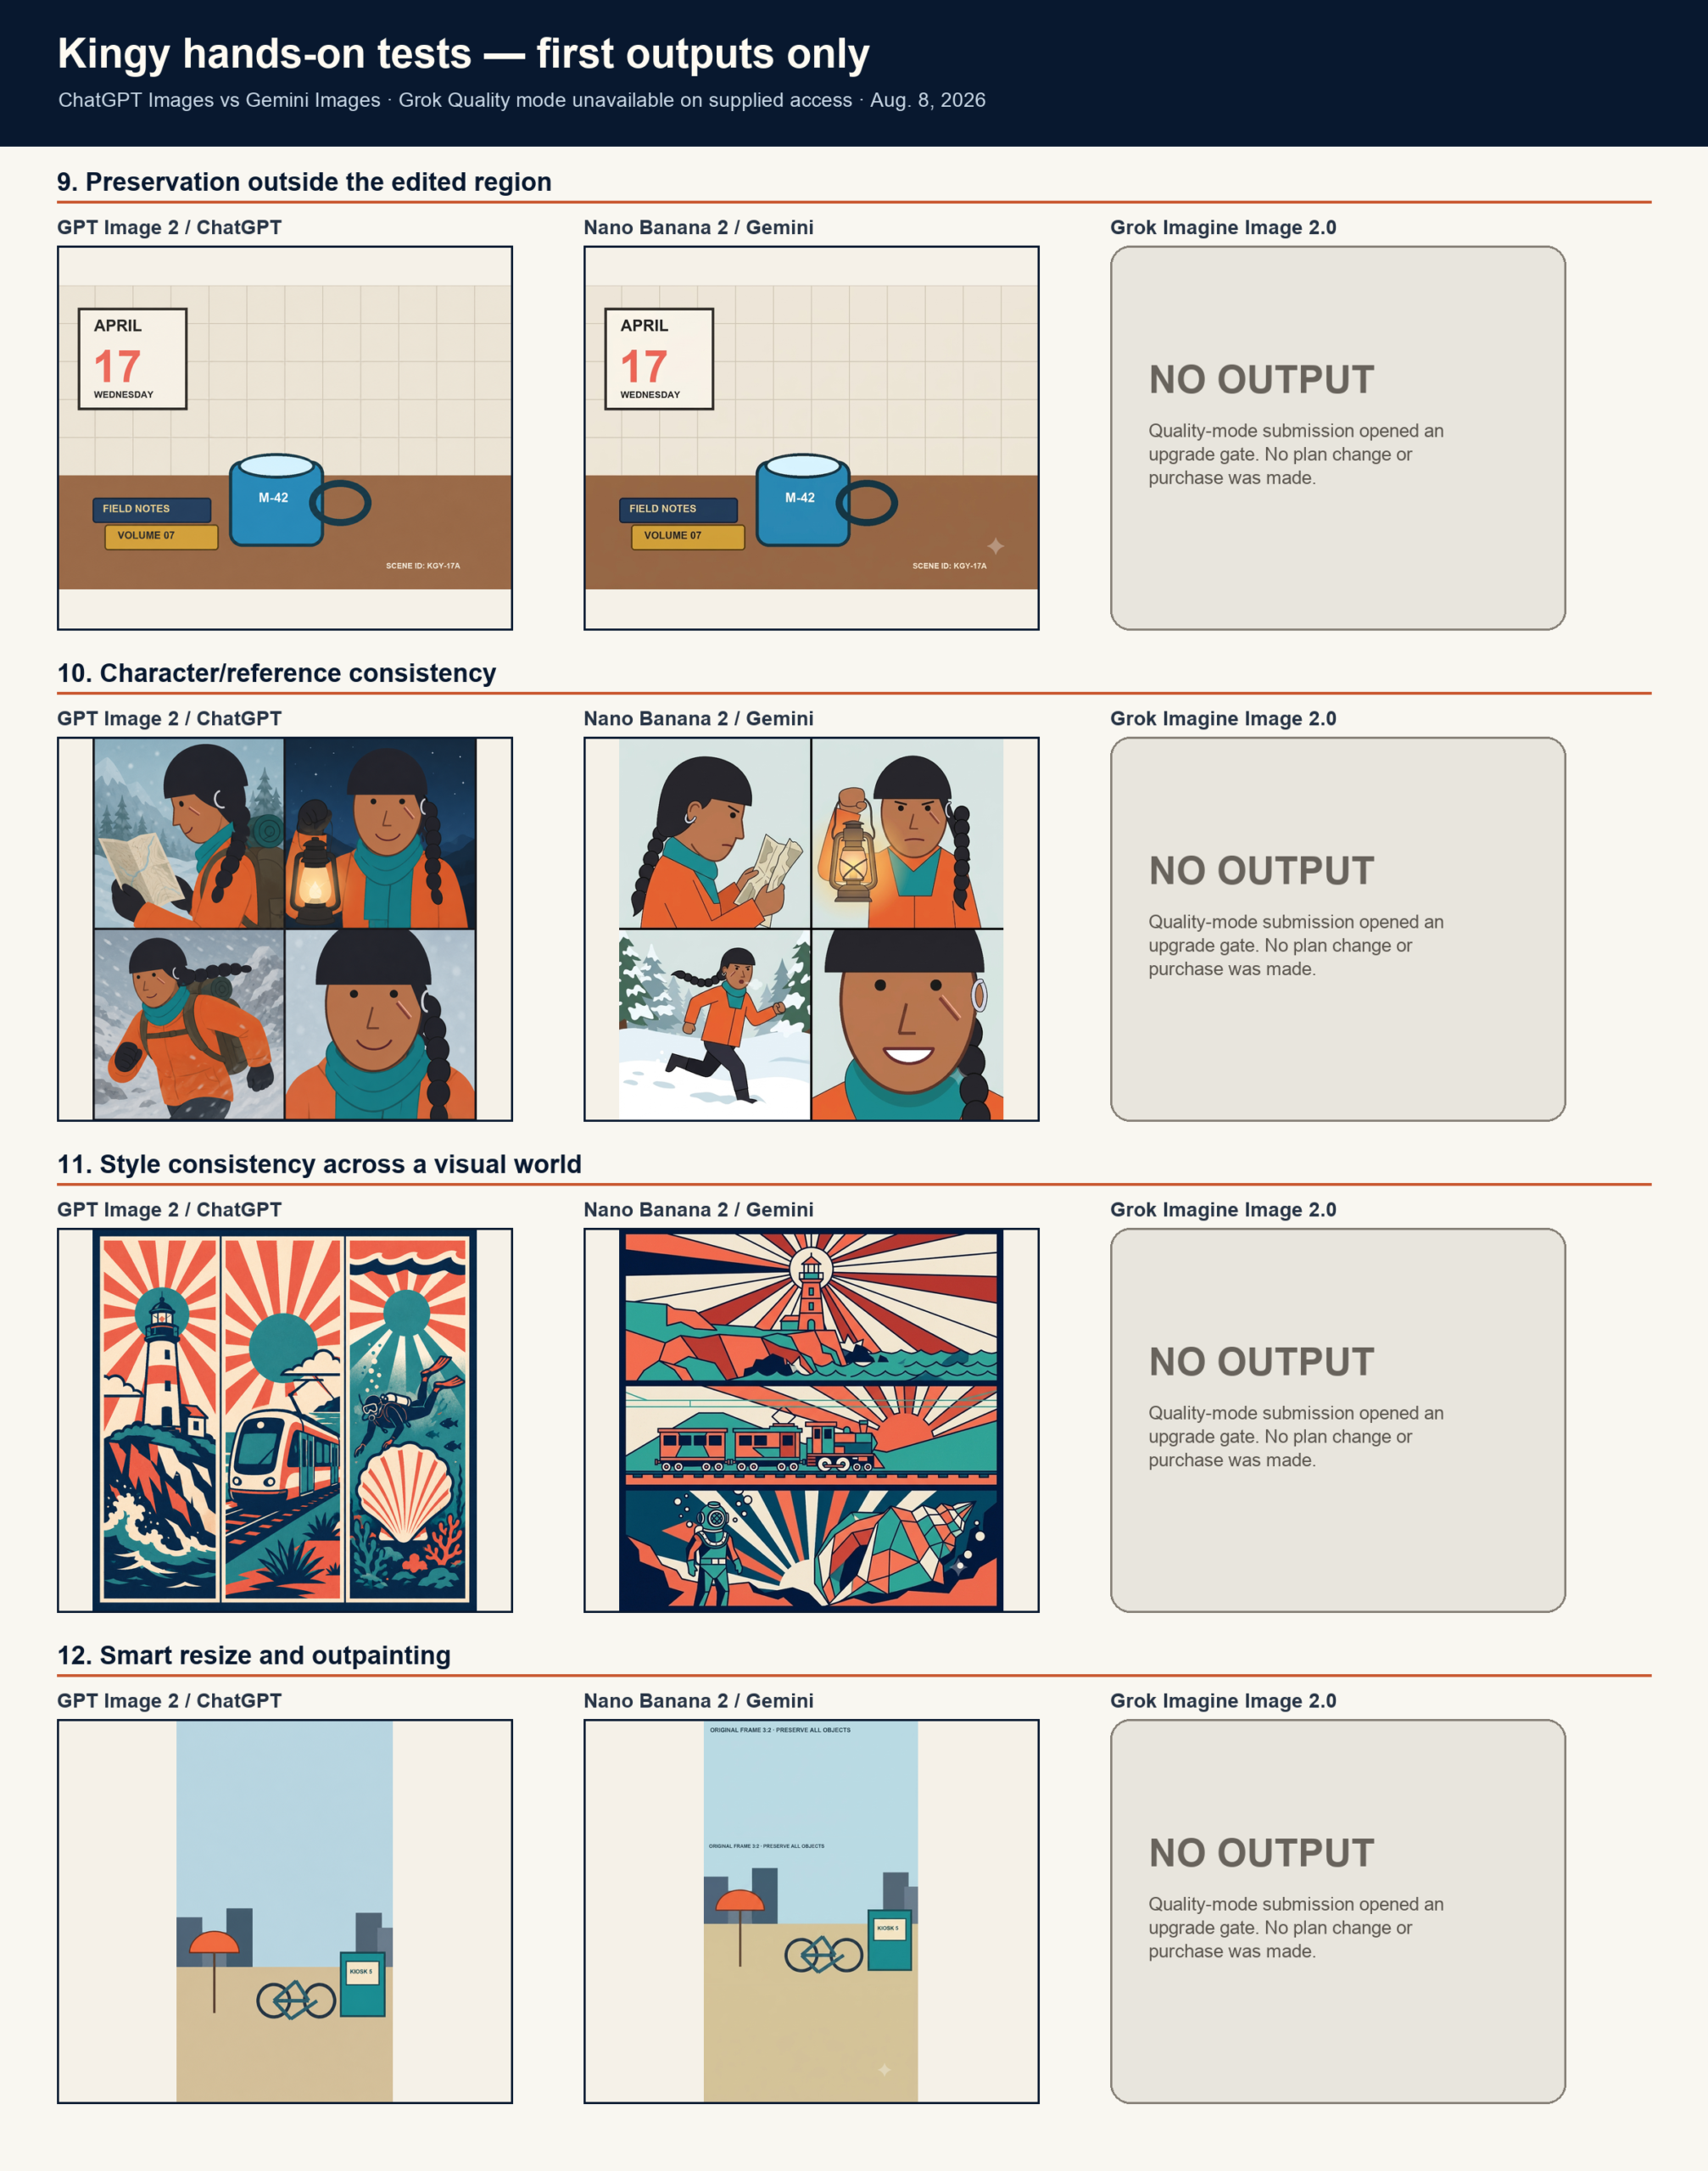
GPT’s strongest practical advantage was consistency. Across a four-panel character story and a multi-panel visual world, it better preserved costume, face, palette, shapes and layout logic. Nano remained usable, but drifted more.
Outpainting reversed the result by 0.27 points. Nano preserved more of the original scene, while GPT removed a source header. Nano also duplicated a header and added an unrequested sparkle. The honest winner is “Nano, narrowly—and still inspect every seam.”
Six repeats: consistency without cherry-picking
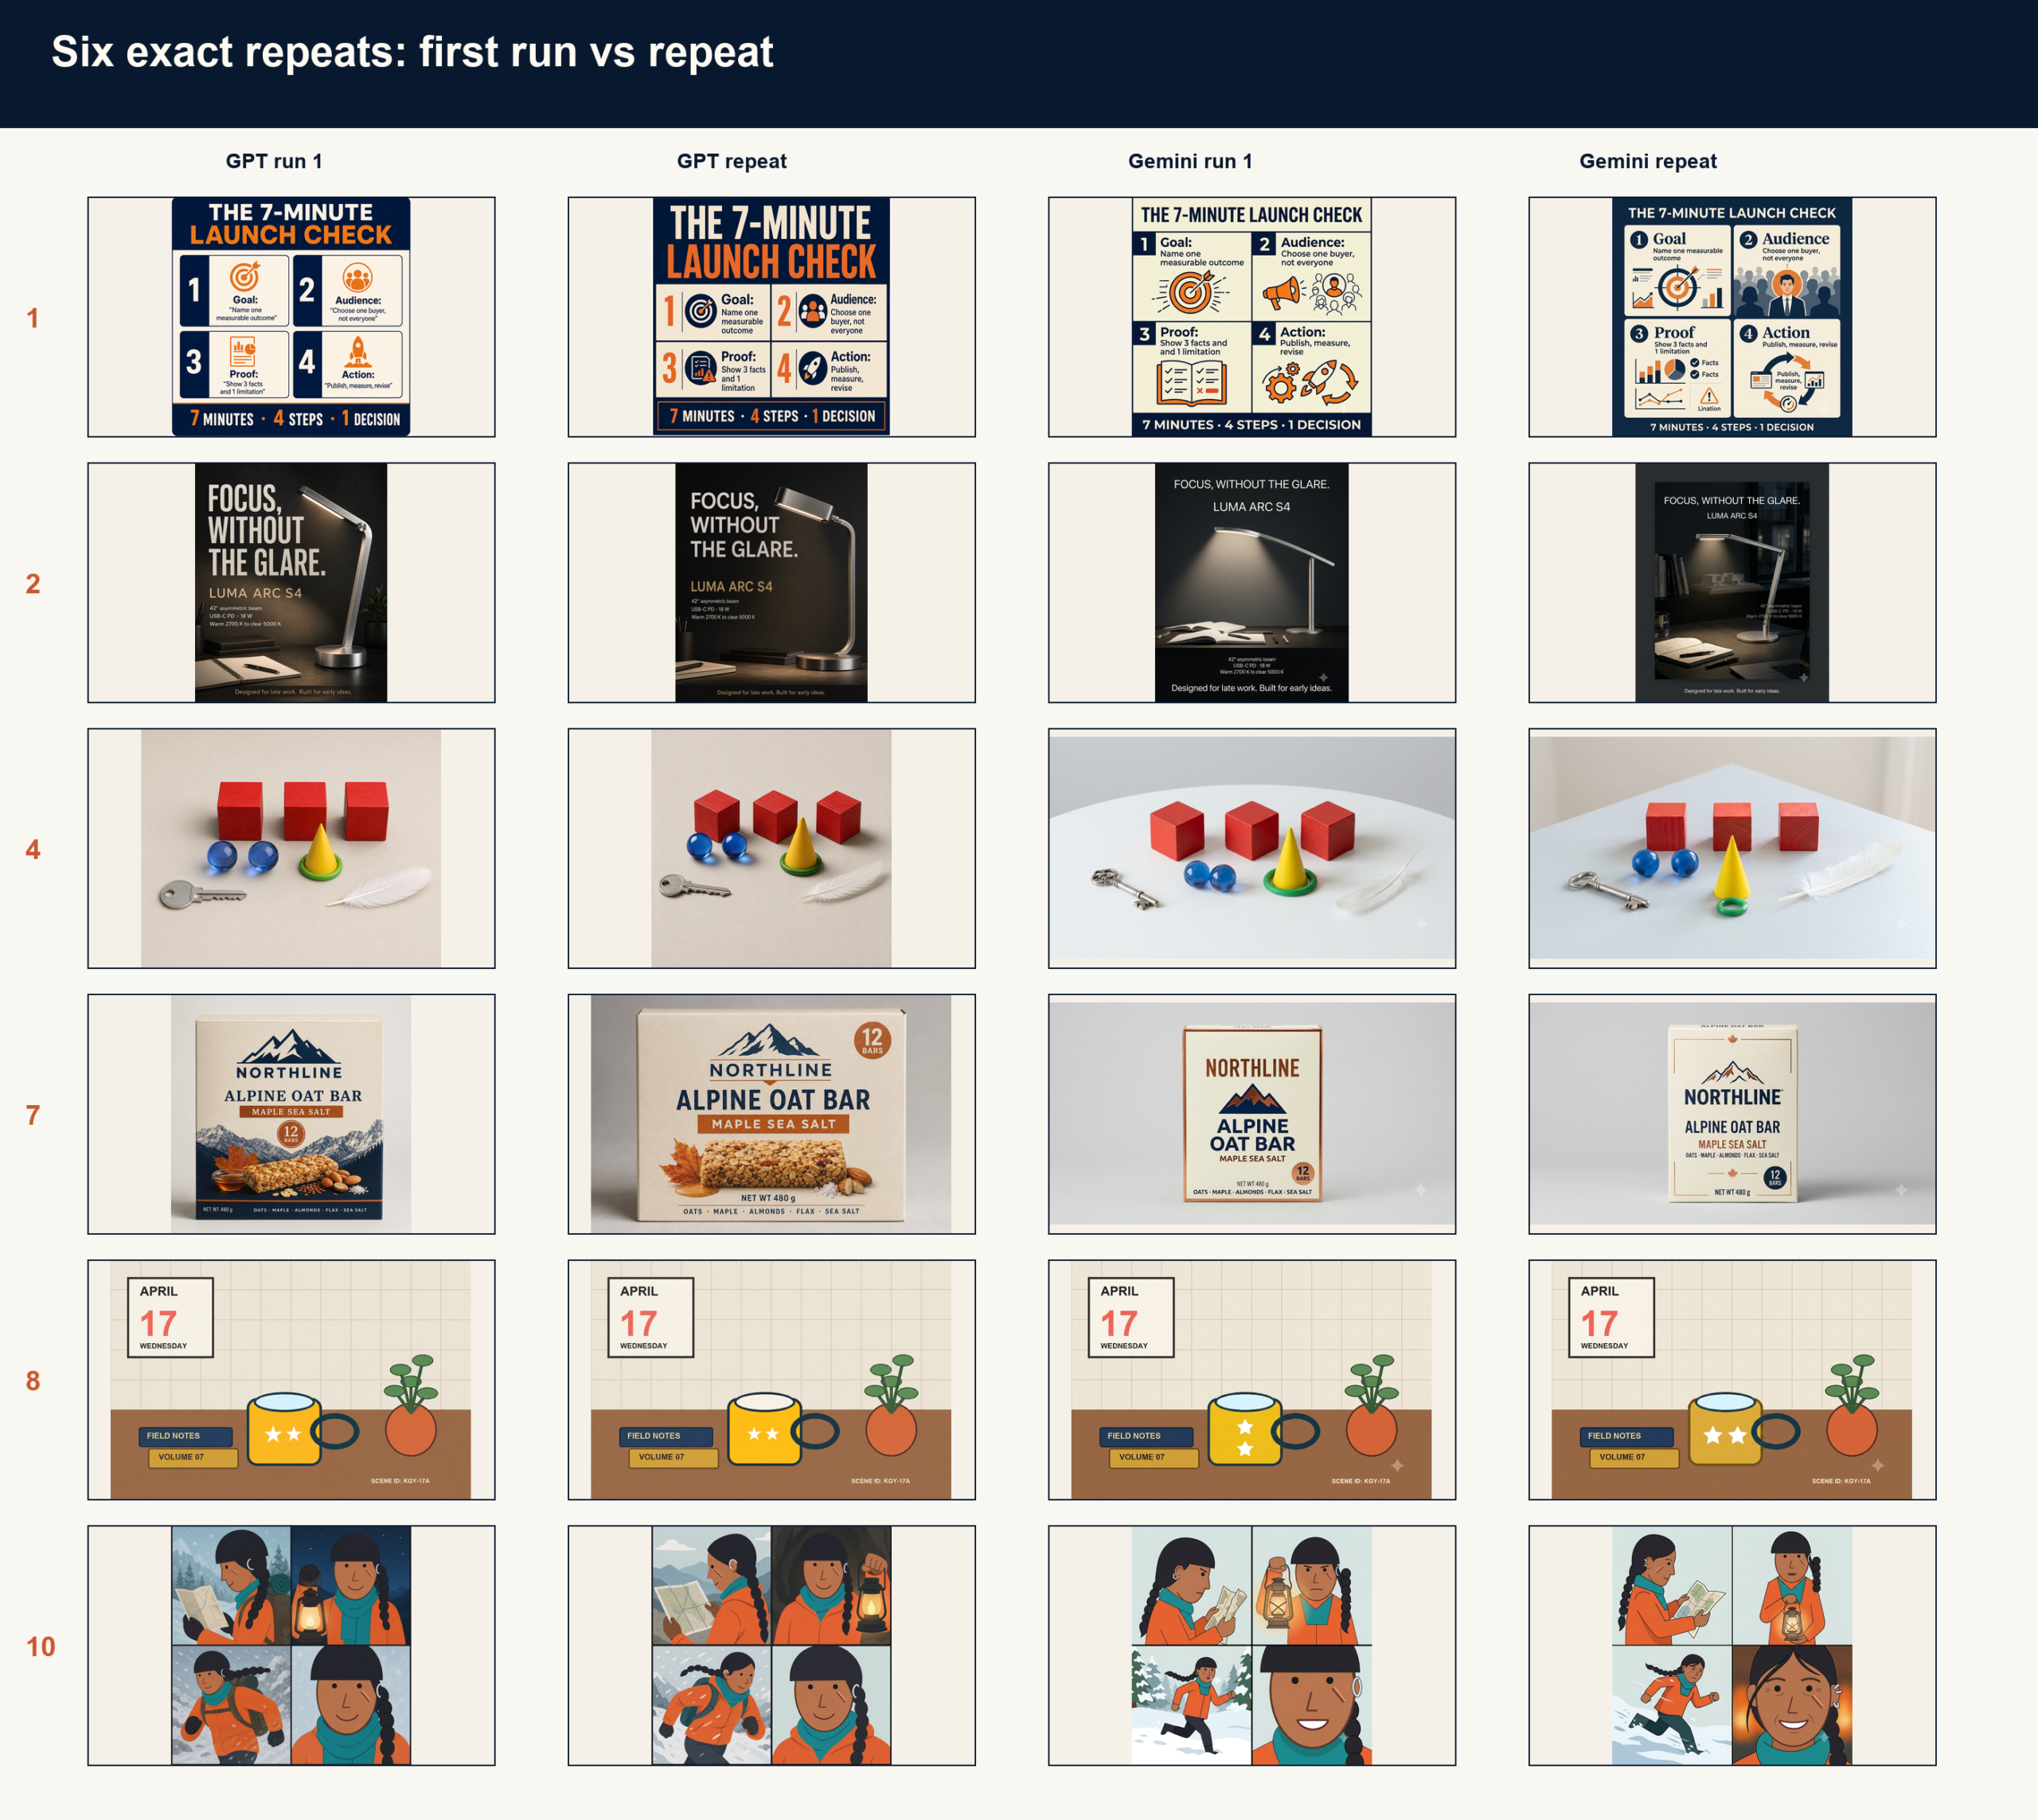
Neither model is deterministic. The repeat sheet shows substantial changes in composition, product angle, fine print and character panels. GPT more often preserved the requested information structure across runs; Nano more often changed the visual interpretation. Teams should budget for review even when a first run succeeds.
Reliability was excellent for both: 18/18 common and repeat jobs completed. Nano’s recorded median was approximately 14.5 seconds, compared with 34.6 seconds for GPT. One Nano preservation edit took 48.2 seconds, but its typical interaction still felt much faster.
Feature-ceiling tests
13. Grok five-reference compositing: blocked before output
xAI says Imagine Image 2.0 can combine up to five inputs. We prepared five controlled references and submitted the task in Quality mode. The signed-in consumer account opened a paid upgrade dialog before generation. Per the test rules, we did not upgrade and did not substitute another service.
So the result is unavailable, not “failed,” and certainly not a quality score. xAI’s official examples below show vendor-provided creative range, not our compositing result.
14. Transparent-background removal: GPT produced alpha; Nano did not
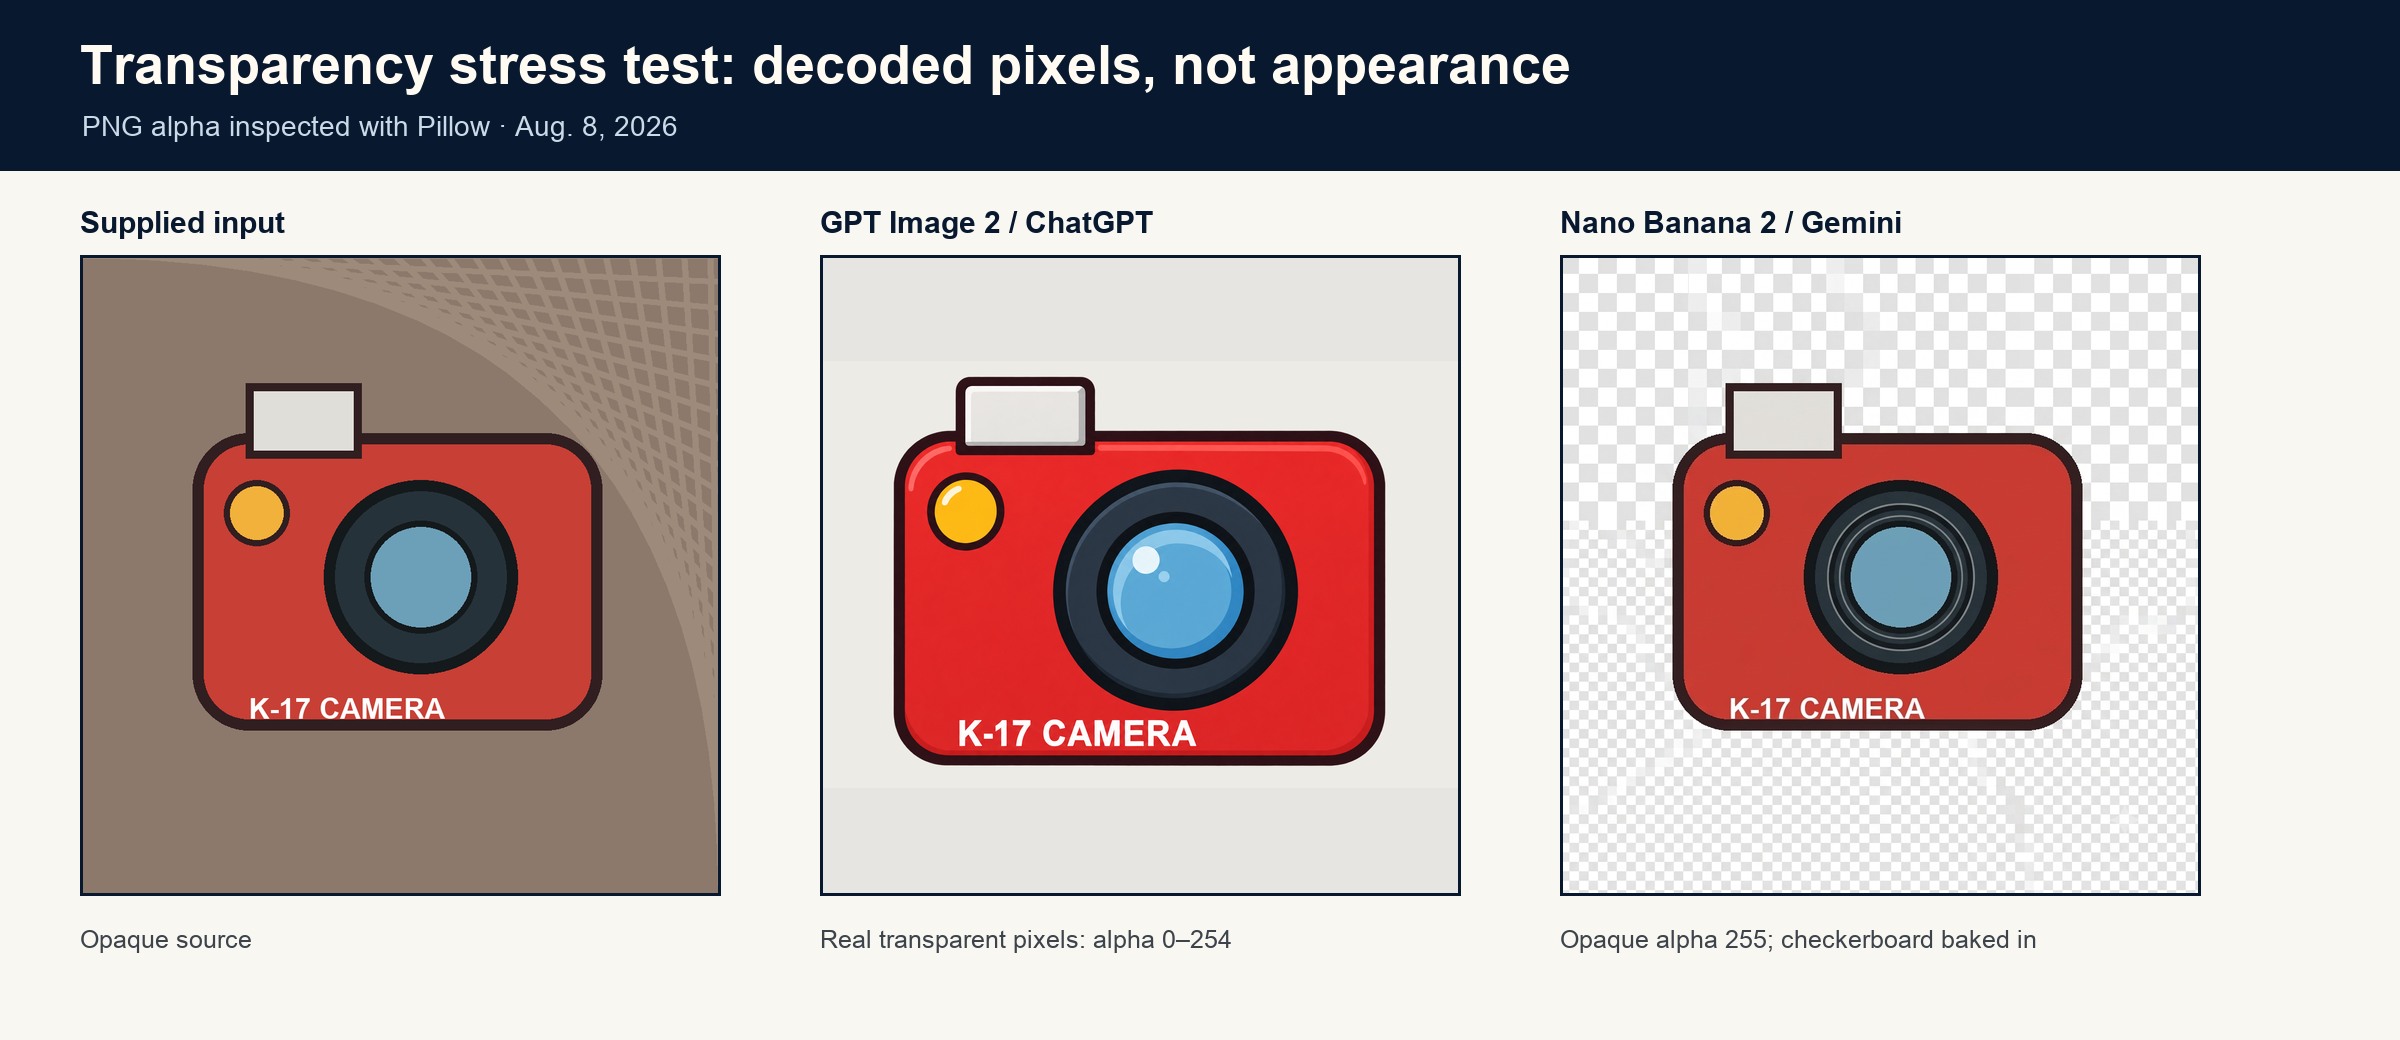
This finding needs a product/API distinction. OpenAI’s GPT Image 2 API guide says transparent backgrounds are not supported for GPT Image 2. Yet our ChatGPT consumer product download contained real transparent pixels. That is an observed product behavior, not proof that the API supports alpha. GPT also redrew the supplied camera and added edge effects, so “transparent” did not mean “unchanged cutout.”
Nano’s output looked transparent at a glance, but the checkerboard was baked into opaque pixels. Visual inspection alone would have produced the wrong conclusion.
15. Each rival’s strongest exclusive workflow
For GPT, we tested a multi-turn refinement ending with a 4K request. The conversation preserved the concept, but the downloaded file was 1536×1024—not 4K. For Nano, we used its Google Search-grounded image workflow. It returned a polished 1024-pixel infographic quickly, but the consumer UI surfaced no citations in the image response. Both workflows were useful; neither fully met the ceiling claim under our exact test.
Exploratory appendix: Grok Free/default Speed mode (unscored)
This appendix is not part of the scored comparison. After the protocol, we checked whether the supplied Grok Free account had an alternative to the Quality gate. At August 8, 2026, 20:03 PDT, Grok showed Image mode, Speed selected and 1:1. No model ID was disclosed, so we do not label this run Image 2.0.
We submitted the exact pre-registered Test 1 prompt once, with no input and no reroll. Grok navigated to #subscribe and opened “Upgrade to SuperGrok” before an image appeared. The gate was captured 16.2 seconds after submission—time to confirmed blocking, not generation latency. No output or dimensions exist.
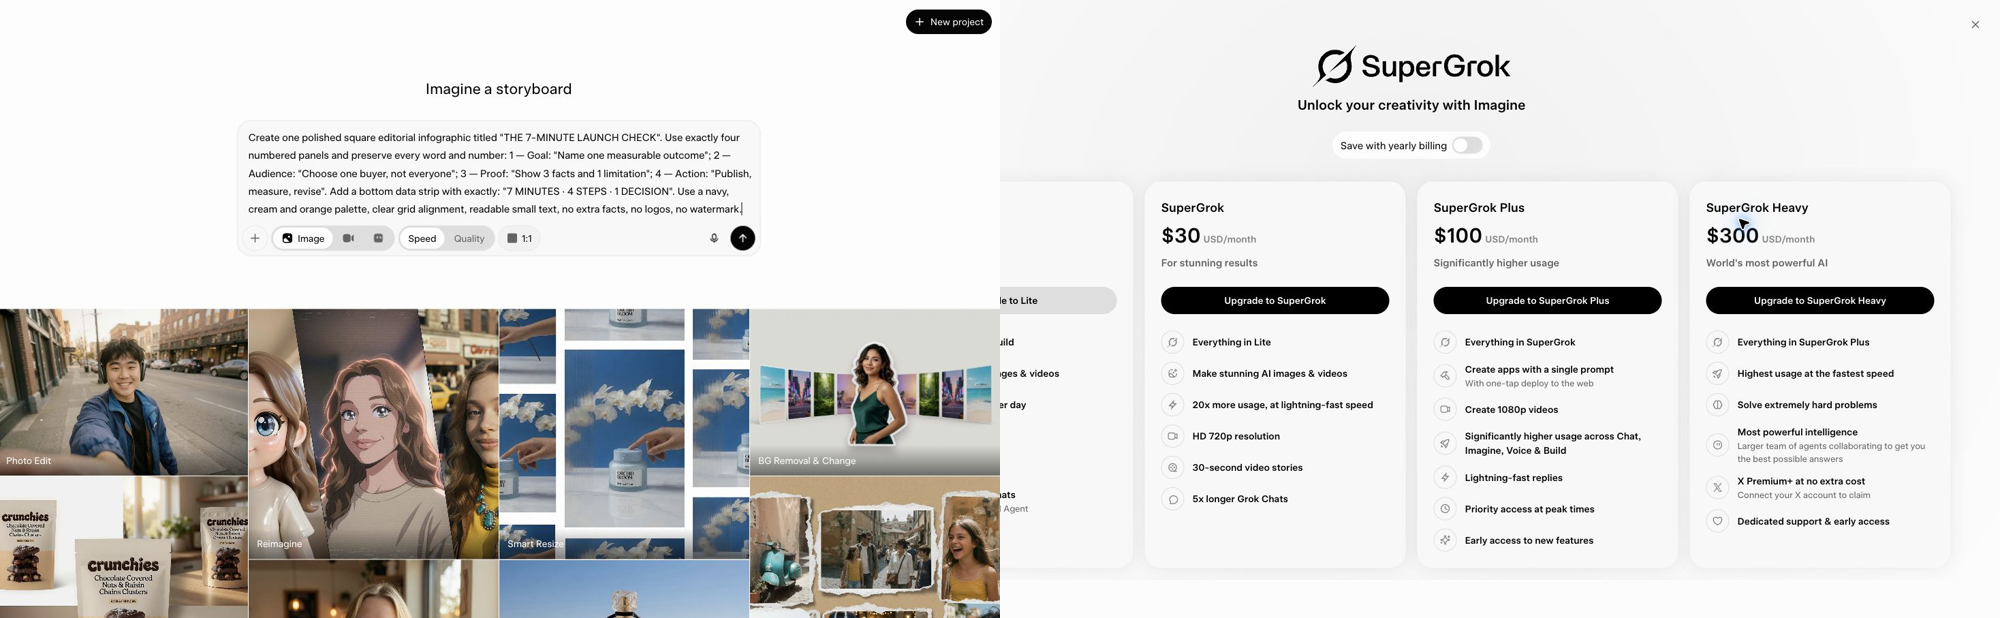
The five-reference upload could not be completed through the browser’s file-permission layer—an automation limitation, not a Grok finding—so we used the no-input common prompt. The conclusion is narrow: on this account at this timestamp, Speed was not a free route around Quality’s gate. It says nothing about output quality, universal availability or the model that would have served the request.
Follow-up: Grok Quality completed Test 1 (unscored)
After publication, at August 9, 2026, 20:27 PDT, we signed into Grok Imagine, selected Image, Quality and 1:1, and submitted the exact frozen Test 1 prompt once. Completion was observed after approximately 28.6 seconds. The interface returned two assets despite our one-output protocol, so we preserved the first displayed asset and did not choose between them or use Generate More.
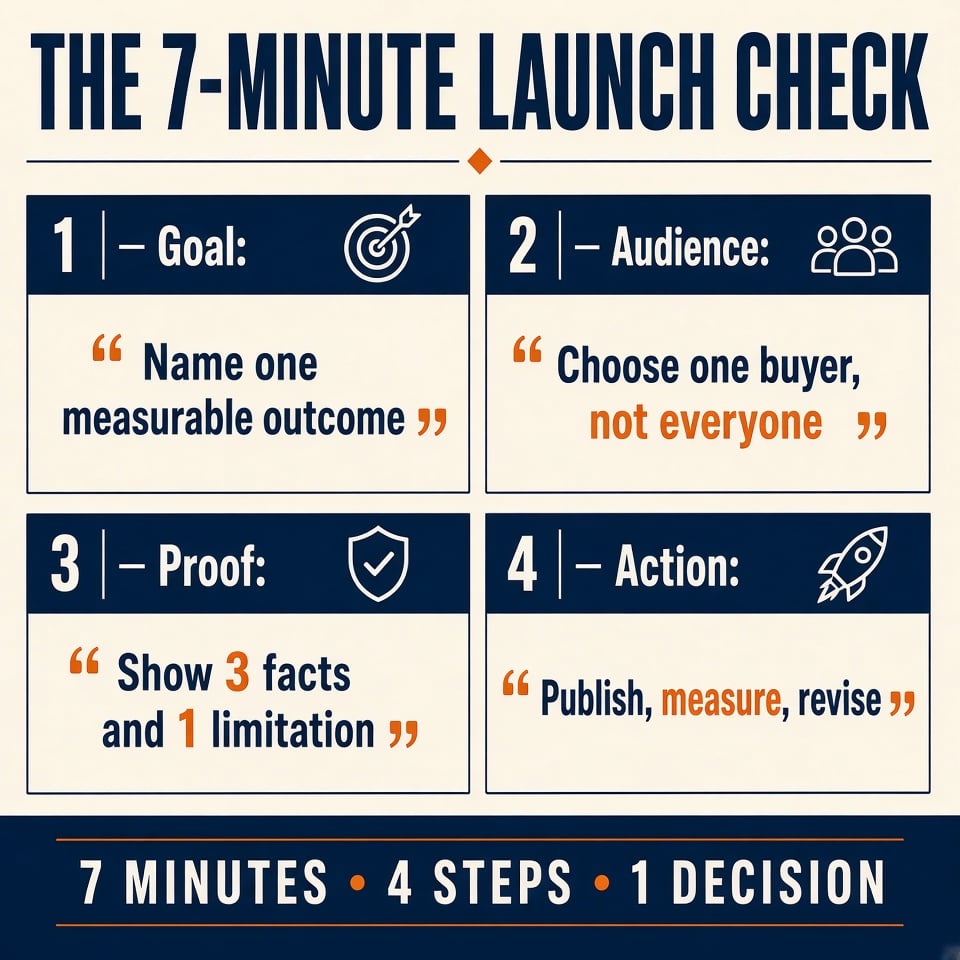
The first image visibly preserves the requested title, four numbered panels, quoted panel copy, bottom data strip and navy/cream/orange palette. It is a successful Kingy hands-on output. The consumer page exposed Quality but no raw model identifier, so this verifies the signed-in Grok Imagine Quality workflow—not a new API model ID.
This follow-up does not revise the 88.0/83.9 score. Grok did not complete the other eleven shared workflows, six frozen repeats or applicable feature-ceiling tests under the original cutoff, and the two returned assets also differed from the protocol’s requested single-output behavior.
Specs, access and pricing
All prices and access claims below were checked August 8, 2026, 18:07–18:46 PDT. Consumer subscriptions and API usage are different products.
| Model | Tested access | Consumer access | API status and price at the August 8 cutoff | Practical note |
|---|---|---|---|---|
| Grok Imagine Image 2.0 | Original Grok Free checks: Quality and Speed gated; signed-in Quality follow-up completed Test 1 on August 9 (unscored; raw model ID undisclosed) | Free $0; SuperGrok $30/month on xAI pricing page | API “coming soon”; no 2.0 API price published | Do not use older grok-imagine-image-quality price as a proxy |
| GPT Image 2 | ChatGPT Pro web | Tested Pro: $200/month, subject to guardrails | gpt-image-2; $8/M image-input tokens, $30/M image-output tokens; output examples $0.006 low, $0.053 medium, $0.211 high at 1024² | Flexible sizes; official API docs say no transparent background |
| Nano Banana 2 | Gemini Free web | Free $0; Google AI Pro $19.99/month | gemini-3.1-flash-image; $0.50/M input, $60/M image output; $0.067 at 1K, $0.101 at 2K, $0.151 at 4K | Supports image grounding and extreme ratios in official docs |
At the August 8 source check, OpenAI identified the snapshot as gpt-image-2-2026-04-21. Google identifies Nano Banana 2 as gemini-3.1-flash-image, updated July 21, 2026. For more background, see our GPT Image 2 release analysis and Kingy’s Nano Banana 2 launch coverage.
What the original report recommended at the August 8 cutoff
The following choices summarize that historical test, not current model rankings, availability, or pricing.
| If your priority is… | Use | Why |
|---|---|---|
| Final text-heavy marketing creative | GPT Image 2 | Best blind score and strongest typography/packaging result |
| Rapid ideation at high volume | Nano Banana 2 | More than twice as fast in our recorded median |
| Character sheets or branded visual worlds | GPT Image 2 | Better reference and style continuity |
| Cheap API-first iteration | Nano Banana 2 | Lower listed 1K image price than GPT medium 1024² |
| A true alpha PNG from the tested consumer surfaces | GPT Image 2 | Only tested download contained genuine transparency |
| Search-informed visual drafting | Nano Banana 2 | Native grounding workflow, but verify facts and citations separately |
| Five-reference compositing or Magic Wand editing | Grok, only after workflow-specific verification | One text-to-image follow-up succeeded; five-reference compositing and Magic Wand remain untested by Kingy |
| Compliance-critical local editing | Neither alone | Both regenerated outside the target region |
| Broad market shopping | See Kingy’s top-five image generator guide | This article intentionally covers only three models |
Limitations
The original report described an editorial test, not a laboratory claim of universal superiority. Its underlying test files were not recovered in this review, so present-day reproducibility has not been verified. Consumer surfaces can route models, change defaults or impose plan limits without exposing every parameter. ChatGPT did not display a raw model ID in the conversation UI; Gemini explicitly labeled the tool Nano Banana 2; Grok explicitly showed Quality mode but gated the original submission. Its later Speed-mode appendix also exposed no model ID. The August 9 signed-in Quality follow-up completed Test 1, but the consumer page still exposed no raw model identifier.
Three graders reduce individual taste, but the sample remains 12 shared workflows and one first output per run. Arena has far more votes but a different task and population. Grok’s new listing is preliminary and has fewer votes. Prices, plans and ranks can change after the timestamp.
Most importantly, we did not turn one later Grok output into a retrospective score. That preserves the original score boundary and the separately reported follow-up; it does not establish that the unrecovered original run can currently be reproduced.
FAQ
Did the August 8 evidence show Grok Image 2 was better than GPT Image 2?
No. The August 8 Arena snapshots ranked GPT first and Grok second on both boards. Kingy’s original Grok comparison was blocked because Quality mode triggered an upgrade gate, and the later Speed-mode check was also gated. A signed-in Quality follow-up subsequently completed Test 1 and produced a strong-looking infographic, but one unscored output is not enough for a direct Kingy quality verdict.
Is there a free alternative to Grok Quality mode?
Not on the supplied Grok Free account at our August 8, 2026, 20:03 PDT check. The visible Speed mode accepted the prompt but opened the SuperGrok upgrade dialog before generating. A later signed-in Quality run succeeded, but that does not establish that free Speed is generally available. Availability can vary by account, region and time, so verify your own access before planning a workflow.
Did GPT Image 2 beat Nano Banana 2 for editing in the original test?
In the original report’s runs, GPT won local editing and preservation, though both regenerated outside the target region. Nano narrowly won outpainting. For pixel-critical edits, neither should replace a mask-based editor and diff check.
Which model did the original report rate highest for text in images?
The report said GPT Image 2 won the dense infographic and narrowly won multilingual typography; it called the small-text ad a tie. All generated text still needs proofreading before publication.
Which model was fastest in the original report?
The article reported Nano Banana 2 as faster in its consumer-web runs: approximately 14.5 seconds median versus 34.6 seconds for GPT across the reported common and repeat jobs. The timing logs were not recovered in this review. Platform load can change that result.
Does Grok Image 2.0 have an API price?
No price was published at our August 8, 2026 cutoff. xAI’s launch post says API access is coming soon. The older grok-imagine-image-quality API is a different model and should not be used as a pricing stand-in.
Can GPT Image 2 create transparent PNGs?
At the August 8 cutoff, the official API guide linked in the article said GPT Image 2 did not support transparent backgrounds. However, our ChatGPT consumer test downloaded a PNG with real alpha pixels. Treat that as observed consumer-product behavior, not an API guarantee.
Original research and scoring cutoff: August 8, 2026, 20:03 PDT. Follow-up access/output check: August 9, 2026, 20:27 PDT. Evidence labels: the article attributes xAI/OpenAI/Google capability statements to vendors and preserves Arena ranks as dated third-party snapshots. Scores, timings, files and alpha checks are reported as Kingy hands-on results from the historical article; underlying files were not recovered in this review. The story-specific featured image is illustrative and is not benchmark evidence. The Grok Speed-mode appendix and later Quality follow-up are exploratory evidence and are excluded from scoring.
Buying details checked October 22, 2026: Nano Banana 2 buying profile: This is Nano Banana 2, not 2.1. API free-tier generation is not listed; consumer access and historical timing are separate. The original article keeps its existing dates and evidence scope; the linked profiles describe their own demonstrations.