Qwen3.8-27B Runs on a Laptop—But Here’s the Hardware You Actually Need
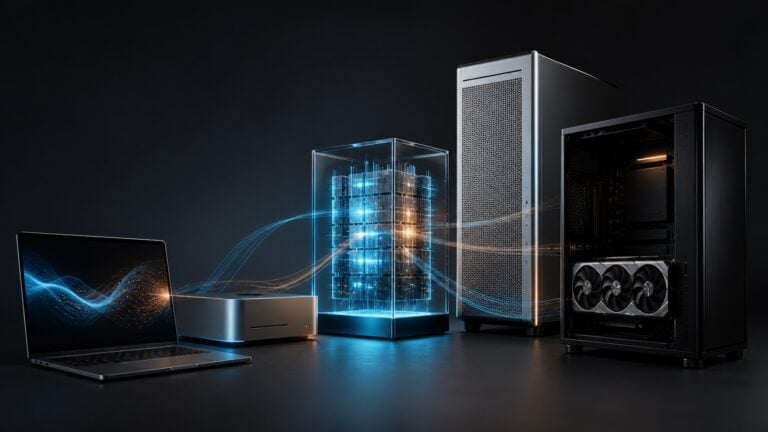
Yes, Qwen3.8-27B runs locally on a laptop—but 24GB is the fit-first minimum, 32–48GB is the practical sweet spot, and an RTX 5090 is the speed choice, not a requirement.
Qwen3.8-27B may be the new dense open-weight model to beat around 30 billion parameters. This evidence-led launch guide audits the benchmarks, calculates local-memory requirements and compares current open and frontier alternatives.
GLM-5.3's full FP8 and BF16 weights are live. Kingy verifies checkpoint sizes, licenses, hardware requirements, downloads, vLLM setup, API pricing, and why Ox Alpha became GLM-5.3-Flash—not full GLM-5.3.
GLM-5.3’s weights are delayed for safety testing. We audit Z.ai’s cyber benchmarks, 2,436-finding ledger, disclosure status and attribution.
GLM-5.3 wins the vendor-reported race, DeepSeek V4 Pro 0813 wins the endpoint crown, and Kimi K3 wins on downloadable weights. Here is the source audit.
OpenAI's Mac feature turns interaction events into memories for ChatGPT and Codex, but cloud processing, unencrypted local files, and prompt injection make selective access the sensible default.
Daily Kingy AI Launch Radar for 2026-08-13: source-checked AI launches, product updates, pricing notes, use cases, and risks worth watching.
Google’s new Flash model makes its biggest gains in coding, agents and documents while keeping the same million-token context and a low promotional price.
Claude Opus 5 leads on public evidence, GPT-5.6 Sol is the strongest tool-rich generalist, and Grok 4.6 is the provisional value leader.
DeepSeek V4 Pro 0813 is live, but its Fable 5 claim needs context: vendor benchmarks, 1/57 output-only pricing, cache differences and unconfirmed 0813 weights.