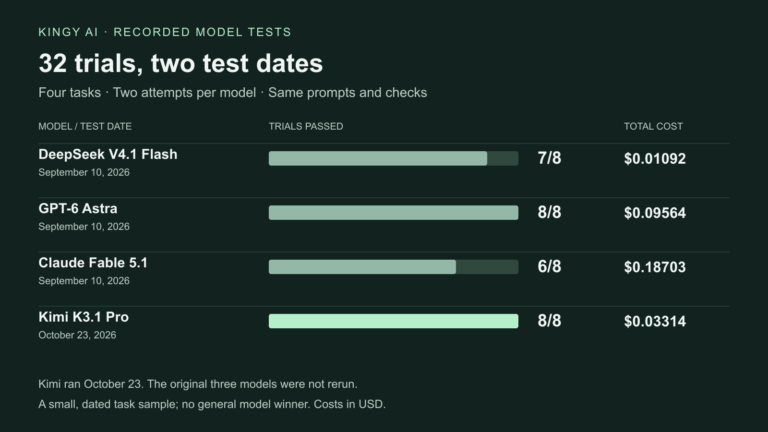
Kimi K3.1 Pro passed 8/8 for $0.03314 on October 23. The September 10 results remain GPT-6 Astra 8/8, DeepSeek 7/8 and Claude 6/8. Compare the same four tasks, measured costs and separately dated evidence.
Relationship not stated
Scope and disclosure
32 trials: 24 from September 10, 2026 plus eight Kimi trials from October 23. Four tasks, two attempts per model. Original models were not rerun.
Commercial relationship not stated. Check the article or video disclosure.
Original summary wording
Kimi K3.1 Pro passed all eight trials for $0.03314 on October 23, 2026. Compare its measured results with the September 10 DeepSeek V4.1 Flash, GPT-6 Astra and Claude Fable 5.1 tests.
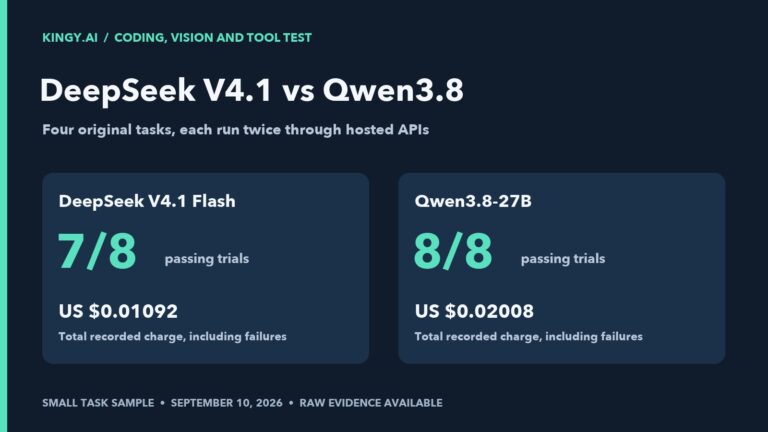
Qwen3.8-27B passed 8/8 trials for $0.02008; DeepSeek V4.1 Flash passed 7/8 for $0.01092. Both passed the coding and chart tasks. Compare the hosted results and one DeepSeek tool failure; local hardware is a separate question.
Relationship not stated
Scope and disclosure
The same eight DeepSeek trials appear in both comparison articles; the articles are not independent replications.
Commercial relationship not stated. Check the article or video disclosure.
Original summary wording
Qwen passed 8/8 trials; DeepSeek passed 7/8 at lower cost. Our small hosted test covers coding, chart reading, tool recovery and the separate local-hardware decision.
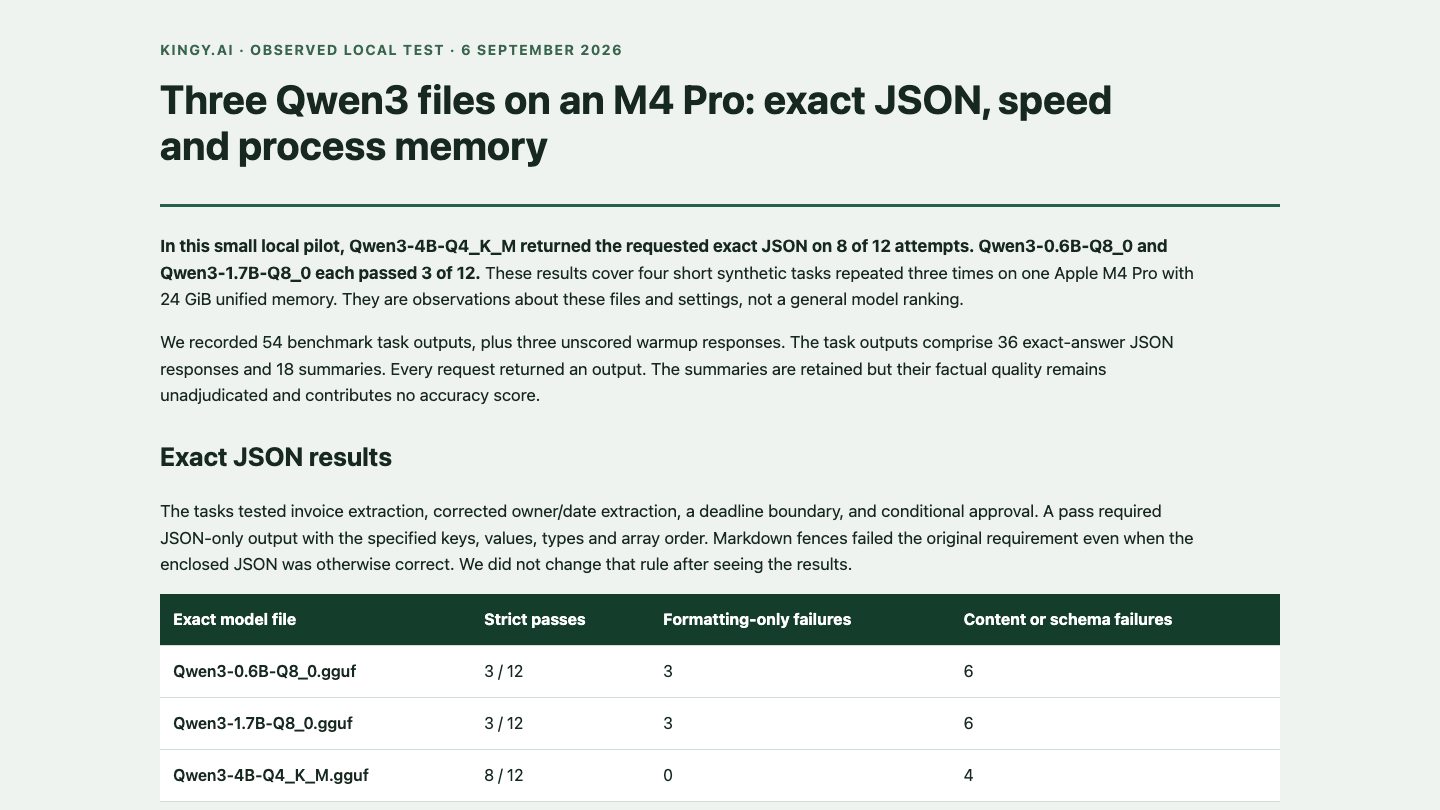
The tested Qwen3 4B file passed 8/12 JSON attempts; the 0.6B and 1.7B files passed 3/12 each. Provider charges were $0. Compare timing and mistakes on one M4 Pro. Different quantizations limit model-size comparisons; summaries remain unscored.
Relationship not stated
Scope and disclosure
A narrow local pilot: four JSON tasks repeated three times per model. Different quantizations limit model-size comparisons. The 18 retained summaries are unscored. Four JSON tasks were repeated three times per model. The 18 summaries are unscored.
Commercial relationship not stated. Check the article or video disclosure.
Original summary wording
Three exact Qwen3 files, four short JSON tasks, and saved outputs from an M4 Pro. Inspect strict passes, formatting failures, timings, and sampled process memory.
Proof Lab 01 found failures in all six August 26 clips under the later PL-01-v1 rules. Historical charges totaled US$1.81332. Watch the clips and inspect the damaged marks. The stricter rubric was written after generation; original usability labels remain unchanged.
Relationship not stated
Scope and disclosure
Inspect the saved attempts, method, and limits before applying these results to another task. The original brief allowed a 5–25% enlargement; the later rubric narrowed that to 10–20%. The original September 19 report and sharing video record the earlier four-failure/two-unresolved state. No new runs were made.
Commercial relationship not stated. Check the article or video disclosure.
Original summary wording
Proof Lab 01: six retained August 26 clips. A September 20 addendum documents six retrospective failures under the later PL-01-v1 rubric and zero certified strict passes. Original usability labels remain unchanged. Inspect the methods and files; no new runs.
Kingy-run experiments with saved outputs and a documented method. Small samples and failed attempts stay visible. Some articles share the same runs; entry counts are not independent experiment counts.
Video reviews & demos
Recorded reviews or workflows with an evidence companion. Demonstrated behavior and sourced claims have different limits; these entries are not automatically controlled benchmarks.
Source analysis
Comparisons and buyer reviews based on named sources. They may link to hands-on work, but the source analysis itself is not counted as a new experiment.
Commercial disclosure is a separate filter. “Product or access supplied” identifies a documented contribution; it does not establish cash sponsorship or affiliate terms. “No product sponsorship disclosed” reflects an explicit statement; a video may still include an advertisement. “Relationship not stated” is not a claim of independence. Dates describe the test, publication or source check shown. A separate “New test results” date identifies a later test extension; it does not mean the original models were retested or every claim was reviewed again.
This library brings together existing documented records and selected source reviews. The wider archives remain available below.