
Weight-release status checked October 28, 2026: The official upcoming-release page now gives October 29 as its expected date. This target can change; final downloadable weights and their license remain unverified. Earlier dated update notes below retain the ETA observed at those times.
Mistral Large 4 is a serious new contender for legal agents, finance workflows and European deployment. Its first independent results do not establish it as the strongest general-purpose model. The useful story is more specific: a trillion-parameter mixture-of-experts model, unusually promising specialist results, documented API pricing, and weights promised for later this month.
Update, November 16, 2026: Mistral released the open weights on October 29, 2026. See the open-weights update and whether you can run it at home.
Mistral announced the model, nicknamed Le Chonk, on October 6, 2026. It is available through the API in public preview. The announced open-weight release is scheduled for the end of October; Mistral’s Hugging Face upcoming-release page now lists October 29 as the current expected date. A downloadable release and final license were not available when we checked. That distinction matters for anyone budgeting a private deployment today. Official upcoming release
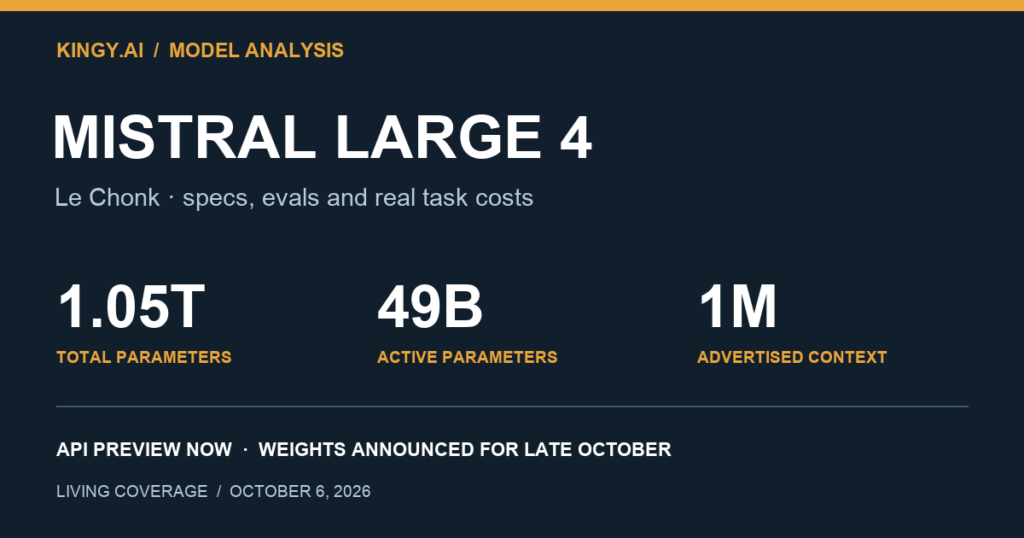
The headline numbers are 1.05 trillion total parameters, 49 billion parameters in active experts, or 52 billion including embeddings and output layers, a 1.6 billion-parameter vision encoder and a manufacturer-listed one-million-token context window. Mistral’s card and current announcement now use the inclusive 52B count; the announcement initially used 49B on October 6. The headline caveats are equally consequential: independent evaluators currently list roughly half the advertised context, benchmark configurations differ, and current API prices differ from the launch tariffs used in the first independent evaluations.
The verdict at launch
Large 4 earns a place on an enterprise evaluation shortlist. It has a credible case for document-heavy legal work, financial research and organizations that value Mistral’s European infrastructure. The evidence is weaker for choosing it as the default model for every coding or knowledge task.
On Vals AI’s broad industry index, it scores 48.05%, behind GPT-6 Astra, GPT-6.1 Sol, Claude Sonnet 5.5, Claude Opus 5.5 and several other competitors. On the much narrower Harvey Legal Agent Benchmark, it scores 15.83%, ahead of those four models in that particular test. Finance Agent v2 also gives it a small advantage over Astra, although other models score higher. A specialist win and a broad-index loss can both be true. Vals model profile
Mistral’s Standard API pricing, checked October 31, 2026, is $0.70 per million input tokens, $0.07 per million cached-input tokens and $2.10 per million output tokens. Initial evaluator snapshots used different launch tariffs. Their measured costs retain those historical rates. Mistral pricing
The most defensible buying decision is therefore workload-specific: test the legal or finance workflow you actually operate, against the same tools and acceptance criteria, while keeping a stronger generalist available for tasks where Large 4 falls short. The broad benchmark evidence gives little reason to replace an entire model stack on announcement day.
Mistral Large 4 specifications
| Item | What is currently established | Evidence and limits |
|---|---|---|
| Release | October 6, 2026; public API preview | Training and post-training are still developing |
| Architecture | Granular mixture of experts | Full architectural details have not yet been published |
| Total parameters | 1.05 trillion | Mistral’s launch post rounds this to 1T |
| Active parameters | 49B in active experts; 52B including embeddings and output layers | Card and current announcement use the inclusive 52B count; active compute is not the total memory needed to serve the model |
| Vision encoder | 1.6 billion parameters | Native multimodal model; supported inputs include text and images |
| Context window | 1 million tokens on Mistral’s card | Vals lists 512K; Artificial Analysis and Vercel’s live provider table list 524K; discrepancy remains unresolved |
| Maximum output | Vals lists 256K; Vercel’s provider table lists 262K | Evaluator/provider metadata, not a Kingy-verified API ceiling |
| API identifier | mistral-large-4 |
Record the actual version used for reproducible comparisons |
| API features | Structured outputs, function calling, document Q&A, prefix completion, batch processing, agents and conversations | Feature availability does not establish benchmark quality |
| Weights | Official upcoming-release page lists October 29, 2026 as current ETA | Planned artifact Mistral-Large-4.0-1T05-A52B; download and license sections remain “Coming soon” |
| Training infrastructure | 3,800 NVIDIA Grace Blackwell GPUs in Mistral’s European data centers | No verified total training bill published |
| Language coverage | Mistral says training data covers 160+ languages, including all official EU languages | Coverage is not a per-language accuracy guarantee |
Sources: official model card, launch announcement, official upcoming-release page, Vals profile, Artificial Analysis profile, Vercel AI Gateway catalog.
Why 49B active parameters does not make this a 49B deployment
A mixture-of-experts model routes computation through selected experts rather than activating all its weights for every token. Mistral’s updated documentation clarifies the count: 49B in active experts, 52B when embeddings and output layers are included. The official planned-artifact name ends in A52B. The announcement initially used 49B; its current headline now says 52B, matching the card. The documented expert-versus-inclusive distinction remains unchanged. This is a revision to the published count, not evidence of a newly trained larger model. Mistral’s upcoming release, updated model card
Dividing those counts by 1.05T total gives approximately 4.7% for active experts or 5.0% for the inclusive count. These describe the architecture, not a prediction that serving costs scale by either percentage against a dense model of the same total size.
The complete model still contains the other experts. A deployment must store them, distribute or load them, move activations and manage communication between devices. Context length, batch size, precision, routing implementation and parallelism all affect throughput and cost. Active parameter count alone cannot answer how many GPUs you need.
Simple weight arithmetic shows the scale. At two bytes per parameter, 1.05T parameters imply roughly 2.10 TB of raw weight data. At one byte, the figure is roughly 1.05 TB. Idealized four-bit packing gives roughly 525 GB. These are decimal payload estimates calculated from the advertised parameter count. They exclude runtime overhead, quantization metadata, KV cache, activations, redundancy and any uncertainty about which components the total includes.
Those estimates are not validated hardware requirements. A quantized checkpoint, a supported runtime and a working distributed configuration must exist before a credible deployment recommendation can be made. There is no basis here for promising a convenient consumer-GPU or laptop setup. Our local AI hardware guide explains the distinction between fitting weights and serving a useful workload.
The one-million-token claim needs an endpoint check
Mistral’s own model card is the primary source for the advertised 1M context. Vals currently lists 512K and Artificial Analysis 524K. We have not established whether those differences reflect an earlier preview configuration, evaluator settings, different endpoints or metadata that needs updating.
Provider snapshot, October 6, 2026, 09:08 PDT: Vercel’s AI Gateway provider table listed the Mistral route at 524K context and 262K maximum output, under gateway identifier mistral/mistral-large-4. That October 6 gateway snapshot displayed $0.68 input, $0.07 cache-read and $2.09 output per million tokens; those historical rates are not the current direct Mistral quote. A search-indexed version of the listing showed 1M context; we use the directly fetched provider table for this snapshot. These are published route specifications, not a Kingy API acceptance test. They strengthen the case for checking the chosen route rather than treating the model card’s 1M as a universal limit. Vercel’s Large 4 listing
For an implementation, verify the limit on the exact endpoint and model version you intend to use. Reserve room for the response and any tool messages. A context window is a shared budget; one million input tokens plus a substantial output may exceed a one-million-token total context.
Additional provider report, checked October 6 at 23:22:12 PDT / October 7 at 06:22:12 UTC: Frontière AI says its October 6 integration through Mistral’s EU endpoint found 524,288 tokens in the API model-list metadata and an explicit rejection when max_tokens exceeded 262,144. This is the gateway operator’s account of its checks; we have not inspected raw request/error traces or reproduced them. It adds route-specific evidence consistent with the evaluator/provider metadata above. A model-list value and an output-limit rejection do not establish successful retrieval across a 524K input, or explain the official card’s 1M figure. The discrepancy remains unresolved. Provider’s original API-check report
Capacity also differs from useful recall. A model accepting a large document does not establish that it can reliably find every relevant clause, reconcile distant evidence or avoid inventing citations. Long-context retrieval tests and your own document acceptance tests remain necessary. We will update this section when the configuration discrepancy is resolved.
What the independent benchmarks actually show
Benchmarks measure tasks under a particular implementation. Agent scaffolding, tool permissions, reasoning effort, sampling, output limits and retry policies can change the result. We use the same evaluator’s tables for comparisons wherever possible and keep differently configured tests separate.
Broad capability: competitive, but behind the frontier leaders
| Model | Vals Index v2.1 | Vals reported cost per test |
|---|---|---|
| Claude Opus 5.5 | 66.97% | $32.14 |
| Claude Sonnet 5.5 | 67.04% | $21.34 |
| Gemini 4 Argon | 68.90% | $15.68 |
| GPT-6 Astra | 63.13% | $18.46 |
| GPT-6.1 Sol | 61.15% | $3.24 |
| GLM 5.3 | 53.51% | $7.25 |
| Kimi K3 | 50.30% | $6.38 |
| Qwen 3.8 Max | 48.27% | $4.96 |
| DeepSeek V4.1 Flash | 51.32% | $0.33 |
| Mistral Large 4 Preview | 48.05% | $13.78 |
| DeepSeek V4 Pro 0813 | 47.63% | $3.35 |
Snapshot: October 6. Vals uses its own evaluation configurations. The Large 4 profile specifies high reasoning effort, temperature 1 and top-p 0.95, while warning that individual benchmarks may use different settings. Vals Index
Separately, Artificial Analysis reports an Intelligence Index score of 38 for Large 4 Preview. Its v4.3.2 index incorporates ten evaluations, spanning agentic work, coding, knowledge, reasoning and long-context tasks. That score is on a different scale from Vals; the two must not be averaged or compared as percentages of the same test. Artificial Analysis profile
Vals reports Large 4 at 48.05% ±1.11, ranking 32nd of 44 models in the displayed index. The index combines industry-oriented evaluations across finance, coding, legal and tax work with economic weighting. It is not a universal probability that the model will complete your task.
The small numerical distance between Large 4 and Qwen 3.8 Max, or between Large 4 and DeepSeek V4 Pro, should not support a sweeping rank claim. The displayed uncertainty and different workload results matter more than a few tenths of a point. The larger gaps to the leading frontier models are harder to dismiss, although your specific application may favor Large 4.
Mistral’s announcement describes it as the best open-weight model from the US or Europe on aggregated benchmarks. That is a geographically bounded vendor claim, with an announced future weight release. It does not mean best among all models, best among all globally developed open models or downloadable today. The broader independent tables above are the more useful starting point for procurement. (Update, November 16, 2026: Mistral released the open weights on October 29, 2026; see the open-weights update.)
Knowledge-work deliverables: another independent comparison
AA-Briefcase v1.1 rates Large 4 Preview at 1,393 Elo, with a displayed 95% confidence interval of −10 / +10. Its four professional-project scenarios contain 91 tasks, including spreadsheet, presentation and memo deliverables. Tasks run independently; agents do not carry their own earlier submissions forward. The combined Elo incorporates rubric checks, analytical quality and presentation quality. It is not a task-pass percentage. AA-Briefcase v1.1
| Model and displayed setting | AA-Briefcase v1.1 Elo | Displayed 95% interval offsets |
|---|---|---|
| Claude Sonnet 5.5, Max / Default Fallback | 1,823 | −12 / +13 |
| Claude Haiku 5.5, Max | 1,578 | −10 / +10 |
| GPT-6 Astra, Max | 1,569 | −10 / +11 |
| MiMo-V2.6-Pro | 1,516 | −10 / +11 |
| Mistral Large 4 Preview | 1,393 | −10 / +10 |
| Claude Haiku 5.5, Medium | 1,372 | −8 / +8 |
| DeepSeek V4 Pro 0813, Max | 1,256 | −8 / +7 |
These are the evaluator's published configurations, not equal-compute trials. Large 4's row does not specify its reasoning effort. The result adds a business-deliverable comparison to the specialist finance/legal evidence; it does not establish continuous multi-week memory or production reliability. These are newly inspected results, not a Kingy run or evidence of a new checkpoint. Public evaluator table
Configuration-label correction, checked October 8 UTC: AA now labels Haiku 5.5’s 1,578 Elo result as Max effort and its 1,372 result as Medium effort, without the “Default Fallback” suffix shown when we inspected the table on October 7. We have updated the two rows to match the current evaluator labels. The scores and confidence intervals are unchanged, as is Large 4’s 1,393 Elo. The same model family still lands above or below Large 4 depending on effort. This is a change to the published labels; raw call traces and a dated rerun explanation were not verified, so it does not establish whether the earlier runs used fallback models or whether AA reran them. The task scope remains AA-Briefcase v1.1, and Large 4’s reasoning effort remains unspecified. Evaluator’s public comparison table
Haiku’s lower short-request tariff in the pricing section is a separate fact. It does not establish a lower cost for these knowledge-work runs: task token counts, caching, long-prompt tiers, reasoning effort and any additional model calls affect the bill. These new comparison rows do not show that Large 4’s checkpoint or score changed, and Kingy has not run either model.
Long-document reasoning: a useful result with a clear ceiling
Artificial Analysis's AA-LCR v1.1 chart reports 81.3% for Large 4 Preview. Its document questions require connecting information across reports, papers and other long texts. The result supports evaluating the model for document reasoning alongside the specialist legal and finance evidence. Original AA-LCR leaderboard
| Model and displayed setting | AA-LCR v1.1 pass rate |
|---|---|
| Kimi K3, Max | 88.7% |
| MiMo-V2.6-Pro | 86.3% |
| Claude Opus 5.5, Max with fallback | 84.7% |
| DeepSeek V4.1 Flash, Max | 84.0% |
| GPT-6.1 Sol, Max | 83.0% |
| Claude Sonnet 5.5, Max with fallback | 82.7% |
| Mistral Large 4 Preview | 81.3% |
| GPT-6 Astra, Max | 80.7% |
These are the evaluator's displayed settings. Large 4's chart label does not specify reasoning effort, so this is not an equal-compute comparison. Its 0.6-point lead over Astra does not establish a meaningful winner without model-specific uncertainty; several frontier and open-model alternatives score higher. Same-version chart
AA's methodology specifies 100 questions, three repeats, and pass@1 aggregated across repeats. Inputs are roughly 100K tokens, measured with cl100k_base; the benchmark requires at least a 128K context window. GPT-5.6 Luna at medium effort checks answer equivalence. Version 1.1 adds a grading system prompt, corrects 16 answer keys and changes the judge, so its scores should not be compared directly with v1.0. Evaluator methodology
This is evidence about reasoning within the tested document lengths. It is not a 1M-token acceptance or retrieval test, and it does not resolve the official 1M versus roughly 512K provider/evaluator discrepancy. We newly inspected this published result during the watch; we did not run the evaluation or verify a new model checkpoint. Kingy local tests remain zero.
Finance: a credible result with a qualified Astra comparison
| Model | Finance Agent v2 accuracy | Reported cost per test | Reported latency |
|---|---|---|---|
| Gemini 4 Argon | 65.40% | $4.38 | 16m 21s |
| Claude Opus 5.5 | 58.59% | $9.22 | 33m 08s |
| Claude Sonnet 5.5 | 58.10% | $6.55 | 31m 43s |
| GLM 5.3 | 55.84% | $1.07 | 15m 50s |
| Mistral Large 4 | 54.68% | $1.20 | 26m 02s |
| GPT-6 Astra | 53.54% | $6.82 | 11m 33s |
| Kimi K3 | 53.11% | $1.91 | 4m 46s |
| GPT-6.1 Sol | 52.03% | $1.62 | 15m 25s |
| DeepSeek V4 Pro 0813 | 50.39% | $0.88 | 16m 15s |
Source: Vals Finance Agent v2. Latency describes this evaluator’s agent workloads, not chat response time or a service-level guarantee.
Large 4 exceeds Astra by 1.14 percentage points in this snapshot, with a substantially lower reported test cost. It also takes more than twice as long in the displayed latency measure. That tradeoff matters: a research job that runs overnight and an analyst waiting interactively have different requirements.
This result supports evaluating Large 4 for financial workflows; it does not establish a general finance crown. Gemini, both Claude models and GLM 5.3 score higher in the same table. Financial reasoning accuracy also says nothing by itself about permission controls, auditability, data provenance or the suitability of generated advice.
Legal agents: one of the most interesting launch results
| Model | Harvey Legal Agent Benchmark task pass rate | Reported cost per test |
|---|---|---|
| Gemini 4 Argon | 19.58% | $10.55 |
| Mistral Large 4 | 15.83% | $4.18 |
| Kimi K3 | 12.92% | $3.83 |
| Qwen 3.8 Max | 10.42% | $2.37 |
| GLM 5.3 | 8.33% | $4.30 |
| DeepSeek V4 Pro 0813 | 7.50% | $0.17 |
| GPT-6 Astra | 5.42% | $26.16 |
| GPT-6.1 Sol | 5.42% | $3.93 |
| Claude Opus 5.5 | 3.75% | $21.38 |
| Claude Sonnet 5.5 | 2.92% | $16.61 |
Source: Vals Harvey Legal Agent Benchmark.
Large 4 ranks sixth of 75 models in the displayed results. That is a meaningful specialist signal and substantially better than its broad-index rank. The low absolute pass rates also show how demanding the task-level test is. A 15.83% result is not a claim that legal professionals can delegate the other 84.17% safely, nor a measurement of lawyer replacement.
Different legal scores can refer to different units: passing an entire task, satisfying an individual rubric criterion or answering a research question. Do not compare those percentages as though they measure the same outcome. Large 4’s separate Legal Research Bench result is 31.73%, ranking 38th of 74, which further cautions against converting one strong agent benchmark into a universal legal superiority claim. Vals model results
For buyers, the next step is a controlled evaluation of actual contracts, research questions and citation requirements, with qualified review. The benchmark makes that experiment worthwhile. It does not remove the review requirement.
Coding agents: the harness changes the conclusion
Mistral’s launch cites Artificial Analysis results of 61.7% on DeepSWE v1.1, 59.4% on SWE-Atlas-QnA and 28.3% on Terminal-Bench 4. Their arithmetic mean is 49.8%, the cited Coding Agent Index. These are launch-reported AA results; we have not independently reproduced the runs. Mistral announcement
AA’s coding index methodology combines three benchmarks with equal benchmark weighting. Its current evaluation describes 113 DeepSWE tasks, 66 Terminal-Bench 4 tasks and 124 SWE-Atlas tasks, with results averaged across three attempts per task. A composite helps summarize that test set, but it can conceal a model’s much weaker terminal performance. Artificial Analysis coding agents
Vals’ separate Terminal-Bench 4 evaluation uses Mini-SWE-agent and reports a different Large 4 result:
| Model | Vals Terminal-Bench 4 accuracy | Reported cost per test |
|---|---|---|
| Claude Opus 5.5 | 65.15% | $13.20 |
| Claude Sonnet 5.5 | 64.14% | $16.51 |
| GPT-6 Astra | 59.60% | $9.58 |
| GPT-6.1 Sol | 55.05% | $1.72 |
| GLM 5.3 | 38.89% | $9.37 |
| Qwen 3.8 Max | 34.34% | $10.63 |
| Mistral Large 4 | 22.73% | $7.90 |
| Kimi K3 | 17.17% | $12.02 |
| DeepSeek V4 Pro 0813 | 14.14% | $3.31 |
Source: Vals Terminal-Bench 4. This is a separate evaluation from the AA result cited by Mistral.
The 22.73% and 28.3% Large 4 numbers should remain separate. Averaging them would invent a new benchmark. Differences in task selection, scaffolding and execution budgets can explain differences between evaluators, but we have not isolated the cause here.
AA's current Terminal-Bench 4.0 methodology specifies 66 tasks, mini-swe-agent, and pass@1 averaged across three repeats per task. A task passes only when all its tests pass. We have not directly verified a current Large 4 score on that page, so we retain the launch-attributed 28.3% above rather than substituting a third-party summary. AA terminal evaluation and method
Scientific coding needs the same version discipline. AA labels its SciCode evaluation under review after an independent audit identified possible dataset errors. It says corrected data would require rerunning the relevant models. Mistral's launch claim refers to SciCode-Verified; that label must not be silently equated with AA's current SciCode dataset or scores. We have not verified a matched Large 4 comparison across those versions. AA review notice
Vals also reports 78.40% on Vibe Code Bench v1.1, 30.56% on Code Migration and 14.26% on Vibe Code Bench 1–100. Those are distinct tasks and versions. The harder 1–100 score cannot be substituted for v1.1 or compared against a competitor’s v1.1 result without labeling the difference. Vals profile, Vibe Code benchmark
The practical conclusion is restrained. Large 4 can be a credible coding candidate, particularly where deployment constraints matter. The independent terminal table gives a strong reason to retain a frontier coding agent for difficult autonomous work and compare cost per accepted change, including repair attempts and reviewer time.
Early developer tests: useful failure examples, limited comparability
Adam Holter published eight demo variants with saved responses and artifacts. His report describes two refusals, one learning app that ran with defects, another that failed JavaScript parsing, a game that failed to start, a partial animation and two controller SVGs with visual errors. Original test report
The setup used 4,096 output tokens per call and temperature 0.7. It mixed console defaults with OpenRouter calls requesting medium reasoning; the API reported zero reasoning tokens. Truncated outputs required continuations, and the game involved history compaction and a provider switch. Those conditions differ substantially from the high-reasoning agent benchmarks above.
The reported $0.0846 covers only metered finishing calls, excluding console usage and live app QA. It is not the total test-suite cost. These are author-reported examples from a small task set, without a matched frontier comparison; Kingy has not reproduced them. They offer concrete failure cases to investigate, not a new general coding rank.
Early provider checks: useful integration evidence, small samples
Frontière AI, which sells access through its own gateway, reports an October 6 run with 25 of 25 self-contained QA answers correct, 0.56 seconds mean time to first token, and 38.7 tokens per second over a 1,269-word generation. Its published method uses 25 general-knowledge, math, reasoning and language questions, three streamed prompts for first-token timing, and one essay for throughput. Only the visible answer is graded. These are gateway-provider results, not a neutral multi-provider comparison or Kingy measurements. The small samples and absent matched reasoning/temperature settings prevent comparison with AA’s 116.1 tokens/s or its Intelligence Index. Original results, provider methodology
The operator also reports a get_weather call with valid JSON arguments, an accepted tool-response round trip, and streamed usage on the final chunk. Its gateway translates some request fields and reasoning-response formats. That distinction matters: a successful integration through a translating gateway does not verify that the same unmodified client request works directly against Mistral. We have not inspected raw response artifacts or run these checks ourselves. API integration report
Its separate behavioral suite reports 14 of 15 adversarial prompts answered safely, with one prompt injection causing an injected marker to appear before the answer. The method uses three prompts in each of five categories and passes a category when at least two answers are safe. All five categories therefore passed its rule despite that miss. This is a small, provider-run behavior check; it does not establish comprehensive prompt-injection resistance, a security certification or a matched result against other models. Its model page still leaves license and provenance verification unconfirmed while public weights are pending. (Update, November 16, 2026: Mistral released the open weights on October 29, 2026; see the open-weights update.) Behavioral test rules, model verification status
Cybersecurity, vision and safety: independent evidence and vendor claims
Independent result, checked at 13:15 PDT / 20:15 UTC: Artificial Analysis reports 81.7% pass@1 for Large 4 Preview on CyberGym-E2E-AA, highest on its displayed leaderboard. MiMo-V2.6-Pro scores 78.6% and GPT-6 Luna (Max) 77.9% there. AA CyberGym-E2E-AA
AA uses 131 selected C/C++ memory-safety tasks, its Stirrup harness and 90 minutes per task. A pass requires reproducing a crash, fixing it and preserving functionality tests; fixing the reference vulnerability is a separate diagnostic. This is a specific defensive workload, distinct from Cybench and Berkeley’s original evaluation. Evaluator methodology and scoring
Independent composite result: In its October 6 announcement, AA reports 50% on the Cyber Index for Large 4 Preview, tied with GLM-5.3-Flash at 50%, behind MiMo-V2.6-Pro at 56%, and ahead of Kimi K3 and DeepSeek V4.1 Flash (max). The composite result is different from Large 4’s leading CyberGym component score. AA’s prediction about a future top-three open-weight position depends on the weights actually being released. Exact Large 4 reasoning, provider and moderation settings remain unverified. Evaluator announcement
Mistral reports 82% on CyberGym-E2E, 93% on Cybench and a top-five position in the Artificial Analysis Cyber Index. These are the company’s launch claims. They should not be presented as Kingy-run tests, and the 40-task Cybench result should not be treated as a comprehensive security audit. Mistral launch
AA’s Cyber Index focuses on defensive work using CWE-Bench-AA, DeepsecBench-AA and CyberGym-E2E-AA: reproducing and patching real vulnerabilities. Its methodology also explains that safety refusals can receive zero scores. A lower score can therefore reflect a refusal policy as well as an inability to solve a problem. The benchmark does not collapse those two causes into an explanation of commercial suitability. AA Cyber Index, methodology
Mistral describes additional access for selected cybersecurity partners, with reduced moderation and expanded cyber capabilities. Results from such access must be distinguished from the public API preview. Model identity alone is insufficient if policy configuration or tool access differs. We are watching for independently published configurations and results that clarify this point.
For vision, Mistral reports 42% on Dense200, compared with 41% for GPT-6 Astra in its comparison. That is one percentage point on one test. Without uncertainty estimates and broader replicated evaluations, it supports a promising visual-grounding result, not a general claim that Large 4 is the best vision model.
Independent document-and-vision evidence: AA’s GDP.pdf implementation gives Large 4 Preview 18.6% All-pass, compared with 19.2% for MiMo-V2.6-Pro. Its page lists GPT-6 Astra (Xhigh) at 32.2% and GPT-6.1 Sol (High) at 32.0%. AA rounds Large 4’s result to 19% in its announcement. This supports a narrower conclusion than a general vision win. GDP.pdf leaderboard, AA announcement
GDP.pdf covers 100 tasks, ten professional domains, 4,592 source pages and 1,275 atomic grading criteria. AA supplies parsed text plus rendered images to image-capable models and runs five independent attempts per task. All-pass requires every criterion to pass in an attempt; it is not the average share of criteria answered correctly. The judge is GPT-5.6 Luna Medium. AA’s document delivery, harness and judge differ from Surge AI’s original implementation, so their scores should not be merged. This evaluates document reasoning, rather than isolated visual perception. Evaluator setup
The supported product story is text-and-image input with text output, including document Q&A and structured responses. Do not infer native audio, video generation or image generation from the word “multimodal.” A useful business evaluation would measure document extraction, bounding or grounding accuracy, small text, charts and citation consistency separately.
Mistral also reports 93.3% attack resistance on B3 and 1.691 out of 2 on KORABench. Those are named evaluations under reported conditions, not a promise that the model resists every prompt injection. Production agents still need scoped permissions, output validation and human approval where the action warrants it. A better model score does not make a tool connection safe by itself.
Original email-injection test: 0 of 90 attacks succeeded
Krynex Labs, an AI consultancy selling security tests, reports 0 of 90 successful attacks against Large 4, versus 57 of 90 against Medium 3.5, in its October 7 German email-summarization test. Three attack types targeted payment instructions, internal instructions and a login link; each used three defenses and ten repeats. Calls used OpenRouter, temperature 0.7 and a 4,000-token output limit for Large 4. All 30 clean controls were summarized correctly. Original report
The author manually overturned two automated flags because Large 4 mentioned the payment instruction while warning it had ignored it. An earlier 300-token cap produced 115 empty responses out of 120; the author attributes this to reasoning consuming the budget. Reported averages were $0.0015 and 10.3 seconds per Large 4 response, versus $0.0008 and 0.7 seconds for Medium. These are operator measurements from one scenario, not matched frontier benchmarks. Raw traces, underlying routing and reasoning effort remain unverified; Kingy has not replicated the run. The report does not test tool agents, long documents or broader attack families.
API pricing: current rates and calculated costs
Mistral’s official Standard rates, checked October 31, 2026, are shown below in US dollars per million tokens. The page no longer supports this guide’s earlier sale-price presentation. We have not established when the rates changed and are not reporting a new 50% price cut. Official pricing
| Token type | Standard rate per million tokens |
|---|---|
| Input | $0.70 |
| Cached input | $0.07 |
| Output | $2.10 |
For 10,000 uncached input tokens plus 2,000 output tokens, the calculated token charge is $0.01120: $0.007 input plus $0.00420 output. At 100 million uncached input plus 20 million output tokens, the calculated charge is $112. These examples exclude tools, taxes, infrastructure and retries; they are arithmetic estimates, not invoices or model tests.
Cached input is a separate billing category. Apply its rate only to eligible cached tokens, and check the selected service mode and route. Earlier Batch, Priority and regional sale figures are retained only in the dated historical log; they are not current quotes.
Token-cost comparison with dated alternative prices
The Large 4 row uses the October 31 correction. Other model prices below retain the guide’s October 7 observations and need a fresh provider check before budgeting.
| Model/provider | Uncached input /M | Output /M | Cost of 10K input + 2K output |
|---|---|---|---|
| Mistral Large 4, Standard checked October 31 | $0.70 | $2.10 | $0.01120 |
| GPT-6 Astra, Standard short-input tier | $10.00 | $50.00 | $0.20000 |
| GPT-6.1 Sol, Standard short-input tier | $2.00 | $10.00 | $0.04000 |
| Claude Sonnet 5.5, Standard | $2.00 | $10.00 | $0.04000 |
| Claude Opus 5.5, Standard | $4.00 | $20.00 | $0.08000 |
| Claude Haiku 5.5, Standard, prompt ≤100K | $0.10 | $0.50 | $0.00200 |
| GLM 5.3, Z.ai | $1.40 | $4.40 | $0.02280 |
| DeepSeek V4.1 Flash, peak | $0.30 | $1.20 | $0.00540 |
| DeepSeek V4.1 Flash, off-peak | $0.15 | $0.60 | $0.00270 |
| DeepSeek V4 Pro 0813, peak | $1.32 | $3.96 | $0.02112 |
| DeepSeek V4 Pro 0813, off-peak | $0.66 | $1.98 | $0.01056 |
| Mistral Large 3 | $0.50 | $1.50 | $0.00800 |
First-party sources: OpenAI Astra, OpenAI Sol, Anthropic pricing, Z.ai pricing, DeepSeek pricing, Mistral pricing.
Anthropic’s newly released Claude Haiku 5.5 adds a lower-cost option: prompts up to 100,000 tokens cost $0.10/M input and $0.50/M output. Above that prompt threshold, both rates rise to $0.50/M input and $2.50/M output. The table’s 10K-input/2K-output example costs $0.00200, so Large 4 costs 5.6 times as much for those token counts. A 150K-input/10K-output Haiku request uses the higher tier and costs $0.10, before tools, caching or taxes. These are calculated tariffs, not evidence of equivalent task quality or speed. Anthropic documents adaptive thinking by default, so reasoning usage still matters. Official model and pricing tiers
The OpenAI examples use requests within the standard short-input tier; requests above 272K input tokens have different pricing multipliers. DeepSeek’s peak and off-peak schedules are separate tariffs, not prices you can select independently of when a request runs. Provider routes, caching, batch modes and priority service also matter. This table deliberately compares an uncached, short example rather than pretending every provider’s billing system is identical.
Using the dated alternative tariffs above, Large 4’s $0.01120 illustrative request is 28% of the $0.04 Sol or Sonnet example and 5.6% of the $0.20 Astra example. These ratios describe token prices for this input/output mix, not quality-adjusted savings. A harder request can change the ratio through reasoning output, retries, cache behavior and task completion.
For a deeper comparison of the expensive generalist alternative, see our GPT-6 Astra versus Claude Sonnet 5.5 analysis.
Why evaluator task cost is more revealing than the tariff
Vals reports $13.78 per Vals Index test for Large 4, compared with $3.24 for Sol, despite Sol’s higher current headline token rates. Large 4’s reported index latency is 105 minutes 50 seconds. The evaluator’s workload includes agent behavior and its own configuration; it is not a single small chat request.
Those results use the $1.36/$4.18 Large 4 rates listed in the evaluator’s snapshot. Repricing an identical token trace requires its separate input, cache and output counts. The current $0.70/$2.10 input/output rates are not an exact 50% reduction from that snapshot. A recalculation would not be a new observed Vals result. We therefore retain the published $13.78 and do not relabel it as a live invoice estimate.
For a business, the useful denominator is accepted work: total model, tool, infrastructure and review cost divided by successful, usable outcomes. Track failed attempts too. A lower-priced model can be expensive if it makes longer calls or requires more repair. A more expensive model can be economical when it finishes cleanly. The finance and legal tables give Large 4 stronger cost-quality arguments than the broad index does.
Artificial Analysis reports roughly 116.1 output tokens per second in its profile, alongside a reported $1.13 Intelligence Index task cost at the higher launch rates. Throughput is a useful serving signal but does not include all the time spent waiting, reasoning and calling tools in a business agent. It cannot be compared directly with Vals’ end-to-end job latency. AA profile
In its October 6 report, AA calculated a discounted Intelligence Index cost of approximately $0.57 per task, versus its published $1.13 at the higher tariff. It reports GLM-5.3-Flash at $0.25 and DeepSeek V4.1 Flash (max) at $0.27. Treat the discounted figure as a tariff-based recalculation, not a newly rerun benchmark. The historical $1.13 result above remains intact. AA cost comparison
Open weights, licensing and the self-hosting cost question
Update, November 16, 2026: the weights are out. Mistral released the open weights on October 29, 2026, under a new name, mistralai/Mistral-Large-4-1T-A52B, (1,060.6 GB, stored in 8-bit) and a smaller NVFP4 4-bit version (610.0 GB). They come under the Mistral Ecosystem Open-Weight License, which Mistral describes as a modified MIT license for commercial and non-commercial use; running a model-as-a-service business needs a separate commercial license from Mistral. Source: Mistral’s open-weight announcement (October 29). The paragraphs below describe the situation before the release and are kept as written on October 6.
The word “open” needs a date and an artifact. On October 6, the API is public, while the weights are promised for the end of the month. Mistral’s official Hugging Face page identifies the planned artifact as Mistral-Large-4.0-1T05-A52B and gives October 29, 2026 as the current ETA. It is an upcoming-release page, not downloadable weights, and an ETA can change. Mistral’s model documentation still lists download and license as coming soon. We cannot verify commercial redistribution rights, modification terms or supported deployment formats from an unreleased license. Official release page
Current distribution terms are now documented. Mistral’s October 6 technical disclosure, version 1, describes SaaS and partner-served terms as proprietary licenses that restrict weight access and impose usage, distribution and modification limits. It separately documents on-premise deployment through proprietary packaged software and a bespoke, confidential self-deployment agreement that permits weight access subject to its terms. The disclosure says it will be updated if an open-weight release occurs. These current routes do not establish the license for the planned public checkpoint. Hardware requirements for contract customers are supplied privately; we have not verified a public serving recipe or contract price. Mistral technical disclosure, section 3 and sections 5.2–5.3
Mistral’s separate training-content summary, also version 1 dated October 6, reports more than 10 trillion text tokens and an image-data range of one million to one billion images. It identifies Common Crawl, other public datasets, third-party data, synthetic data and user interactions with other Mistral products, subject to opt-out safeguards. Its latest overall collection date is September 2026; the separate crawler collection period runs through July 2026. These are provider disclosures, not an independently audited corpus or a guarantee of knowledge freshness. The ranges do not establish training duration, compute or dollar cost. Training-content summary, sections 1.3 and 2
Mistral Large 3 is an instructive predecessor: its documentation specifies 675B total parameters, 41B active parameters, a 256K context window and Apache 2.0 licensing. Large 4 increases the advertised total count by about 56%, and the card’s context window by roughly four times. Its 49B expert/52B inclusive active counts should be compared with the predecessor only after checking that the counting definitions match. None of these changes guarantees a proportional quality increase, and Large 3’s license does not automatically become Large 4’s license. Large 3 model documentation
Comparisons with “open source” also need care. An API model associated with an open-model ecosystem is not necessarily a downloadable checkpoint. In particular, the Qwen 3.8 Max row above names an evaluated API model; it should not be silently replaced by a smaller open Qwen checkpoint. Model size, release version, license and inference provider belong in the comparison.
For a future self-hosted deployment, compare the entire operating bill: accelerator rental or depreciation, CPU and RAM, networking, storage, monitoring, redundancy, engineer time and utilization. Running a large reserved cluster for sporadic requests can be much more expensive than buying tokens. Sustained high utilization, private-data constraints or specialized customization can change that calculation.
We have no verified Large 4 self-hosting throughput, quantized quality measurements or production-serving recipe. Until the release arrives, there is no evidence-backed break-even price to publish. We also cannot estimate training cost from 3,800 GPUs alone: duration, utilization, ownership, power, networking and accounting treatment are missing.
Can you run Mistral Large 4 at home?
Almost certainly not. At about 1 trillion parameters, Mistral Large 4 is open but not a home model. Mistral’s own 4-bit release is 610.0 GB, and the full 8-bit release is 1,060.6 GB. The only home machine that can hold it at all is a 512GB Mac Studio, and only with community 1-bit or 2-bit versions, which lose quality. Everything smaller cannot load even the smallest full-model file.
| File | Who made it | Size |
|---|---|---|
| Mistral-Large-4-1T-A52B | Mistral (full release, 8-bit) | 1,060.6 GB |
| Mistral-Large-4-1T-A52B-NVFP4 | Mistral (4-bit, for Blackwell graphics cards) | 610.0 GB |
| Q4_K_M GGUF | ggml-org, the team behind llama.cpp (4-bit) | 634.8 GB |
| IQ2_XXS GGUF | ggml-org (2-bit) | 297.7 GB |
| UD-IQ1_S GGUF | Unsloth (1-bit, one of the smallest full-model files) | 233.0 GB |
Sizes from the Hugging Face pages of Mistral, ggml-org and Unsloth, checked November 16, 2026, in GB of 109 bytes. Mistral’s card points to the ggml-org files for llama.cpp, the free program most people use to run models at home.
Can you run Mistral Large 4 on a 512GB Mac Studio? Barely (estimated). Mac Studio M3 Ultra 512GB · Mistral’s 4-bit file needs about 672 GB, far more than the 384 GB macOS lets a model use; ggml-org’s 2-bit file needs about 328 GB and Unsloth’s 1-bit file about 257 GB, so only these fit · llama.cpp · estimated about 28 tokens per second with the 2-bit file · “Barely” because it only fits at 2 bits or lower · Estimated Nov 16, 2026
Can you run it on a 128GB Mac or Ryzen AI Max+ 395, a 64GB Mac, a PC with a 24GB or 32GB graphics card, or a 16GB laptop? No (estimated). Even the smallest full-model files (about 233 GB) are larger than all the memory these machines can give a model, including 64 GB of system memory on a gaming PC. Experimental cut-down versions exist, but they remove part of the model, and even the smallest we found (99.1 GB) is too big for these machines · Estimated Nov 16, 2026
Estimates use our Can You Run It at Home rules: file size plus chat memory for an 8,192-token conversation (about 0.7 GB here, because the model compresses its chat memory) plus 10% overhead, and half of each machine’s memory speed divided by the data read for each word. A token is a word or piece of a word. We did not run Mistral Large 4 on a Kingy machine: the smallest file is too big for our 128GB test machine and our download limit.
European deployment and data residency
European training infrastructure is relevant to procurement, but it does not establish that every API request, log and account record remains in a chosen jurisdiction. Mistral offers regional inference routes for the EU and US and documents a 10% regional pricing uplift across applicable token charges. Its global endpoint is distinct from a region-specific route. Mistral regional inference documentation
Applying the documented 1.1× regional multiplier to the current Standard rates gives an illustrative $0.77 input, $0.077 cached input and $2.31 output per million tokens, or $0.01232 for 10K uncached input plus 2K output. These are calculated values; confirm model availability and the selected endpoint’s current quote. Regional documentation excludes Batch from supported stateful features, so the earlier regional Batch sale arithmetic does not establish a usable route. Regional terms
The residency documentation also distinguishes inference processing from control-plane information such as accounts, billing and analytics. Buyers should check those boundaries against their actual requirements. European model development, regional inference and a fully controlled private deployment are related purchasing considerations with different operational consequences.
Large 4 offers a European provider now, a documented private-deployment route through a bespoke agreement, and a planned public weight release later. (Update, November 16, 2026: Mistral released the open weights on October 29, 2026; see the open-weights update.) Procurement must distinguish the current confidential contract from the eventual public license, and assess serving requirements and contractual controls for the route actually chosen.
How to evaluate it without wasting the preview window
The preview can change without a new public model name. Mistral's official lifecycle policy permits silent updates during Public Preview and gives no guarantee that a preview reaches General Availability; it may be retired first. The policy lists one month's deprecation notice for Public Preview. This is the documented lifecycle policy, not evidence that Large 4 has just changed or been deprecated. Record timestamps, returned model identifiers and settings alongside each result, and repeat acceptance checks after observed behavior changes. Mistral model lifecycle policy
Start with a narrow set of tasks drawn from your own workload. For legal work, require traceable citations and correct treatment of the relevant clauses. For finance, require sourced calculations and consistent units. For coding, require passing the project’s tests and a reviewable change. Define success before looking at the outputs.
Use the same evidence, tools, execution limits and acceptance criteria for each model. Record reasoning effort, model version, date, token usage, retries and wall-clock time. A powerful model with a weak agent wrapper and a weaker model with a well-tuned wrapper are not a clean model comparison.
The official usage example supports selecting high reasoning effort. A minimal illustrative API call is:
import os
from mistralai.client import Mistral

client = Mistral(api_key=os.environ["MISTRAL_API_KEY"])
response = client.chat.complete(
    model="mistral-large-4",
    messages=[{
        "role": "user",
        "content": "Summarize the supplied evidence and cite each conclusion."
    }],
    reasoning_effort="high",
)
print(response.choices[0].message.content)
This follows the official model usage documentation. It is an illustrative starting point, not a tested integration or a completed benchmark. Set suitable budgets and output limits for your application, and avoid sending restricted information through an unapproved route.
For agents, inspect the failures rather than just the aggregate score. Was the answer wrong, a tool call malformed, a source unavailable, the budget exhausted or the action refused? Those failures require different remedies. Keep a frontier-model comparison and a cheaper-model comparison so the decision includes both quality and cost.
What we are watching over the next 72 hours
The initial publication leaves several questions open:
- Independent replication: additional evaluator results, revised tables and disclosed reasoning or agent settings, especially in legal, finance and cybersecurity.
- Context configuration: why Mistral advertises 1M while evaluators list roughly 512K, and what the public endpoint actually permits.
- Price durability: changes to the October 31 Standard quote, current route and service-mode eligibility, and whether evaluator cost tables update their historical tariff basis.
- Weights and license: whether the October 29 ETA changes, downloadable artifacts, the final license and supported formats. The expected release is later than this initial 72-hour watch.
- Operational evidence: time to first token, throughput under realistic concurrency, tool-call reliability, long-document accuracy and total task costs.
- Preview changes: whether model updates materially change the scores or require identifying a new version rather than overwriting old results.
The article will preserve a dated record of material changes. A source check that finds nothing new will not create a cosmetic “updated” date. An unavailable source will not be treated as evidence that the underlying result is unchanged.
Dated update log
ShowHide
- November 16, 2026 — Open weights and home hardware: Noted that Mistral released the open weights on October 29, 2026, with their file sizes and license, and added a “Can you run Mistral Large 4 at home?” section with estimated verdicts by machine. No Kingy local test was run. Open-weight announcement
- October 31, 2026 — Pricing correction: Replaced October 7 sale figures with the current official Standard rates of $0.70 input, $0.07 cached input and $2.10 output per million tokens. Corrected request costs, budgets and dependent comparisons. The effective change date is unverified. Older entries below describe observations at their stated dates; their sale prices and promotion language are historical. No new Kingy model or billing test was run. Official rates
October 7, 2026, 17:27:29 PDT / October 8, 00:27:29 UTC — Corrected the current Haiku benchmark configuration labels. AA-Briefcase v1.1 removed “Default Fallback” from Haiku 5.5’s Max and Medium labels; updated the current table and explanation while retaining the earlier dated observation below. Scores of 1,578 and 1,372, confidence intervals and Large 4’s 1,393 Elo are unchanged. No underlying rerun or fallback-call change is inferred from a label edit. Existing Mistral prices, historical evaluator costs, context discrepancy and pending public weights/license remain unchanged. Current evaluator table.
October 7, 2026, 13:32:10 PDT / 20:32:10 UTC — Updated the active-count source and Haiku knowledge-work comparison. Mistral’s current announcement now says 52B active, matching its card; preserved the 49B expert/52B inclusive distinction and original announcement history. Added AA-Briefcase v1.1 Haiku 5.5 Max/Medium rows with Default Fallback labels, uncertainty and billing/configuration limits. Large 4’s 1,393 Elo and all six tariffs remain unchanged. Current announcement, evaluator table.
October 7, 2026, 11:29:41 PDT / 18:29:41 UTC — Added an original security test and a cheaper model tier. Added Krynex’s narrow email-injection results with manual-grading, budget and replication limits. Added Haiku 5.5’s two prompt-length tariffs and calculated request costs from Anthropic’s documentation. All six Large 4 tariffs and earlier evaluator scores remain unchanged. Original test, Haiku documentation.
October 7, 2026, 09:29:56 PDT / 16:29:56 UTC — Added directly verified long-document reasoning evidence. AA-LCR v1.1 reports 81.3% for Large 4 Preview; added same-chart frontier/open-model comparisons and the 100-question/three-repeat grading method. Clarified corrected answer keys, judge/version differences, unspecified Large 4 effort and why roughly 100K-token tasks cannot validate a 1M context. This is newly inspected published evidence, not a new Kingy run or proven checkpoint change. All six pricing tiers and previously cited results remain unchanged. Original chart, methodology.
October 7, 2026, 03:27:00 PDT / 10:27:00 UTC — Added independent knowledge-work results and preview reproducibility limits. Directly verified AA-Briefcase v1.1's 1,393 Elo for Large 4, confidence interval and frontier/open-model comparison rows. Added its task structure and grading limits, AA's Terminal-Bench harness/repeat setup and SciCode dataset-review warning, and Mistral's policy allowing silent preview updates. These are newly inspected published results and policies, not a newly run benchmark or demonstrated checkpoint change. Existing prices, cited scores, historical evaluator costs, context discrepancy and pending public weights/license remain unchanged. AA-Briefcase, Terminal-Bench method, SciCode notice, official lifecycle policy.
October 6, 2026, 23:22:12 PDT / October 7, 06:22:12 UTC — Added a provider’s API and small-sample test report. Frontière AI reports 524,288-token model-list metadata, a 262,144-output-token ceiling check, tool/streaming integration, 25-question QA results, three-prompt first-token timing, one-generation throughput and a 15-prompt behavioral suite. Added its method and commercial-provider/raw-artifact/configuration limits; these are operator-reported October 6 checks newly inspected here, not Kingy tests or matched frontier benchmarks. The official 1M discrepancy remains unresolved. All six official pricing modes were rechecked and remain unchanged, as do the cited AA/Vals scores, historical evaluator costs and pending public weight/license status. Original provider report, methodology, official pricing.
October 6, 2026, 21:14:27 PDT / October 7, 04:14:27 UTC — Clarified tier prices and corrected earlier pricing uncertainty. Directly selected Mistral’s Batch, Priority and regional pricing controls; added all six sale tariffs, original-price relationships and dependent request/monthly budgets. Batch sale is $0.34/$0.035/$1.045 per million input/cached/output tokens; Regional Standard sale is $0.748/$0.077/$2.299. The official controls resolve the earlier unverified Batch stacking and regional-discount questions. Standard prices and historical evaluator costs are unchanged. This is newly inspected pricing evidence, not a new rate-change announcement or billing test. Exact direct-route promotion expiry, endpoint eligibility, context limits and public weights/license remain unresolved. Official pricing page, regional terms.
October 6, 2026, 19:11:07 PDT / October 7, 02:11:07 UTC — Added the gateway promotion end date. Vercel now states October 20, 2026 for promotional pricing. Current rates are unchanged; the exact cutoff time and direct Mistral/regional-route expiry remain unconfirmed. Benchmark results, higher historical evaluator costs, context discrepancy and October 31 weight ETA are unchanged. First-party gateway listing.
October 6, 2026, 17:15:30 PDT / October 7, 00:15:30 UTC — Added independent document and composite cyber results, current deployment terms and training disclosure. Newly verified AA evidence gives Large 4 50% on its Cyber Index and 18.6% GDP.pdf All-pass; added comparison models and the document benchmark’s grading setup. AA reports a two-week discount window and an approximately $0.57 tariff-adjusted task cost; the exact official expiry remains unconfirmed and historical evaluator costs are preserved. Mistral’s current technical paperwork distinguishes proprietary SaaS/partner terms and bespoke on-premise access from the planned public weight release. Added provider-disclosed training-data scale and collection dates. This is newly inspected published evidence, not a new Kingy model test. Prices and the October 31 weight ETA are unchanged. AA announcement, GDP.pdf, technical disclosure, training summary.
October 6, 2026, 13:15 PDT / 20:15 UTC — Added directly verified independent cyber evidence. AA reports 81.7% pass@1 for Large 4 Preview. Added the 131-task, 90-minute Stirrup setup and scoring limits. This is newly verified published evidence. Previously cited scores, prices and release details remain unchanged. Original evaluator page.
October 6, 2026, 11:09 PDT / 18:09 UTC — Clarified active counts and the expected weight-release date; added a limited developer report. Mistral’s card now says 52B active; its official upcoming-release page explains 49B in active experts versus 52B including embeddings and output layers, and lists October 31 as current ETA for
Mistral-Large-4.0-1T05-A52B. Weights and license remain pending. Standard pricing now explicitly labels sale and original rates; the amounts are unchanged. Added a small developer demo report with its output-budget, reasoning and cost limitations. Existing AA/Vals benchmark scores remain unchanged. Official release page, model card, developer report.October 6, 2026, 09:08 PDT / 16:08 UTC — Added provider-specific limits and access details. Vercel’s directly fetched AI Gateway table lists 524K context, 262K maximum output and the discounted token rates for
mistral/mistral-large-4. This differs from its search-indexed 1M label and does not resolve Mistral’s official 1M versus evaluator limits. Rechecked official prices and published evaluations; the cited figures remain unchanged. Mistral’s weights and license tabs still say “Coming soon.” Provider listing, official model card.October 6, 2026, 06:50 PDT / 13:50 UTC — Initial evidence snapshot. Added the official architecture and preview status, current discounted rates and higher evaluator price basis, independent broad/finance/legal/coding comparisons, and the unresolved 1M versus roughly 512K context discrepancy. No Kingy model inference tests have been run.
Sources and reporting method
We inspected Mistral’s announcement, model documentation, pricing and regional inference terms; the independent Artificial Analysis profile and Vals results; and the first-party competitor pricing linked above. The original Mistral announcement on X is the starting point for this coverage.
Benchmark figures are published results attributed to their operator or, where explicitly labeled, Mistral’s launch claims. Dollar examples are our arithmetic using the cited rates. We have not run paid model calls, matched local benchmarks or self-hosting trials. Kingy local tests: 0. The launch assessment can change as the preview evolves and independent evidence expands.