Evidence status: Source-audited launch-day first look; independent inference results pending
THE ANSWER IN ONE SENTENCE. Tencent Hy4 preview is worth an immediate API evaluation for teams building text-first coding and tool-using agents, provided they treat the launch benchmarks as vendor evidence, do not expect native image input, and do not mistake 49B active parameters for a model that fits on ordinary hardware.
Tencent has made Hy4 preview unusually easy to notice: a 770B-parameter Mixture-of-Experts model, one-million-token context, Apache 2.0 weights, and launch pricing far below Kimi K3. The release deserves a test. It does not yet deserve an unqualified performance crown.
The article’s August 28 notes describe a no-cost access check that reached Hy AI Studio and encountered a sign-in gate. The retained audit found no original access log, screenshot, receipt, or test ledger, so those details remain unverified editorial provenance rather than independently confirmed test evidence. No generated model response or performance test is claimed here.
The strongest verified story is therefore practical rather than theatrical: Hy4 is a text-first, commercially permissive model with an aggressive hosted price and a very high self-hosting floor. It is a credible bake-off candidate. It is not a consumer local model, and its base endpoint is not Kimi K3’s multimodal equivalent.
Commercial relationship for this article: None. This is based on Curtis Pyke’s direct confirmation on October 7, 2026.
1. Quick verdict
Verdict: Test Hy4 preview now if your workload is text-heavy, price-sensitive, and already runs through an OpenAI-compatible agent stack. Wait for independent runs if the purchase decision depends on visual understanding, reliable long tool chains, or a measurable coding win over Kimi K3.
Price basis: The cited price inputs were captured October 8, 2026. Tencent and the retained OpenRouter route list $0.834 per million input tokens, $2.501 per million output tokens, and $0.042 per million cached-input tokens in those captures. Pricing can change; these observations do not renew the original August 28 launch check. [S01, S08]
Testing scope: We inspected the retained official release, model cards, license, deployment recipes, provider metadata, benchmark appendix, and hardware sources. The safetensor byte values below are derived from retained model-card metadata, and the capacity figures are nominal arithmetic. We did not load a model or run paid inference.
Best for
- Text-first coding agents and office-analysis pipelines where token cost matters.
- Teams that need Apache 2.0 weights and fewer commercial-use conditions than Kimi K3’s custom license.
- Operators with H200/B200-class multi-GPU infrastructure, or teams happy to use a hosted endpoint.
- Buyers willing to run a controlled bake-off instead of selecting from launch charts.
Skip or wait if
- Image, screenshot, or video input is a non-negotiable requirement on the base API route.
- You need a proven independent win over Kimi K3 today.
- Your self-hosting plan is an 8xH100, 8x94GB, or 8x96GB server using Tencent’s official FP8 weights.
- You need preview stability, predictable reasoning length, or mature third-party runtime evidence.
Pros
- Aggressive hosted pricing, particularly for cached input.
- Apache 2.0 model release with official BF16 and FP8 weights.
- One-million-token context and documented tool/structured-output parameters.
- Official vLLM and SGLang recipes include the Hy4 reasoning and tool-call parsers.
- Tencent publishes limitations instead of presenting the preview as finished.
Cons
- No independent hands-on result was available in this test session.
- The hosted route is text-to-text; multimodal input is not documented.
- The October 8 model-card capture lists 813.77 GB of FP8 safetensor files, before other repository and runtime overhead.
- Launch benchmarks remain predominantly Tencent-run.
- Tencent itself warns about overlong reasoning and over-verification.
2. What Tencent Hy4 preview actually is
The official name is Hy4 preview. Tencent describes it as a next-generation model from the Tencent Hy Team and places it inside the broader Hunyuan lineage, but neither the launch post nor the official model card names the release “Hunyuan 4.” [S01, S02]
That makes Hunyuan 4 useful only as a search synonym, not as the product name. It is also ambiguous: Tencent already has small models whose names contain “Hunyuan-4B,” where 4B means four billion parameters rather than generation four. Editorial copy should write “Hy4 preview (Tencent’s Hunyuan-family model)” once, then use the official name.
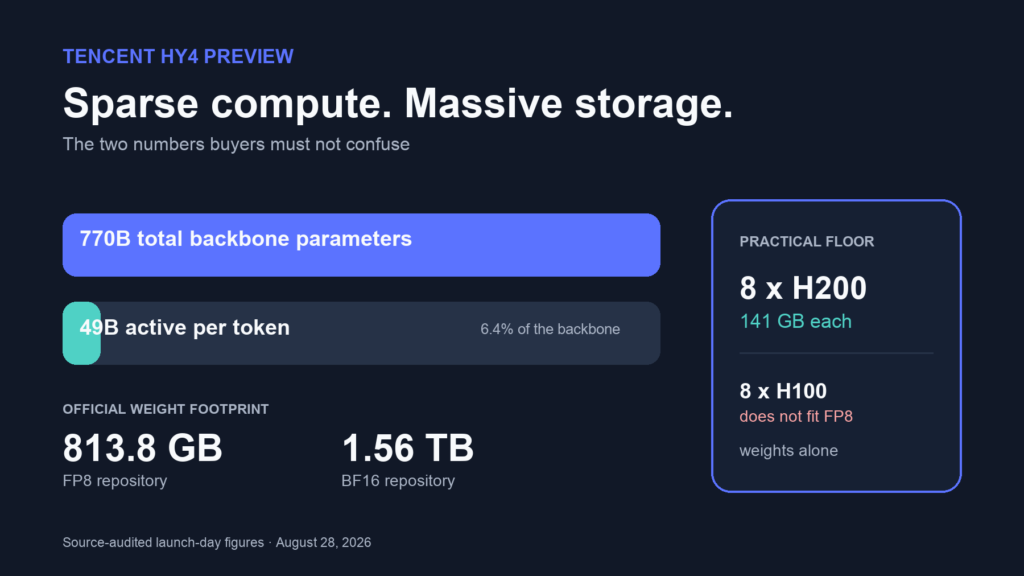
Hy4’s backbone has 770B total parameters and activates 49B per token. It uses 78 backbone layers: one dense feed-forward layer followed by 77 MoE layers, each with 256 routed experts and one shared expert. Each token selects eight routed experts plus the shared expert. Tencent also includes a native multi-token-prediction layer with 10B total and 0.7B active parameters for speculative decoding. [S02]
The architecture explains both the attraction and the trap. Only a fraction of the network performs most per-token computation, which can improve serving efficiency. All expert weights still need to be stored somewhere. “49B active” is a compute-path figure, not a promise that Hy4 has the memory footprint of a dense 49B model.
3. What we tested – and what we did not
| Evidence area | Scope and limits |
|---|---|
| Official materials reviewed | Retained Tencent announcements, model cards, license, deployment recipes, provider pages, hardware specifications, and benchmark appendix. |
| Calculated from retained metadata | Example API workload costs and nominal GPU-capacity arithmetic. Repository safetensor byte totals are labeled separately below; no local model-load or runtime test is claimed. |
| Not tested | Generated coding quality, document accuracy, tool-call completion rate, TTFT, output throughput, million-token retrieval, and visual understanding. |
| Earlier access note | The August 28 article described a sign-in gate after selecting Hy4 preview and High reasoning. No original access log, screenshot, receipt, or test ledger was retained, so this remains unverified editorial provenance. |
| Authorization boundary | No paid API call, new account, software installation, or Kimi credit consumption was authorized. |
The article previously described a 33-case test pack and an inert harness. The independent audit found no retained JSONL pack, harness, or manifest, so this review does not certify that pack’s contents or credit it as an executed or independently verified test. No tasks from that described pack are claimed as run.
4. Specifications: what the numbers actually mean
| Specification | Hy4 preview | Evidence or limit |
|---|---|---|
| Release date | August 28, 2026 | Tencent announcement [S01] |
| Architecture | Mixture of Experts | Tencent model card [S02] |
| Backbone parameters | 770B total / 49B active | Excludes native MTP layer [S02] |
| MTP layer | 10B total / 0.7B active | Used for speculative decoding [S02] |
| Backbone layers | 78 | One dense, 77 MoE [S02] |
| Context | 1,048,576 tokens on OpenRouter | Tencent says 1M; provider exposes exact limit [S08] |
| Maximum completion | 64,000 on Tencent Cloud and NovitaAI; 131,072 on DeepInfra; 262,144 on SiliconFlow | Provider-specific values in the October 8, 2026 capture [S08] |
| Input/output modality | Text to text | OpenRouter public metadata; HF task is Text Generation [S02, S08] |
| Hosted model ID | tencent/hy4-preview |
OpenRouter [S08] |
| Official self-host model | tencent/Hy4-preview-FP8 |
vLLM/SGLang recipes [S03, S04] |
| License | Apache 2.0 | Official license file [S05] |
| BF16 safetensor files | 1,559.98 GB | October 8 model-card totalFileSize metadata [S06]; excludes other repository/runtime files |
| FP8 safetensor files | 813.77 GB | October 8 model-card totalFileSize metadata [S07]; excludes other repository/runtime files |
The exact hosted context is encouraging, but context capacity is not context quality. A one-million-token input limit does not prove accurate retrieval across the whole window, resistance to distraction, or a usable latency/cost profile at maximum length. Those need controlled tests.
5. Coding and document evidence: promising, still vendor-run
Tencent’s benchmark appendix is more informative than the corporate headline. It reports results across coding, terminal work, search, office tasks, connected-tool evaluations, and science. The chart also discloses that many competitor values marked with an asterisk came from Tencent’s own testing, sometimes with different harnesses or multiple reported settings. [S02]
Selected shared rows illustrate why a universal winner would be premature:
| Benchmark | Hy4 preview | Kimi K3 shown by Tencent | Responsible reading |
|---|---|---|---|
| SWE-bench Multilingual | 82.9 | 80.8* | Narrow Hy4 lead in Tencent’s chart |
| SWE-bench Pro | 65.7 | 63.3* | Narrow Hy4 lead |
| DeepSWE | 64.3 | 67.5 / 74.0* | Kimi leads the displayed variants |
| Terminal-Bench 2.1 | 85.4 | 88.3 / 85.7* | Setting-sensitive; no clean winner |
| OfficeQA Pro | 66.2 | 65.4* | Effectively tied without uncertainty bars |
| MCP-Atlas public | 83.7 | 84.2 / 82.8* | Overlapping displayed variants |
| Toolathlon-Verified | 74.1 | 76.5 / 74.7* | Kimi slightly ahead in the shown runs |
| GPQA Diamond | 92.3 | 93.5 / 92.8* | Both high; Kimi slightly ahead |
* denotes results Tencent says came from its own testing. Harness, scaffold, effort, and repeated-run rules vary by row; the table is a coverage map, not a synthetic scorecard.
Tencent’s internal human study offers a second signal. Its 163 internal experts scored outputs on 203 engineering tasks. Hy4 averaged 2.99 out of 4.00 versus 2.94 for Kimi K3, with Hy4 winning 51.2%, tying 7.9%, and losing 40.9% of the comparisons. [S01, S02]
The honest headline is the one Tencent itself used: slightly ahead. A 0.05-point average gap and a roughly 41% loss rate do not establish dominance. They establish that Hy4 belongs in the same evaluation conversation.
For document work, OfficeQA Pro at 66.2 is directionally interesting, as are Tencent’s claims around cross-file analysis and artifact creation. But an office benchmark is not a substitute for citation checking, spreadsheet correctness, or a usable DOCX/PPTX workflow. Those four tests remain queued, not passed.
6. Multimodal reality check
Hy4 preview’s public hosted route is text-to-text. OpenRouter lists only text as an input modality; the official Hugging Face task is Text Generation; and the model card quickstart supplies text messages, not image content. [S02, S08]
Tencent’s WorkBuddy and CodeBuddy products may accept screenshots or provide visual feedback loops. That does not prove the Hy4 base endpoint is natively multimodal. A product can combine several models, OCR, computer-vision tools, and agent scaffolding behind one interface.
Kimi K3 is different. Moonshot’s paper and model card describe native text, image, and video understanding, and OpenRouter exposes those three input modalities. [S10, S11, S14]
If screenshots, charts, UI debugging, or video are central to the workload, Kimi K3 has the documented advantage today. Hy4 should receive no multimodal score until Tencent publishes an image-capable route or a repeatable visual test proves one.
7. Tool calling: support is not reliability
The integration surface is credible. OpenRouter exposes tools, tool_choice, structured output, JSON response formats, and reasoning controls for Hy4. Tencent’s vLLM recipe enables automatic tool choice and uses dedicated hy_v4 tool and reasoning parsers. [S04, S08]
That proves support. It does not prove the model consistently selects the right function, produces valid arguments, recovers from tool errors, resists prompt injection in tool output, or avoids claiming success after a failed action.
Tencent reports 83.7 on MCP-Atlas public and 74.1 on Toolathlon-Verified. Those are useful launch indicators, but our 20-case reliability suite was not run. The article therefore withholds malformed-call, unnecessary-call, recovery, and false-success rates.
8. Hy4 vs Kimi K3
| Decision field | Tencent Hy4 preview | Moonshot Kimi K3 |
|---|---|---|
| Release discussed | August 28 preview | July 2026 K3 release |
| Parameters | 770B total / 49B active backbone | 2.8T total / 104B active |
| Context | 1,048,576 | 1,048,576 |
| OpenRouter output limits in October 8 capture | 64,000 Tencent Cloud and NovitaAI; 131,072 DeepInfra; 262,144 SiliconFlow | Provider-specific values observed October 8, 2026; route limits can change [S08] |
| Modality | Text input, text output | Text/image/video input, text output |
| License | Apache 2.0 | Custom Kimi K3 License |
| Official API list price | $0.834 in / $2.501 out / $0.042 cache | $3 in / $15 out / $0.30 cache |
| Cheapest observed OpenRouter route | Same Tencent price | $2.55 in / $12.75 out / about $0.256 cache |
| Coding evidence | Strong Tencent-reported results; independent run pending | Strong vendor and multi-provider ecosystem; independent matched run pending |
| Tool reliability | Interface and vendor benchmarks documented; not independently measured | Interface documented; not independently matched here |
| Visual work | Base route not documented for image input | Native image and video input documented |
| Self-hosting floor | About 813.77 GB of FP8 safetensor files before other repository/runtime overhead | Depends on the exact Kimi checkpoint and quantization; no verified file-total comparison is established in this review |
| Best fit | Low-cost text agents; Apache-licensed deployment | Multimodal and very-long-output workflows; broader provider choice |
The choice is less mysterious than the benchmark wall suggests. Pick Hy4 for cost, permissive licensing, and text-first agent evaluation. Pick Kimi K3 when native vision is required or a mature multi-provider market matters more than price. Run both when coding quality is the deciding factor.
9. API cost and provider-reported latency
| Route | Input / 1M | Cached input / 1M | Output / 1M | Context |
|---|---|---|---|---|
| Hy4 preview, Tencent/OpenRouter | $0.834 | $0.042 | $2.501 | 1,048,576 |
| Kimi K3, official list | $3.00 | $0.30 | $15.00 | 1,048,576 |
| Kimi K3, lowest observed OpenRouter route | $2.55 | about $0.256 | $12.75 | 1,048,576 |
For one million uncached input tokens plus 100,000 output tokens, the retained October 8 price observations yield about $1.0841 for Hy4, $4.50 for Kimi K3 at Moonshot’s list price, and $3.825 for the lowest observed OpenRouter Kimi route. On those inputs Hy4 is about 75.91% below Kimi’s list-price workload and about 71.66% below the lowest observed OpenRouter workload. These are dated route-price calculations, not guaranteed current checkout prices.
The price gap widens in cache-heavy agents. Ten million cached-input tokens, one million uncached input tokens, and 500,000 output tokens cost about $2.50 on Hy4 versus $13.50 at Kimi’s list price.
OpenRouter’s historical launch notes listed 17 Kimi endpoints and one Tencent Hy4 FP8 endpoint. The original August ledger for those counts was not retained, so they remain reported historical observations rather than independently recertified provider counts. The retained October 8 capture showed four Hy4 provider routes: Tencent Cloud, NovitaAI, DeepInfra, and SiliconFlow. Routes change, so check the live route list; these snapshots do not establish comparable availability or failover reliability. [S08, S09, S14]
10. License: Hy4’s quiet advantage
Hy4 preview’s weights and accompanying release are under Apache 2.0. That is a familiar, permissive license for commercial use, modification, and redistribution, subject to its notice and patent terms. [S05]
Kimi K3 uses a custom license. It grants broad rights, but a Model-as-a-Service operator whose affiliated group exceeds $20 million in revenue over a consecutive 12-month period must make a separate agreement with Moonshot before commercial use. Products exceeding specified user or revenue thresholds also face a prominent Kimi K3 branding requirement, with exceptions for internal use and official/certified routes. [S12]
This is not legal advice, but it is a real procurement difference. For teams embedding an open-weight model into a service, Hy4’s standard license may reduce review friction even before token price enters the conversation.
11. Hy4 hardware requirements
The repository metadata is the clearest reality check. Hy4’s BF16 repository contains about 1,559.98 GB of safetensors (1,452.85 GiB). The official FP8 repository contains about 813.77 GB of safetensors (757.88 GiB). [S06, S07]
Those are weight files, not complete serving-memory requirements. The runtime also needs room for quantization metadata, temporary buffers, CUDA graphs, communication workspaces, the MTP layer’s execution state, and KV cache. Context length and concurrency can make KV-cache demand material.
| Configuration | Aggregate nominal memory | Official FP8 weights fit? | Practical reading |
|---|---|---|---|
| 8x H100 80GB | 640 GB | No | About 174 GB short before runtime overhead |
| 8x H100 NVL 94GB | 752 GB | No | About 62 GB short before overhead |
| 8x RTX PRO 6000 96GB | 768 GB | No | About 46 GB short; PCIe workstation topology also matters |
| 8x H200 141GB | 1,128 GB | Yes, by capacity | Plausible minimum for Tencent’s 8-way FP8 recipe; about 314 GB remains for runtime and cache |
| 8x B200 180GB | 1,440 GB | Yes | More comfortable FP8 headroom |
| 8x B300 288GB | 2,304 GB | Yes | Enough capacity for BF16 weights, with roughly 744 GB nominal headroom |
| 8x B200 180GB, BF16 | 1,440 GB | No | BF16 weights alone exceed node memory |
NVIDIA lists 80/94GB for H100, 141GB for H200, 180GB for B200, 288GB for B300, and 96GB for RTX PRO 6000 Blackwell variants. [S15-S18]
What about 8-bit or 4-bit consumer quantization?
The official FP8 files are already roughly the size expected from an eight-bit 770B-class model plus higher-precision tensors and metadata. A hypothetical ideal four-bit backbone is about 385 GB before scales, metadata, embeddings, MTP weights, runtime buffers, and cache. A realistic package could land materially above 400 GB.
That means:
- 8x48GB equals 384 GB and misses even the idealized four-bit backbone before overhead.
- 4x96GB also equals 384 GB and has the same problem.
- 6x96GB or 8x96GB could have raw capacity for a future four-bit release, but Tencent has not published or validated that configuration.
- CPU or system-memory offload may make loading possible, but interconnect and memory bandwidth can make generation impractically slow.
The realistic recommendation is simple: use the hosted API unless the organization already operates H200/B200/B300-class infrastructure and has a reason to own the serving stack.
12. Known limitations and launch-day risks
Tencent names two preview defects: the model can reason longer than necessary on complex tasks and can over-verify its own work. [S02] Both can affect latency and cost even when per-token pricing is low.
Other practical risks follow from the evidence:
- Provider availability: The original launch notes reported one Hy4 endpoint but lack a retained provider-count ledger. The October 8 capture lists four routes; neither snapshot establishes their availability or failover reliability.
- Documentation churn: deployment guidance and model metadata changed during launch day; pin revisions.
- No independent long-context result: capacity is verified, retrieval quality is not.
- No independent tool-call rate: function support is verified, reliability is not.
- Product/model ambiguity: WorkBuddy capabilities should not be attributed automatically to the Hy4 base endpoint.
- Preview semantics: Tencent says more Hy4-series models are coming, so today’s route may not be the final product shape.
13. Final verdict
Hy4 preview earns a place in the next text-agent bake-off. Its combination of Apache 2.0 weights, one-million-token context, official tool-call integration, and unusually low API pricing is substantively useful. The release is more compelling as an economic and deployment option than as proof that Tencent has beaten Kimi K3.
Use Hy4 for a controlled text-first evaluation, not for a victory lap. Pin the exact route, measure reasoning length, run tool failures as well as successful calls, and price the real cached/uncached mix. Choose Kimi K3 when native vision is required. Choose hosted Hy4 unless your infrastructure starts at eight H200-class GPUs for FP8.
Final line: Evaluate Hy4 for inexpensive text agents and permissive deployment, not as a consumer-local or natively multimodal model. With those conditions understood, it earns our provisional recommendation to test.
14. Tencent Hy4 preview FAQ
Is Tencent Hy4 preview the same thing as Hunyuan 4?
Not as an official product name. Tencent calls the release Hy4 preview and identifies it as part of the Hunyuan/Tencent Hy lineage. “Hunyuan 4” is best treated as an informal search phrase and can be confused with Tencent’s older Hunyuan-4B small-model naming.
Is Hy4 preview open source?
Tencent publishes model weights and supporting code under Apache 2.0. “Open-weight model with an Apache-licensed repository” is the most precise description; it does not mean every training dataset or training-system component is published.
Can Hy4 preview understand images?
The public route checked here is text-to-text, and the official Hugging Face task is Text Generation. Do not assume image input from WorkBuddy marketing. Kimi K3 documents native image and video input.
How much does the Hy4 API cost?
In the October 8 retained price captures: $0.834 per million input tokens, $2.501 per million output tokens, and $0.042 per million cached-input tokens. Pricing can change; recheck immediately before publication or procurement.
Can Hy4 run on eight H100 GPUs?
Not with the 813.77 GB of FP8 safetensor files on an 8x80GB or 8x94GB node; those files alone exceed the aggregate nominal memory, before other repository files or runtime overhead. The official --tensor-parallel-size 8 command specifies shard count, not a promise that every eight-GPU SKU fits.
What hardware is realistic for Hy4 FP8?
An 8xH200 141GB node is the first common eight-GPU configuration with clear weight capacity and meaningful room for runtime overhead. 8xB200 provides more margin. Actual concurrency and context targets still need memory profiling.
Is Hy4 better than Kimi K3?
Tencent’s internal study places Hy4 slightly ahead, while its benchmark appendix shows mixed row-level results. Without matched independent runs, the defensible conclusion is that they are peers with different strengths: Hy4 for cost and license; Kimi for multimodality and provider breadth.
Does Hy4 support tool calling?
Yes at the interface level. OpenRouter documents tools, tool choice, and structured output, and Tencent provides dedicated serving parsers. Reliability across malformed arguments, errors, and long chains remains unmeasured here.
15. Methodology and source notes
This revision uses retained primary captures at their recorded observation times, including October 8 model-card metadata, provider limits, and price observations. The original August 28 launch-era claims remain historical and are not renewed by this revision. Safetensor byte values are converted to decimal GB; GPU-fit arithmetic compares those file sizes with nominal vendor-published memory and does not treat remaining capacity as guaranteed usable KV cache.
Benchmark values are reproduced only to explain Tencent’s evidence. No vendor benchmark is relabeled as a Kingy result. Provider pricing, availability, and latency are volatile and require a publication-day recheck.
The independent audit binds the retained official captures and records their observation times. It found no original access log, test ledger, JSONL pack, or inert harness in the retained bundle, so this review does not claim those artifacts were supplied or independently verified.
Residual uncertainties
- No independent Hy4 or Kimi outputs are present in the retained evidence bundle. The article’s Hy4 sign-in-gate note remains unverified editorial provenance; no paid inference or Kimi credit use is claimed.
- Hy4’s effective TTFT, output speed, retry rate, and reasoning-token behavior remain unmeasured.
- The checked hosted route is text-only; Tencent may add a separate multimodal Hy4 route later.
- No official four-bit Hy4 checkpoint or validated workstation configuration was found.
- Launch-day provider counts, prices, and repository documentation can change quickly.
Official sources
- Tencent launch announcement — S01
- Tencent Hy4 preview model card and FP8 model card — S02, S03
- Tencent-Hunyuan GitHub repository and Apache 2.0 license — S04, S05
- OpenRouter Hy4 model metadata — S08, S09
- Moonshot Kimi K3 paper, model card, and license — S10-S13
- OpenRouter Kimi K3 route data — S14
- NVIDIA H100, H200, B200/B300, and RTX PRO memory specifications — S15-S18
The Kingy Brief
Get The Kingy Brief.
AI changes, original tests and one practical thing to try. Fridays at 09:00 Vancouver time.
Free · Double opt-in · Unsubscribe anytime
Sign up for The Kingy Brief on Beehiiv.
Signup help and newsletter schedule
Signup form provided by Beehiiv. After submitting, check your inbox for "Confirm your subscription to The Kingy Brief" and open its confirmation link. Check Spam or Promotions if you cannot find it.
Fridays at 09:00 Vancouver time: source-checked AI changes, original tests and one practical thing to try. We skip a week when there is not enough verified material. Free. Unsubscribe anytime.