Verdict: GPT-6 Astra now has the highest controlled-harness point score at 74.1%, but it is not a statistically isolated winner. Gemini 3.8 Flash (73.8%), Claude Opus 5 (73.6%) and GPT-5.6 Sol (72.7%) sit inside overlapping published uncertainty bands. Gemini 3.8 Flash is the best economic default in this snapshot: its recorded $2.36 mean attempt cost and 10m 05s median are dramatically lower than the other near-top rows. Claude Opus 5 with Claude Code still leads the separate native-agent table at 50.0%. Claude Fable 5.1 now has an independent native result—45.6% with Claude Code—but still lacks a common-harness DeepSWE row.
The practical answer remains profile-dependent. Choose Gemini 3.8 Flash for efficient controlled API work, GPT-6 Astra when the highest point estimate matters more than cost, Opus 5 with Claude Code for the strongest demonstrated native workflow, and DeepSeek when compute cost is the hard constraint. Fable 5.1 is now a credible native contender, not the overall evidence-backed champion. This review keeps equivalent-harness model evidence separate from native coding-product evidence because the agent loop, tool policy and verification behavior can change the answer as much as the model.
Evidence checked: September 8, 2026. DeepSWE snapshot generated September 3, 2026. SWE-Marathon v1.1 dataset retrieved September 8, 2026. Kingy controlled test referenced below: August 2, 2026. Prices are list prices or benchmark-recorded spend at those dates and may change.
Muse model-version and Mythos access context corrected October 11, 2026. Benchmark datasets, prices and original Kingy test evidence retain the dated snapshot basis above.
Eight-week update log
- Week 1 — September 8, 2026: Added GPT-6 Astra and Gemini 3.8 Flash to the controlled track, added independent native-agent rows for Astra and Fable 5.1, refreshed pricing and replaced all three comparison charts. The recommendation changed: Astra leads the point estimate, Gemini 3.8 leads the near-frontier value case, and Opus 5 remains the native-product leader.
- Original publication — September 1, 2026: Established the controlled-versus-native split and the initial Fable 5.1 evidence boundary.
The short answer: which model should you use?
| Developer decision | Best current choice | Why | Main caveat |
|---|---|---|---|
| Maximum controlled resolution | GPT-6 Astra | Highest DeepSWE v1.1 point result: 74.1% | Top-four uncertainty bands overlap |
| Best balance of success, speed and spend | Gemini 3.8 Flash | 73.8% at about $2.36 per attempt and a 10m 05s median | Benchmark spend reflects the captured snapshot; production routing may differ |
| Strongest native-agent result | Claude Opus 5 + Claude Code | 50.0% on SWE-Marathon v1.1 | Native-product scores are not comparable with common-harness percentages |
| Lowest API compute cost | DeepSeek V4-Pro or V4-Flash | About $0.38 and $0.19 of benchmark compute per resolved attempt, respectively | Longer runs, more intervention risk and lower resolved rate |
| Most important controlled retest | Claude Fable 5.1 | 45.6% in Claude Code is independent evidence; cache economics remain promising | No common-harness DeepSWE score yet |
| Fast, low-cost interactive work | Gemini 3.8 Flash | Near-top resolution with the fastest median among the leading rows | Antigravity’s native-agent result is not yet on SWE-Marathon |
That answer is less exciting than a single leaderboard winner, but it matches how engineering teams actually buy tools. A model that saves three dollars and creates an hour of review is not cheap. A model that wins one more task but takes twice as long is not automatically productive. The unit that matters is a reviewed, accepted repository change.
What Fable 5.1 changes—and what it does not prove
Anthropic released Claude Fable 5.1 and Claude Mythos 5.1 on September 1. The company describes them as the same underlying model under different safeguard regimes. Fable is the general production model; Anthropic’s verified cybersecurity and life-sciences programs also provide access to Mythos under program-specific safeguards. For normal software engineering, Mythos is not a second intelligence tier and should not be double-counted.
Fable 5.1 costs $10 per million input tokens and $50 per million output tokens. That looks expensive next to Opus 5 at $5/$25 and Sol’s promotional $4/$20, but Fable’s cache reads cost only $0.25 per million tokens. Long agent trajectories repeatedly reread a repository, so cache economics can matter more than the headline input rate. Anthropic estimates about 25% lower typical workload cost than Fable 5 and up to 45% lower cost on highly agentic work. Those are vendor estimates, not Kingy measurements.
The launch numbers are impressive: Anthropic reports 73.4% on CursorBench 3.2, 55.8% on Terminal-Bench 4.0 and 52.6% on Terminal-Bench-Science 0.1. Mythos reaches a vendor-reported 60.9% on Terminal-Bench 4.0. Fable 5.1 has since appeared in SWE-Marathon v1.1 at 45.6% with Claude Code, based on 73 successes across 160 trials. That is meaningful independent native-product evidence, but it does not fill the missing common-harness DeepSWE cell. The correct conclusion is “credible contender with one evidence track complete,” not “new champion.”
How this comparison was tested
This article combines three evidence layers and keeps them separate:
- Controlled model track: DeepSWE v1.1 puts models behind the same mini-swe-agent harness across 113 long-horizon tasks from 91 repositories and five languages. Most configurations have four whole-suite passes. Timeouts and context failures count as failures; provider, verifier and network errors are excluded. This is the best evidence here for comparing model behavior with a common tool loop.
- Native product track: SWE-Marathon v1.1 evaluates complete model-agent pairings over 20 task clusters and eight correlated runs per cluster. This answers a different question: what happens when you buy the product, not just the model API?
- Kingy’s prior controlled test: DeepSeek V4-Flash and GPT-5.6 Sol were run on the same 20 SWE-bench Verified tasks in Codex, with matching task specifications and acceptance rules. That test is narrower and single-run, but it adds request, cache, wall-time and bill evidence unavailable from a headline score.
Testing limit: Kingy did not purchase and run a new multi-model API sweep for this update. We downloaded and audited the current DeepSWE and SWE-Marathon datasets, reanalyzed our August test, and verified vendor documentation and prices. We did not run Fable 5.1, GPT-6 Astra or Gemini 3.8 Flash ourselves. Results called “vendor-reported” are never blended into the independent winner table.
Controlled-model results: same agent harness
The table below uses each model’s strongest published DeepSWE v1.1 configuration. “Cost” is the benchmark artifact’s recorded mean model spend per scored attempt, not a subscription estimate. The live interface can revalue spend as tariffs change; every dollar figure in the table and charts therefore comes from the checksummed September 3 JSON snapshot named in the appendix. Median time is wall time per attempt. Fable 5.1 and Mythos 5.1 appear for completeness but are not ranked without a run in this harness. Astra’s recorded spend uses the benchmark artifact’s prelaunch cost basis and should not be treated as a quote at today’s standard API price.
| Model / effort | Resolved rate | Mean cost / attempt | Median time | Evidence status |
|---|---|---|---|---|
| GPT-6 Astra / xhigh | 74.1% | $6.52 | 15m 59s | Independent, 452 attempts; 95% CI ±2.9 |
| Gemini 3.8 Flash / high | 73.8% | $2.36 | 10m 05s | Independent; 95% CI ±1.4 |
| Claude Opus 5 / max | 73.6% | $11.84 | 30m 01s | Independent, 444 attempts |
| GPT-5.6 Sol / max | 72.7% | $8.39 | 16m 54s | Independent, 450 attempts |
| Claude Fable 5 / xhigh | 69.9% | $13.41 | 20m 32s | Legacy predecessor; 452 attempts |
| GPT-5.6 Terra / max | 69.6% | $4.95 | 15m 28s | Independent |
| Kimi K3 / max | 68.5% | $4.65 | 66m 13s | Independent |
| Grok 4.6 / medium | 67.5% | $3.45 | 14m 20s | Independent |
| DeepSeek V4-Pro-0813 / max | 62.8% | $0.24 | 35m 05s | Independent |
| Qwen3.8-Max / xhigh | 57.5% | $3.73 | 40m 24s | Independent |
| Meta Muse Spark 1.2 / xhigh | 54.9% | $3.70 | 13m 05s | Independent; Spark 1.2 build evaluated here |
| DeepSeek V4-Flash / max | 53.3% | $0.10 | 23m 04s | Independent |
| Claude Fable 5.1 | Not tested | — | — | Vendor CursorBench 3.2: 73.4% |
| Claude Mythos 5.1 | Not tested | — | — | Program-limited; vendor Terminal-Bench 4.0: 60.9% |
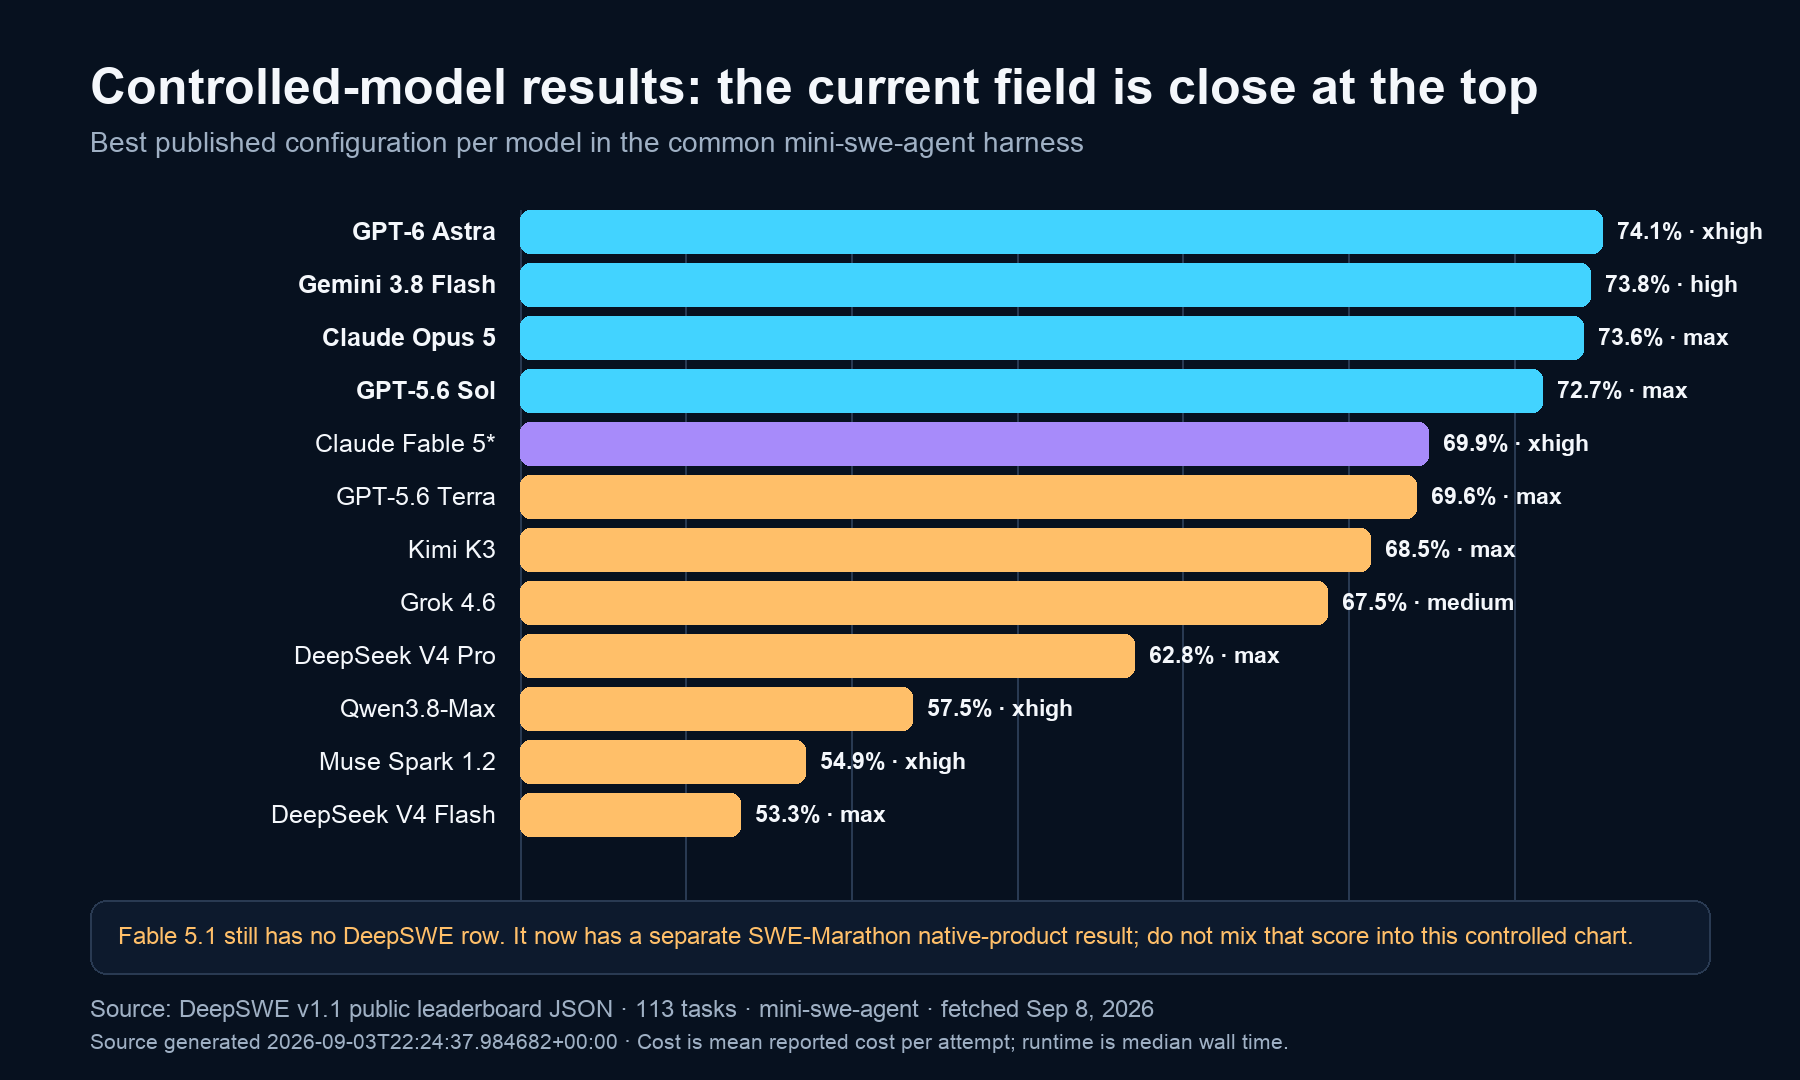
The most important detail is the uncertainty, not the decimal. Astra, Gemini 3.8, Opus 5 and Sol all have overlapping published intervals around their 72.7%–74.1% point estimates. “Astra leads” is a fair description of the point estimate; “Astra is conclusively better” is not. A team choosing among the top four should give price, runtime, integration and its own acceptance tests more weight than a sub-two-point gap.
Gemini 3.8 Flash’s operational advantage is clearer. Its 10m 05s median is about six minutes faster than Astra, seven minutes faster than Sol and twenty minutes faster than Opus max. Its $2.36 recorded mean attempt spend is also the lowest among the near-top group. That makes Gemini the strongest controlled-harness default for teams optimizing accepted work per dollar and developer-day, subject to verifying the same advantage in their chosen agent product.
Fable 5.1 may still change the controlled frontier. Its cache-read price is unusually favorable for long trajectories, and its new 45.6% native result is close to the 50.0% leader. But the older Fable 5 row costs more than Opus, Sol or Astra in DeepSWE despite a lower resolved rate. Until 5.1 gets the same task set, retries, timeouts and verifier, its controlled cost per resolution remains unknown.
Equal-dollar and equal-time winners are different
A single maximum-effort table hides the real buying decision. The Pareto frontier asks a better question: which configurations are not simultaneously beaten on both resolved rate and resource use?
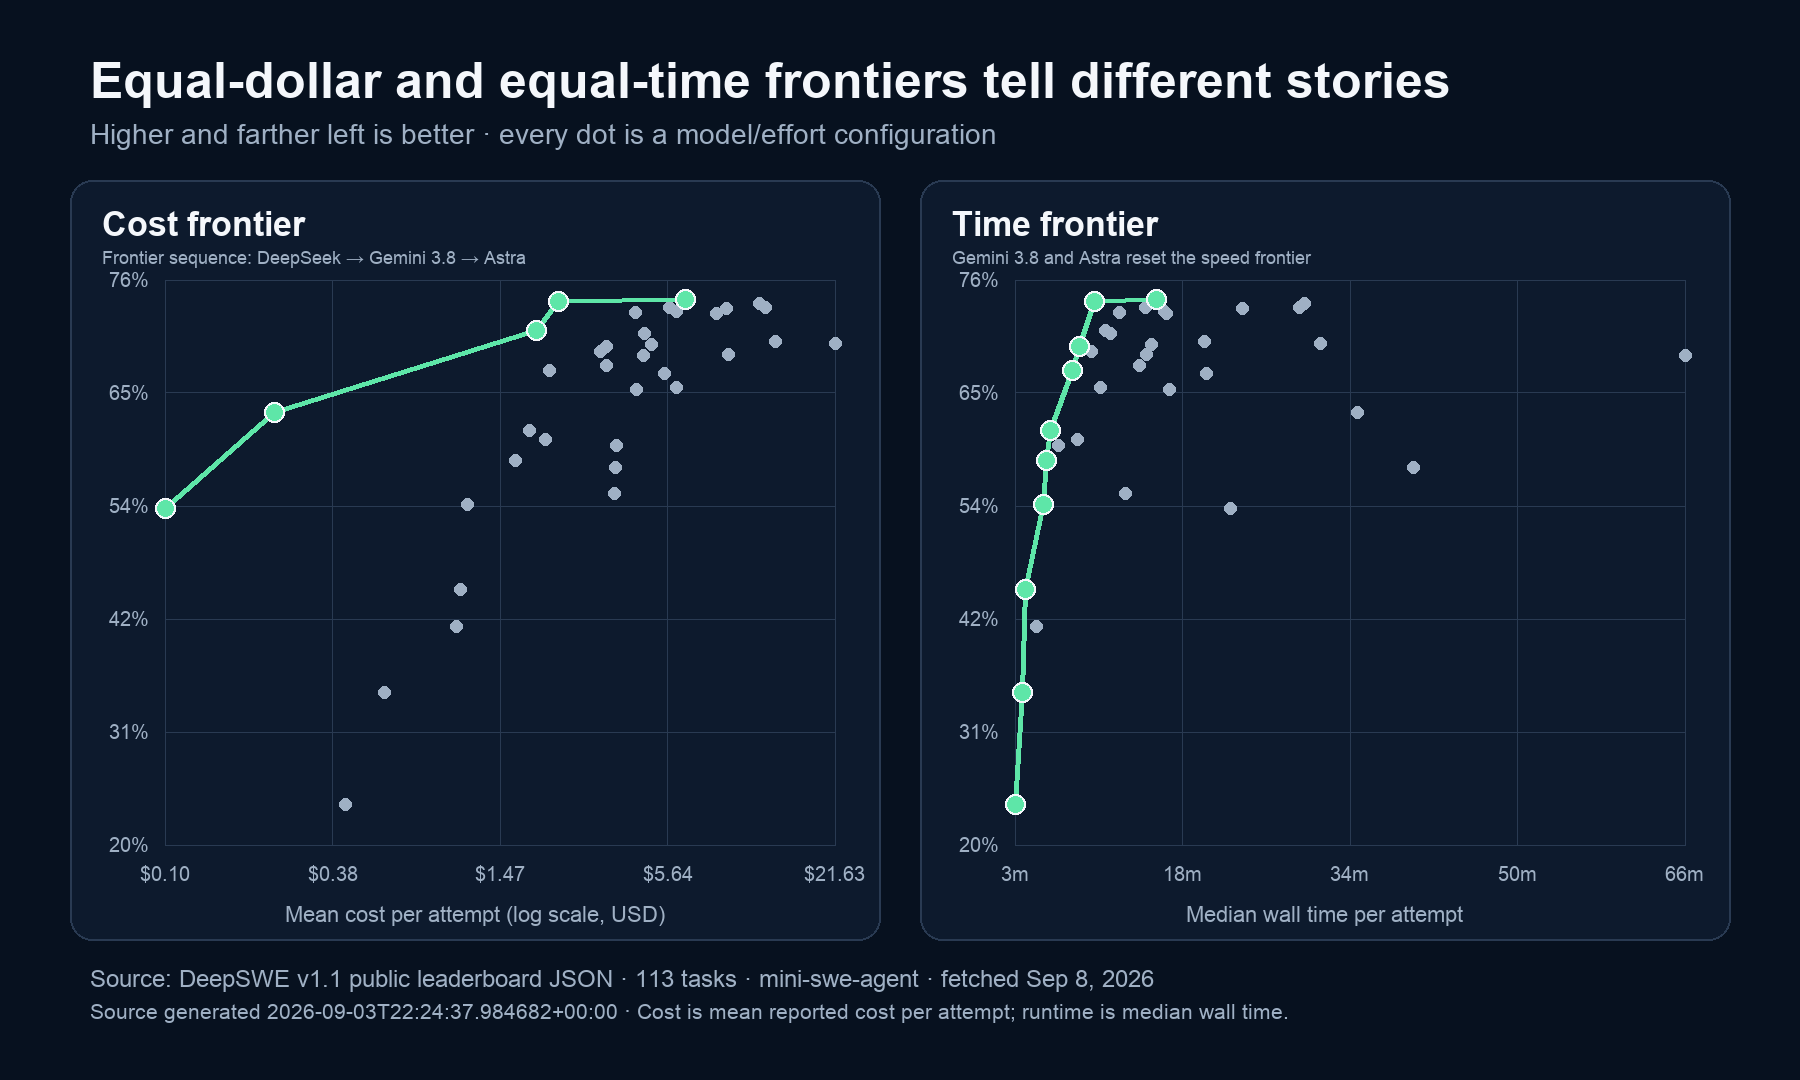
Under an equal-dollar rule, DeepSeek owns the low end. V4-Flash max averages about $0.10 per attempt at 53.3%; V4-Pro reaches 62.8% for about $0.24. Gemini 3.8 Flash is the decisive next step at 73.8% for $2.36, and Astra buys the final 0.3 points at a recorded $6.52. Opus and Sol are dominated on this two-axis snapshot even though their native integrations and operational histories may justify them.
Under an equal-time rule, Gemini 3.8 Flash resets the frontier: 73.8% at a 10m 05s median. Astra is slower at 15m 59s but has the highest point estimate. Grok’s best row has a 14m 20s median, Terra is 15m 28s and Sol is 16m 54s, but all three resolve fewer tasks. Kimi K3’s 68.5% looks competitive in isolation, yet a 66-minute median makes it a poor throughput choice in this configuration.
The maximum-capability scenario favors Astra’s 74.1% point estimate, while Opus 5 retains the strongest native-agent score. Even there, the data recommends escalation rather than defaulting every ticket to maximum effort. Start with a value configuration, preserve the failing transcript and tests, then escalate the unresolved tail.
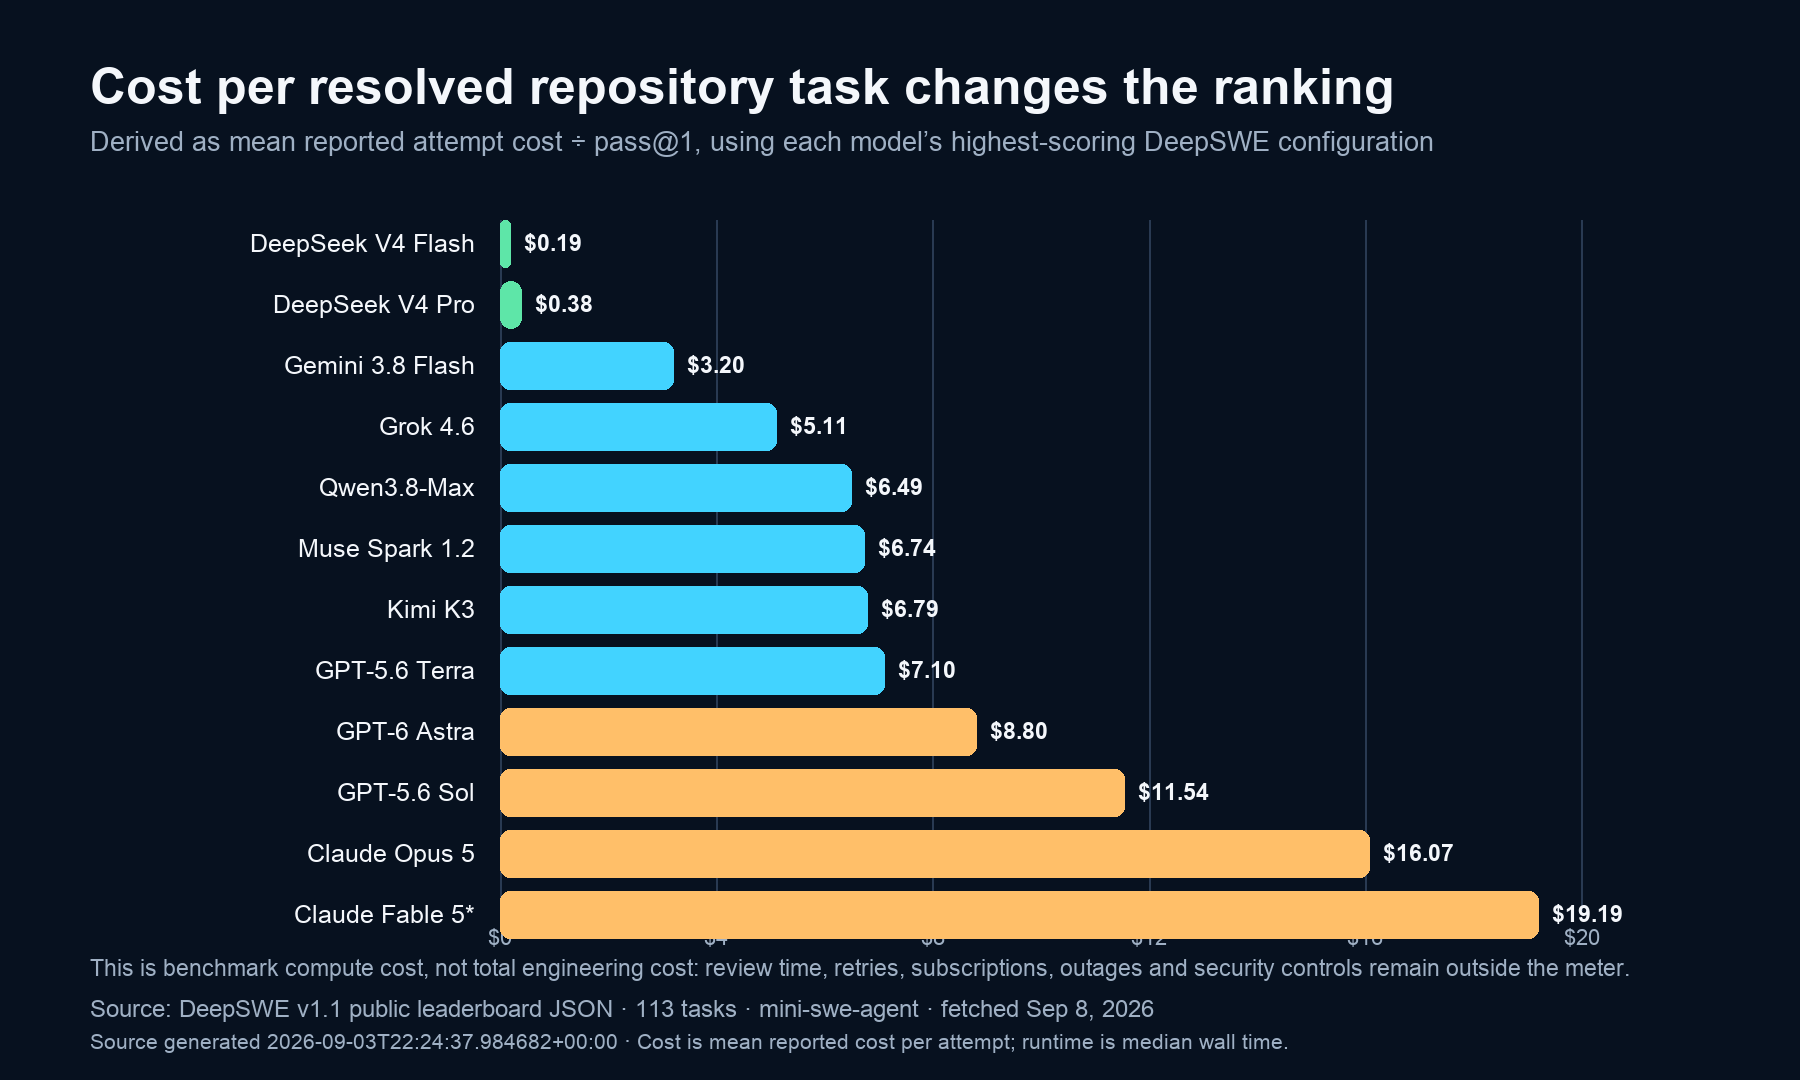
Cost per resolved repository task
| Model | Benchmark compute / resolved attempt | What the number misses |
|---|---|---|
| DeepSeek V4-Flash | $0.19 | More failures, longer trajectories and review risk |
| DeepSeek V4-Pro | $0.38 | Slower median and less mature agent-product integration |
| Gemini 3.8 Flash | $3.20 | Agent harness and promotional pricing effects |
| Grok 4.6 | $5.11 | Lower maximum resolved rate |
| Qwen3.8-Max | $6.49 | Long runtime in the tested configuration |
| Meta Muse Spark 1.2 | $6.74 | Contributor pricing has a different data-use trade-off |
| Kimi K3 | $6.79 | Very long median trajectory |
| GPT-5.6 Terra | $7.10 | Review and subscription costs excluded |
| GPT-6 Astra | $8.80 | Derived from benchmark artifact spend, not today’s standard API quote |
| GPT-5.6 Sol | $11.54 | Review and subscription costs excluded |
| Claude Opus 5 | $16.07 | Review and subscription costs excluded |
| Claude Fable 5 predecessor | $19.19 | Not the new 5.1 model |
This is why “cheap tokens” and “cheap engineering” are different claims. In Kingy’s earlier 20-task test, DeepSeek V4-Flash accepted 19 of 20 tasks versus Sol’s 17 of 20 and cost only $0.3433 in total. But DeepSeek took 1.93 times as long, made 723 requests versus 289, and depended on a 97.44% cache-hit rate. The accepted task cost was about $0.018 for DeepSeek. That is a spectacular API bill result, but it also exposes the operational condition: the cache and provider path must remain stable through a much longer trajectory.
The 20-task result should not overrule the 113-task board. It was Python-heavy, included 19 pytest tasks and one requests task, and used one run per task. It does show why teams should measure their own repositories instead of importing a universal ranking.
Native-agent results: the harness changes the answer
Model-only comparisons do not tell you what happens in Claude Code, Codex, Grok Build or another complete product. Native agents decide what context to read, how often to test, when to backtrack and whether to stop after a plausible-looking patch. SWE-Marathon v1.1 measures those pairings, although it also includes third-party combinations and should not be mistaken for a perfectly controlled API test.
| Model + agent product | Repository resolved rate | Interpretation |
|---|---|---|
| Claude Opus 5 + Claude Code | 50.0% | Highest current point score in the native-product set |
| Claude Fable 5.1 max + Claude Code | 45.6% | 73 successes across 160 trials; first independent native evidence |
| Claude Fable 5 + Claude Code | 45.0% | Legacy Fable; some runs used fallback behavior |
| GPT-6 Astra max + Codex | 42.5% | Tied with Sol in this native pairing despite leading the controlled point estimate |
| GPT-5.6 Sol + Codex | 42.5% | Strong integrated result; below its controlled-model standing |
| GPT-5.6 Terra + Codex | 32.5% | Value product tier, not maximum-capability winner |
| Grok 4.6 + Grok Build | 31.9% | Fast but less reliable on this long-horizon set |
| Gemini 3.7 Flash + OpenCode | 22.5% | Not an Antigravity result; agent pairing matters |
| DeepSeek V4-Pro + mini-swe-agent | 10.6% | Not a native DeepSeek coding product |
SWE-Marathon uses 20 task clusters with eight correlated trials each. It does not publish the same configuration-level uncertainty treatment as DeepSWE, so small point gaps should not be sold as decisive. More importantly, these are product pairings. Gemini 3.7 Flash in OpenCode does not tell us how Gemini 3.8 Flash in Antigravity would perform. Kimi K3 appears on the broader board with Claude Code, which is not a Kimi Code result. The current Qwen3.8-Max snapshot, Gemini 3.8 Flash and Muse Spark 1.2 are not represented.
The product lesson is simple: keep two scorecards. Use the controlled track to choose an intelligence/cost tier; use the native track to decide which product workflow you can trust. Do not combine the percentages into one “overall” winner.
Reliability and human-intervention matrix
| Model tier | Self-testing and context retention | Likely intervention load | API / harness risk | Confidence |
|---|---|---|---|---|
| Opus 5 | Best demonstrated long-horizon ceiling; large trajectories | Lowest unresolved tail, but expensive review loops | Mature Claude Code integration | High |
| GPT-6 Astra | Highest controlled point estimate; strong long-context trajectory | Low-to-moderate, but native result ties Sol rather than leading | New release; Codex integration is already represented | Medium-high |
| Gemini 3.8 Flash | Near-top controlled result with the shortest leading-row median | Potentially low; native Antigravity evidence is still missing | New release and product pairing need observation | Medium-high |
| GPT-5.6 Sol | Strong verification with shorter trajectories than Opus max | Low-to-moderate; good default for hard work | Mature Codex integration | High |
| GPT-5.6 Terra | Good retention at lower spend | Moderate on complex migrations and hidden-test work | Mature Codex integration | High |
| Fable 5.1 | Strong native result; controlled-harness retention remains unknown | Moderate based on a 45.6% native resolved rate | New release; benchmark and routing effects need observation | Medium |
| Grok 4.6 | Fast and capable, but lower controlled resolved rate | Moderate; inspect incomplete verification carefully | Product pairing changes the result materially | Medium |
| Kimi K3 / Qwen3.8-Max | Long trajectories in the public harness | Moderate-to-high review and latency burden | Regional API, quota and harness differences | Medium |
| DeepSeek V4-Pro / Flash | Excellent cost efficiency; more requests and slower paths | High on failures unless escalation is automated | Cache, rate limit and provider stability are central | Medium-high |
| Muse Spark 1.2 | Fast runs but lower independent resolved rate | High for difficult repository tasks | Preview product and pricing/data-use choices | Medium |
No public board here adequately measures parallel-agent speedup. Spawning more agents can reduce wall time when the work decomposes cleanly, but it also duplicates context, raises spend and creates coordination failures when branches overlap. A credible parallel result must report the serial baseline, total tokens across agents, conflicts, discarded work and final reviewer time. Until then, “multi-agent” is a harness feature, not a free multiplier.
Mythos 5.1: separate safeguarded programs, not a second general-coding tier
Anthropic says Fable 5.1 and Mythos 5.1 share the same underlying model. Its current program pages describe Mythos 5.1 access for qualifying cybersecurity teams through the Cyber Verification Program and for verified life-science professionals through the Life Sciences Verification Program. The LSVP uses safeguards more permissive for biology-related work while retaining other safeguards, including cyber classifiers. These program-specific settings do not make Mythos a second general-coding intelligence tier. Anthropic’s Life Sciences Verification Program explains the biology safeguards; its Cyber Verification Program describes verified cybersecurity access.
For a task within an approved cybersecurity or life-sciences program, safeguard behavior is part of task completion. A valid cybersecurity test would use isolated vulnerable applications, explicit scope, no public targets, controlled egress, fixed exploit-validation rules and patch verification after remediation. Report refusal or rerouting separately from technical failure. Anthropic’s 60.9% Terminal-Bench 4.0 Mythos result is vendor-reported and does not establish performance on Kingy’s proposed sandbox suite.
Best coding model by developer profile
| Profile | Recommended default | Escalation path | Reason |
|---|---|---|---|
| Solo developer with a fixed API budget | DeepSeek V4-Pro | Sol for the unresolved tail | Extreme compute value without dropping as far as Flash |
| Startup shipping daily | Gemini 3.8 Flash | Sol or Opus 5 for product-integrated escalation | Near-top controlled success, low spend and fastest leading-row median |
| Large codebase / high consequence | GPT-5.6 Sol or Opus 5 + Claude Code | GPT-6 Astra for a second maximum-capability attempt | Strong native integrations plus a higher-point controlled escalation option |
| One hardest possible repository task | GPT-6 Astra max | Opus 5 + Claude Code and independent human review | Highest controlled point estimate; Opus leads the native table |
| Latency-sensitive pair programming | Gemini 3.8 Flash | Sol when native verification stalls | 10m 05s median with a 73.8% controlled resolved rate |
| Self-hosting or model customization | DeepSeek V4 or Kimi K3 weights | Hosted frontier API for final verification | Open-weight control, with infrastructure trade-offs |
| Team evaluating Fable 5.1 | Pilot in Claude Code on representative repos | Keep a controlled-harness incumbent for comparison | Credible 45.6% native result, but no equivalent-tools score |
| Verified cybersecurity or life-sciences team | Fable 5.1 for ordinary engineering | Mythos 5.1 only inside the applicable approved program | Same base model; safeguard regime is the differentiator |
Model versions and September 8 price snapshot
The comparison brief began with Meta Muse Spark 1.1. Meta announced Muse Spark 1.3 on September 2, 2026; the independent controlled ranking here uses the tested Spark 1.2 build, not Spark 1.3. Spark 1.1 remains historical context. GPT-6 Astra and Gemini 3.8 Flash are serious contenders and have been added. Qwen3.8-Max also moved to the 2026-09-02 snapshot after the benchmark row was generated, so its existing score should be treated as evidence for the earlier tested build rather than the refreshed alias. The price table below preserves the September 8, 2026 snapshot, not current quotes. Meta’s September 2 Muse Spark 1.3 announcement identifies the newer release.
| Model in September 8 snapshot | List input / output per 1M tokens | Context note |
|---|---|---|
| Claude Fable 5.1 | $10 / $50; $0.25 cache reads | Long-agent cache pricing is the key economic change |
| Claude Opus 5 | $5 / $25 | 1M-token context |
| GPT-6 Astra | $10 / $50; $1 cache reads | 1.05M context; higher long-context rates above 272k input tokens |
| GPT-5.6 Sol | $4 / $20 promotional | 1.05M context; promotion is time-limited |
| GPT-5.6 Terra | $2 / $12 | 1.05M context |
| Gemini 3.8 Flash | $0.75 / $3.75 promotional | 1M context; introductory price scheduled to rise after 2026 |
| Grok 4.6 | $2 / $6 | 500k context; $0.50 cached input |
| DeepSeek V4-Pro / Flash | $0.66/$1.98 and $0.22/$0.66 off-peak | Time-of-day pricing and cache rates matter |
| Qwen3.8-Max-0902 | CNY12 / CNY36 global list | Alias qwen3.8-max-2026-09-02; regional pricing differs; 1M context |
| Kimi K3 | $3 uncached input / $15 output | $0.30 cached input; 1M context |
| Meta Muse Spark 1.2 | Preview pricing varies by access path | Verify the Meta Model API quote and data-use terms for your account |
Reproducible test-manifest appendix
The evidence in this article is reproducible at the snapshot level. Kingy downloaded DeepSWE’s public live-leaderboard JSON generated at 2026-09-03T22:24:37.984682+00:00. Its SHA-256 checksum is 005cbedb49f988ba3f0d9636300862ad7ace93ce1992b37faf9945fe5b383415. We also extracted SWE-Marathon’s embedded v1.1 task dataset on September 8; its checksum is d0df5a489c28966694c6f33eee7c16a55674b2490513c4ba9c7abf0e659318c4. These files preserve configuration-level scores, attempts, cost, duration and task outcomes used in this update. The original August 26 DeepSWE snapshot remains archived with checksum fa747b5d67bd146dfc9685568f28c1211580563ce960a11ae7232a0264f59a7b.
| Manifest field | Controlled public evidence used here | Next Kingy seven-task suite |
|---|---|---|
| Suite ID | DeepSWE v1.1 / snapshot 2026-09-03; SWE-Marathon v1.1 / retrieved 2026-09-08 | KNG-FCA-1.0 (protocol; not yet run) |
| Repository pins | 113 benchmark tasks across 91 repositories, frozen by the benchmark environments | Exact Git commit and container digest required before pilot |
| Task classes | Long-horizon issue resolution across five languages | Diagnosis; hidden-test feature; migration; behavior-preserving refactor; screenshot frontend; measured performance; sandboxed vulnerability patch |
| Attempts | Most configurations: four whole-suite passes | Three attempts per model/task; label any single-run cell |
| Equal-time scenario | Compare resolved rate at observed median duration | 30 minutes per attempt, same CPU/RAM/network policy |
| Equal-dollar scenario | Compare resolved rate at observed model spend | $5 model-spend cap per attempt, cache charged |
| Maximum-capability scenario | Best published effort per model | Highest supported effort, 120-minute ceiling, uncapped model spend reported |
| Tools | mini-swe-agent common harness | Equivalent shell, patch, search and test tools; no model-specific hidden helper |
| Acceptance | Benchmark verifier; timeouts/context failures count | Visible tests + hidden tests + regression/security review + task-specific performance target |
| Logging | Passes, attempts, CI, cost, token/cache, time, steps and context | Add tool calls, retries, first-pass acceptance, reviewer findings, intervention minutes and API failures |
| Parallel agents | Not counted as a separate result here | Serial baseline plus total multi-agent tokens, conflicts, discarded work and speedup |
The proposed KNG-FCA-1.0 row is a protocol, not a completed benchmark. No model receives credit for it in this article. Before any future result is publishable, every repository needs an exact commit, a task-spec checksum, a container digest, hidden-test hash, network policy and reviewer rubric. That is the standard required to turn the seven requested scenarios into auditable evidence rather than benchmark theatre.
Final recommendation
For controlled API work, Gemini 3.8 Flash is the best default in this week’s evidence: its 73.8% resolved rate is effectively tied with the leaders while its recorded spend and median runtime are much lower. GPT-6 Astra is the maximum-capability point leader at 74.1%. For complete native products, Opus 5 with Claude Code retains the highest demonstrated score; Sol and Terra remain mature Codex options. DeepSeek V4-Pro is the economic specialist for high-volume, reviewable work.
Fable 5.1’s 45.6% SWE-Marathon result makes it a credible native contender, just 4.4 points behind Opus 5 in the same product family. The decisive controlled evidence is still missing: identical repository tasks, equivalent tools, repeated attempts, hidden tests, total wall time and human intervention. Until that row exists, the most reliable answer is a routed portfolio, not a logo.
FAQ
Is Claude Fable 5.1 the best AI coding model in 2026?
Not overall. Fable 5.1 now has a credible independent native-agent result of 45.6% with Claude Code, but it has no DeepSWE v1.1 row under the common model harness. GPT-6 Astra leads that controlled point estimate, Gemini 3.8 Flash offers the strongest near-frontier economics, and Opus 5 with Claude Code leads the native table.
Which model has the highest repository resolved rate?
GPT-6 Astra xhigh has the highest current DeepSWE v1.1 point score at 74.1%. Gemini 3.8 Flash high is close at 73.8%, followed by Opus 5 at 73.6% and Sol at 72.7%; their published uncertainty intervals overlap.
Which coding agent is cheapest?
On benchmark compute alone, DeepSeek V4-Flash and V4-Pro are dramatically cheaper per resolved attempt. Total engineering cost can be higher if slower trajectories, retries or review consume more developer time.
Is Claude Mythos 5.1 better than Fable 5.1 for coding?
Anthropic describes the same underlying model with different safeguards. Mythos should be evaluated only within an applicable verified cybersecurity or life-sciences access program; it is not a separate general-coding tier.
Why not combine model and native-agent scores?
Because the agent product controls context selection, tool use, retries and verification. A common harness isolates more of the model effect; a native-product test measures the complete workflow. Both matter, but they answer different questions.
What should a team test before switching?
Use representative repositories and measure first-pass acceptance, hidden tests, regressions, reviewer findings, intervention minutes, wall time, spend, retries and provider failures. Three attempts per task are preferable because a single agent run is noisy.
Official sources and methodology
- Anthropic: Claude Fable 5.1 and Mythos 5.1
- Anthropic: Claude Opus 5 and Claude API pricing
- OpenAI: GPT-5.6 Sol and Terra
- OpenAI: GPT-6 Astra and API model documentation
- Google: Gemini 3.8 Flash and Gemini API model documentation
- xAI: Grok 4.6 model documentation
- Meta: Muse Spark and Muse Code
- DeepSeek model updates and API pricing
- Alibaba Cloud: Qwen3.8-Max
- Moonshot AI: Kimi API and pricing
- DeepSWE v1.1 controlled-model leaderboard
- SWE-Marathon v1.1 native-agent leaderboard
- Kingy: DeepSeek V4-Flash vs Codex on 20 coding tasks
- Kingy: Grok Build vs Codex vs Claude Code
- Kingy: Muse Code and Muse Spark 1.2 evidence audit
The Kingy Brief
Get The Kingy Brief.
AI changes, original tests and one practical thing to try. Fridays at 09:00 Vancouver time.
Free · Double opt-in · Unsubscribe anytime
Sign up for The Kingy Brief on Beehiiv.
Signup help and newsletter schedule
Signup form provided by Beehiiv. After submitting, check your inbox for "Confirm your subscription to The Kingy Brief" and open its confirmation link. Check Spam or Promotions if you cannot find it.
Fridays at 09:00 Vancouver time: source-checked AI changes, original tests and one practical thing to try. We skip a week when there is not enough verified material. Free. Unsubscribe anytime.