Summary: Goodfire researcher Nick Cammarata argues that neural networks may be more directly understandable than researchers assumed. His essay challenges how apparent internal disorder has been interpreted. The findings are preliminary, and complete model understanding remains unproven. Their significance depends on whether explanations survive independent tests and lead to reliable improvements. Read the original essay.
When an AI model invents a reference, agrees with a mistaken assumption, or produces an answer it cannot justify, the failure is visible. Explaining what caused that failure inside the model is considerably harder.
That gap helps explain why artificial intelligence is so often described as a black box. We can inspect the question and read the answer, yet the computations connecting them resist a straightforward explanation.
The phrase can also encourage a misleading impression: that AI’s internal workings are permanently beyond investigation. Researchers have already identified meaningful internal structures and experimentally changed model behavior. The unresolved questions concern how much those discoveries explain, how reliably the methods work, and how far they can scale.
Our coverage of research into Claude’s internal workspace examines another approach to investigating computations behind a model’s answers.
Cammarata’s argument deserves attention because it challenges an assumption about the difficulty of that work. To understand its significance, we need to distinguish access to a model, an explanation of its components, and dependable control over its behavior.
Knowing the mathematics is different from understanding a decision
A language model’s developers know the architecture they built and the training process they used. With sufficient access, researchers can inspect its parameters and record the numerical activity generated as it processes text.
Those facts still leave a difficult explanatory task.
Consider an ordinary question about a fictional character. A useful account of the answer would identify how the model recognizes the name, retrieves relevant associations, handles ambiguity, and selects a response. A list of numerical operations contains that computation, but turning the list into an explanation requires discovering which relationships matter.
OpenAI described this distinction in its 2024 research on extracting concepts from GPT-4: researchers design the algorithms that train neural networks, while the resulting internal organization remains difficult to decompose into identifiable, understandable parts. OpenAI’s research explanation.
Mechanistic interpretability attempts to close that gap by investigating the components and computations responsible for behavior. The ambition is an explanation that makes testable predictions about what the model will do when particular internal mechanisms change.
A hypothetical example makes the standard clearer. Suppose a researcher identifies a component that activates whenever a model discusses uncertainty. Calling it an “uncertainty detector” is a useful starting point. A stronger explanation would predict when it activates on unfamiliar examples, identify how other components influence it, and show what happens when its activity is altered.
Each step supplies evidence that a label corresponds to something the model uses.
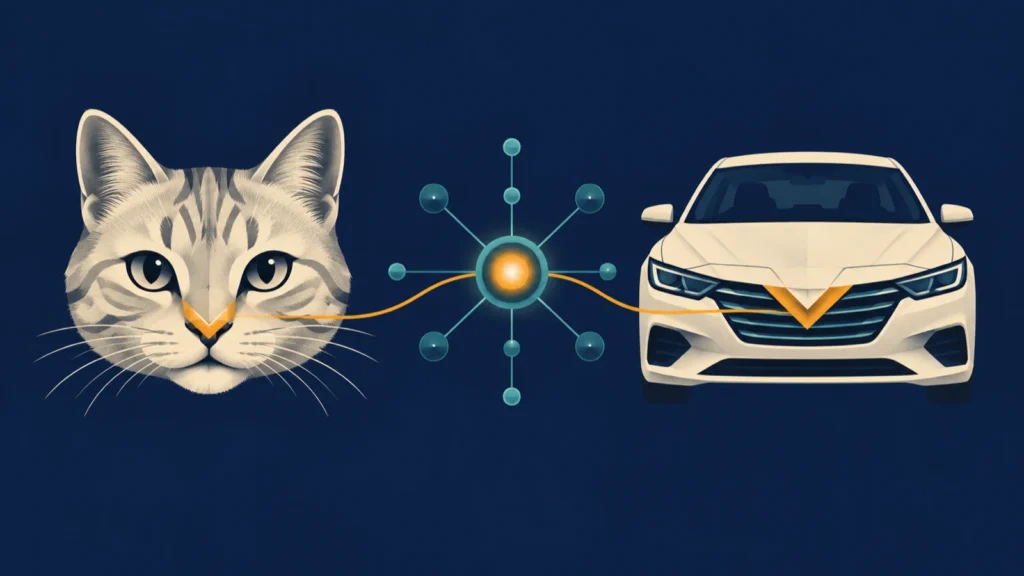
Cammarata’s essay, Neural Networks Are Already Clean, offers a concrete reassessment: a famous image-model neuron associated with cats and cars may respond to shared V-shaped geometry. He proposes recursive generalization, in which related functions develop branches, illustrated by a progression from “iy” to “diy” to “do it yourself.” Cammarata’s argument and examples.
The distinction matters because the categories people recognize are only one possible way to organize information. A visual system could find a geometric similarity useful even when it crosses familiar object categories. A language system could exploit a relationship that connects spelling, meaning, and context.
An explanation built around human labels can therefore miss a simpler relationship. But a simpler explanation also needs testing: a convincing story about shared geometry should predict responses to new shapes, including examples deliberately chosen to separate it from competing accounts.
That is the productive scientific question raised by an example like this. Which explanation predicts more of the model’s behavior, and where does it fail?
Why researchers became concerned about superposition
Two terms help explain the broader disagreement.
A polysemantic neuron appears to respond to multiple meanings or patterns. Superposition is a proposed explanation for how networks can represent more features than their available dimensions might initially seem to permit, using overlapping representations.
Composition offers another way to combine information. Separate properties can work together to represent many combinations without requiring a dedicated component for each complete object.
In a 2023 explanatory note, Chris Olah illustrated the distinction through colored shapes. A system can combine properties such as color and shape, or encode information using overlapping representations with different benefits and costs. The note explicitly allows mixtures of composition and superposition. Olah’s explanation of composition and superposition.
For an intuitive example, imagine describing a room using reusable properties: blue, circular, wooden, tall. Those properties can describe many objects through different combinations. That is a useful analogy for composition.
Overlapping representations introduce a different interpretive challenge. Looking at one component may reveal an incomplete or confusing mixture; recovering a meaningful representation may require examining a combination of components.
These possibilities matter because they affect where researchers should look for explanations. Individual neurons might sometimes offer useful units of investigation. In other cases, a pattern spanning several components could be more informative.
The existence of several responses in one neuron does not, by itself, settle which account explains them. Researchers must investigate the relationships between those responses and how downstream computations use them.
That leaves room for substantial disagreement without reducing the field to opposing camps that believe either in perfect order or total chaos. The practical issue is which representations explain real computations faithfully enough to support useful predictions.
What the preliminary 90% estimate measures
Cammarata reports preliminary Qwen3-32B audits estimating that roughly 90% of neuron poles have one main role, about 7% have two related roles, and 2–4% remain unexplained. These classifications depend on thresholds and what counts as a distinct function. The essay describes a forthcoming technical companion paper and says full audits at trillion-parameter scale have not begun. Source and qualifications.
Those qualifications determine how the number should be interpreted.
A count of components assigned a main role is different from a measurement of how much behavior has been explained. Components can differ in their importance, interact in unexpected ways, or become relevant only under particular conditions.
There is also a distinction between explaining common behavior and accounting for rare failures. A mechanism could be straightforward on the examples used to study it while behaving differently under unusual inputs. Conversely, a complicated component could make only a small contribution to an outcome.
For that reason, the most useful follow-up would connect component-level explanations to predictions about complete responses. An audit becomes more informative when readers can see its sampling procedure, classification rules, disagreements, counterexamples, and results on examples held back during investigation.
The percentage is an invitation to examine the method. Treating it as a fraction of “AI understood” would discard the details needed to evaluate it.
Why researchers train models to interpret other models
One influential interpretability method uses a sparse autoencoder, often abbreviated SAE.
An SAE learns a representation of a model’s internal activity using a larger set of features, with relatively few active at once. Researchers then examine whether those features correspond to understandable patterns. Its training objective includes reconstructing the original activity while encouraging sparsity.
Goodfire’s practical guide describes SAEs as useful exploratory tools: they can suggest concepts and relationships for researchers to investigate further. It also distinguishes this exploratory task from detecting a specific, already defined behavior, where a purpose-built classifier may be more appropriate. Goodfire’s guide to sparse autoencoders.
The appeal is clear. If a representation is difficult to understand directly, a learned decomposition might expose useful structure.
Anthropic demonstrated this approach in 2024 by extracting millions of features from a middle layer of Claude 3 Sonnet. One feature responded to the Golden Gate Bridge across different contexts and languages. Artificially increasing its activity caused the model to bring the bridge into answers where it was irrelevant. Anthropic’s feature-mapping research.
That intervention supplied stronger evidence than a descriptive label alone. Altering the feature changed behavior in a related direction.
However, a decomposition introduces its own research questions. How faithfully does it preserve the original computation? Which information does it omit? Does an understandable feature capture a mechanism, a correlation, or a mixture of both?
OpenAI’s 2024 work explicitly identified incomplete reconstruction and difficulties validating interpretations among the limitations of its SAE approach. It also emphasized that finding features at one location leaves further work to explain how the model computes and uses them. OpenAI’s stated limitations.
These are reasons to compare methods against the task being studied. Direct component analysis, learned features, and targeted detectors can provide different kinds of evidence. A method earns its place by answering a question more accurately or efficiently than the alternatives.
What would count as understanding an AI?
Public discussion often compresses several achievements into the word “understanding.” Separating them makes breakthrough claims easier to assess.
| Achievement | Evidence it would provide | Question still to answer |
|---|---|---|
| Describe a component | Its activity has an apparent pattern | Does the description predict unfamiliar cases? |
| Predict its activity | The explanation generalizes beyond observed examples | What role does it play in producing behavior? |
| Trace a causal contribution | Interventions change an outcome as predicted | How complete is the explanation? |
| Improve behavior reliably | A targeted change works across varied tests | What failures or side effects remain? |
This is an editorial framework for evaluating claims, rather than a standardized score.
Its purpose is to prevent a familiar jump: moving from an attractive explanation of one component to confidence in an entire system.
A researcher might correctly identify a feature associated with agreement. That discovery could help explain a specific response. Establishing that it causes inappropriate agreement would require further experiments. Using it to reduce sycophancy reliably would require broader testing, including cases where agreement is appropriate.
The steps are connected, but each requires evidence.
Earlier interpretability research has already grappled with this problem. In Interpretability in the Wild, researchers investigated how GPT-2 small performed an indirect-object identification task. Their proposed explanation involved 26 attention heads grouped into seven classes, and they evaluated it using faithfulness, completeness, and minimality criteria. The evaluation also exposed gaps in their account. The original study.
That is a useful model for progress: an explanation can illuminate a mechanism while remaining incomplete, and a good evaluation should help reveal the missing pieces.
Causal experiments also need careful design
Researchers often test explanations by removing, replacing, or otherwise changing internal activity and measuring the consequences.
These interventions can be powerful. They can also be sensitive to experimental choices.
Fred Zhang and Neel Nanda examined activation patching, a technique for identifying important model components by transferring internal activity between runs. Their study found that choices including evaluation metrics and how inputs were altered could lead to different interpretability results. Their activation-patching research.
The implication is practical. A diagram becomes more persuasive when its proposed relationships survive several reasonable ways of testing them.
For a hypothetical uncertainty mechanism, researchers could vary wording, subject matter, the amount of available evidence, and whether the correct response is confidence or hesitation. They could compare targeted interventions with changes to unrelated components. They could test whether an apparent improvement comes from better judgment or from a general tendency to avoid answering.
These checks distinguish a mechanism that supports accurate uncertainty from one that merely makes the model sound cautious.
They also show why independent replication matters. Another team may use different examples, notice a missing control, or find a case that separates two explanations previously thought equivalent.
A successful replication would strengthen confidence in the proposed mechanism. A failure could reveal a boundary condition or a problem in the interpretation. Either result would make the claim more useful.
An AI’s explanation of itself is another piece of evidence
A chatbot can produce an articulate account of how it reached an answer. That account can be helpful to a reader, but its accuracy requires investigation.
For background on the relationship between written reasoning and internal computation, see our analysis of how chain-of-thought reasoning works.
Anthropic tested this issue by giving reasoning models hints during evaluation and examining whether their written reasoning acknowledged using them. The models often omitted the hints despite relying on them. The researchers also emphasized limitations, including artificial scenarios, multiple-choice tasks, and a restricted set of models and hint types. Anthropic’s research on reasoning faithfulness.
The finding supports a specific caution: a persuasive written explanation does not establish that every influential factor has been disclosed.
Internal investigation offers a different route to evidence. It allows researchers to compare what a model says happened with activity observed during the computation.
That comparison is valuable even when both accounts are incomplete. Agreement between them can support an explanation; disagreement can identify a question worth investigating. Neither a fluent narrative nor a complicated activation diagram should receive automatic authority.
For users, this distinction helps explain why asking an AI to justify an answer cannot replace checking the answer itself. For researchers, it motivates experiments that connect explanations to measurable internal processes.
What interpretability could contribute to hallucination research
Our explanation of why language models hallucinate examines another part of this problem: how training and evaluation can encourage incorrect answers.
Anthropic’s 2025 circuit-tracing work provides a concrete example of that connection.
In its studies of Claude 3.5 Haiku, researchers identified mechanisms involved in whether the model answered a question or declined because it lacked information. They showed that intervening on relevant features could induce a fabricated answer about an unfamiliar person.
The same research also traced planning in poetry: changing internal representations associated with a planned rhyme changed how the model completed a line. Anthropic cautioned that its method captured only a fraction of the computation, even on short prompts. The circuit-tracing findings and limitations.
These examples demonstrate the value of asking mechanistic questions about visible behavior. They also define a boundary between diagnosing a failure and developing a dependable remedy.
A system that refuses more questions could produce fewer false statements while becoming less useful. A successful intervention would need to improve the decision about when to answer, preserve knowledge the model already uses correctly, and hold up across different formulations and subjects.
That makes outcome testing essential even when an internal explanation looks convincing.
For an AI research assistant, a useful evaluation might examine whether a proposed change reduces invented references without increasing missed valid references. For a coding assistant, it could examine whether uncertainty signals distinguish unsupported guesses from correct but unfamiliar solutions.
Those are proposed tests, not demonstrated consequences of Cammarata’s essay. They illustrate the kind of practical evidence that would connect improved interpretability to better products.
Understanding and control can also come apart
Goodfire’s earlier work on DeepSeek R1 illustrates another complication.
The company reported that steering some features in the reasoning model behaved unexpectedly. In certain experiments, stronger interventions caused the model to revert toward its original behavior before eventually becoming incoherent at still higher strengths. The researchers described these as early observations requiring further investigation. Goodfire’s DeepSeek R1 research.
That result should discourage overly simple accounts of model control. Identifying something relevant does not guarantee that turning it up or down produces a smooth, predictable change.
A proposed intervention may affect several processes. Other pathways may compensate. Its effect may depend on when it is applied or what the model has already computed.
From an engineering perspective, this creates a demanding standard. A change should work under the conditions where it is intended to operate, and its side effects should be measured under conditions where it could cause harm or reduce usefulness.
Interpretability can help formulate those tests. It cannot remove the need to run them.
Can AI help investigate AI?
The scale of neural networks makes automation attractive. A productive research process must examine large numbers of examples, generate hypotheses, identify counterexamples, and keep track of the resulting evidence.
OpenAI explored part of this approach in 2023 by using GPT-4 to generate and score explanations of GPT-2 neurons. The researchers found that iteration and counterexamples could improve explanation scores. They also stated that their method described correlations with input text without establishing the mechanisms producing the behavior or its downstream effects. OpenAI’s automated neuron-explanation research.
A sensible automated workflow would build on that distinction. One system could propose an explanation, another could generate challenging examples, and experimental tools could measure what the model actually does.
The measurements need to constrain the narrative. Several AI systems agreeing on a label would offer limited reassurance if they share the same mistaken assumption. A useful process must make it easy for the data to disprove the explanation.
Automation should therefore be judged partly by its ability to expose errors: finding cases where a label breaks, identifying inconsistent results, and preserving enough detail for another researcher to reproduce the experiment.
Producing more interpretations is useful only when their quality can be assessed.
The next evidence should make narrower claims easier to trust
My assessment is that the strongest response to this research is a program of specific comparisons.
First, researchers should compare methods on the same models, behaviors, and held-back examples. Otherwise, differences in model architecture or task selection can become confused with differences in explanatory power.
Second, component audits should report how examples were selected and how ambiguous cases were handled. A category such as “one main function” becomes much more informative when outsiders can inspect borderline cases and reproduce the classification.
Third, explanations should predict interventions before the results are known. A successful prediction provides a stronger test than an account constructed after inspecting the outcome.
Finally, a practical claim should demonstrate a practical benefit. If an interpretation is intended to help detect unreliable answers, it should be evaluated on unreliable answers, including cases the researchers did not use to develop the method.
These standards leave room for useful progress without requiring a complete explanation of every computation. A method could earn trust for diagnosing one failure, monitoring one behavior, or answering one scientific question while its broader ambitions remain unresolved.
For readers evaluating the next claim that AI’s black box has been opened, the most useful evidence will be a clear prediction, a reproducible intervention, and a measured result on unfamiliar cases.
This article is based on the linked primary sources. No independent replication or researcher interviews were conducted. The featured artwork is an AI-generated conceptual illustration, not a measured activation map.
The Kingy Brief
Get The Kingy Brief.
AI changes, original tests and one practical thing to try. Fridays at 09:00 Vancouver time.
Free · Double opt-in · Unsubscribe anytime
Sign up for The Kingy Brief on Beehiiv.
Signup help and newsletter schedule
Signup form provided by Beehiiv. After submitting, check your inbox for "Confirm your subscription to The Kingy Brief" and open its confirmation link. Check Spam or Promotions if you cannot find it.
Fridays at 09:00 Vancouver time: source-checked AI changes, original tests and one practical thing to try. We skip a week when there is not enough verified material. Free. Unsubscribe anytime.