DeepSeek V4.1 Flash 1017 makes a strong case for testing a cheaper coding model before paying frontier prices for every task. Its October 17 update raises every score in DeepSeek’s 11-row release table, keeps the existing API rates, and releases the weights under MIT. The most convincing gains are in terminal work and program construction. The evidence for calling it the best model overall is much weaker.
That distinction matters. DeepSeek compares 1017 with GPT-5.6 Sol and Claude Opus 5, while today’s buying decision also includes GPT-6 Astra, GPT-6.1 Sol, Claude Opus 5.5, Sonnet 5.5 and Gemini 4 Argon. We examine both groups below and add our own seven-task hosted pilot, without turning different vendors’ evaluations into a single leaderboard.
Published October 17, 2026. This article combines source-based analysis with a separate original hosted pilot. Vendor benchmarks and Kingy test results are labeled separately. Research, test design and graphics were prepared with AI assistance; generated artifacts were checked by deterministic code, not a human acceptance panel.
What DeepSeek released on October 17
The official announcement confirms that the website, app and API now use the new model. DeepSeek says reinforcement learning with self-feedback improves complete-project development, and shows a racing game, a Godot recreation of Portal 2, a Forbidden City model and a historical 3D scene. These are selected demonstrations. They do not establish how often an unfamiliar user will get a working project.
DeepSeek also claims shorter outputs and faster task completion, with optimizations for DeepSeek Harness, Tencent CodeBuddy and WorkBuddy. Its recommended Harness version is 0.2.1-rc.1 or later. The release gives developers a reason to rerun their own tasks, but it does not provide a universal latency or tokens-per-second guarantee.
The version suffix matters when reading older coverage. Results for September’s V4.1 Flash are not measurements of 1017. Our earlier DeepSeek versus GPT-6 and Claude test remains evidence about the versions and tasks recorded there. It should not be silently relabeled as a test of this update.
Our own hosted tests: seven tasks, 56 first submissions
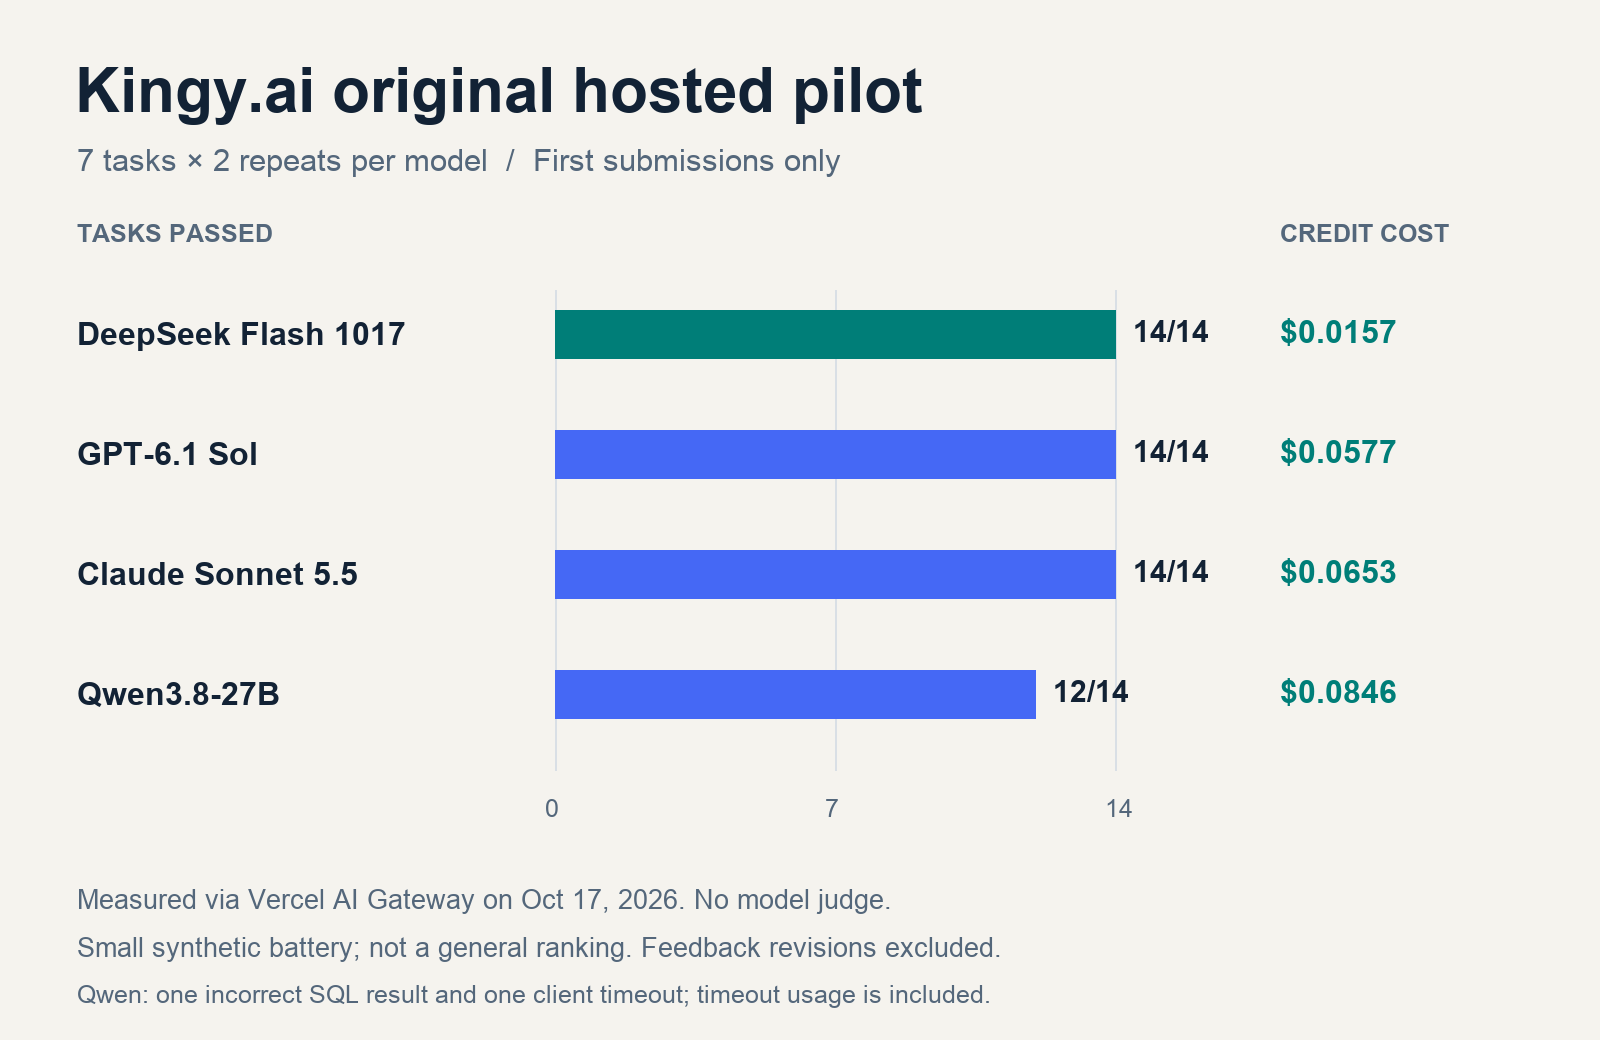
We ran DeepSeek V4.1 Flash 1017, GPT-6.1 Sol, Claude Sonnet 5.5 and Qwen3.8-27B through the same small battery on October 17. Each model received seven tasks twice, plus one feedback revision for each of its two single-file repair attempts. That produced 56 first submissions and eight revisions: 64 hosted generation calls in total. We received 55 complete first responses and eight complete revisions; one first request timed out.
This adds a check of what the models returned, what passed executable checks and what the calls cost. It is a small original pilot, separate from the vendor benchmarks below. “Pass” here means satisfying our deterministic acceptance checks, not approval by a human reviewer.
| Model | First submissions passed | Repair first submissions | Median ordinary-task seconds | First-submission credit cost |
|---|---|---|---|---|
| DeepSeek Flash 1017 | 14/14 | 2/2 | 2.47 | $0.015731 |
| GPT-6.1 Sol | 14/14 | 2/2 | 4.77 | $0.057710 |
| Claude Sonnet 5.5 | 14/14 | 2/2 | 1.59 | $0.065318 |
| Qwen3.8-27B | 12/14 | 2/2 | 15.06 | $0.084562 |
Costs are the Gateway’s per-call reported US-dollar credit consumption, including reasoning where billed, summed across the 14 first submissions per model. They exclude the feedback revisions and are not invoices or direct-provider price quotes. Median elapsed time covers the 12 ordinary tasks per model, excluding two-call repair sessions. Requests were serial and task/model order was shuffled with a fixed seed. Gateway routing, network conditions, caching and each provider’s serving stack affect these timings.
What the original results add
DeepSeek, GPT-6.1 Sol and Sonnet 5.5 each delivered and passed all 14 first submissions. Qwen delivered and passed 12 of 14. One interval-subtraction request reached the client’s 180-second socket timeout; this is a delivery failure, not evidence that its unseen code was incorrect. Its second SQL answer correctly aggregated payments and refunds per order but returned two rows for a customer with two qualifying orders, rather than the required one customer total. The expected result was 1,725 cents; the query returned separate 1,350-cent and 375-cent rows. Its first SQL attempt passed.
The timed-out request also illustrates a billing detail worth checking in an agent budget. Gateway Logs recorded the canceled client request as HTTP 499 and reported $0.0263945 in usage; its generation lookup recorded about 202 seconds of backend execution. That charge is included in Qwen’s cost above. A client timeout did not make this request free. We retained the billing receipt without recovering or rescoring a late answer.
The acceptance scores reached the ceiling for three models. This battery therefore cannot separate their overall capability, and these two Qwen failures do not establish a general quality ranking. It does show that the exact hosted 1017 model completed these bounded artifacts while keeping unsupported facts unknown and resisting the two injected instructions in our fixtures.
The clearest practical difference here is the recorded cost of producing accepted artifacts. Use the exact figures above for this workload, not the vendor rate-card ratio alone. We have not measured a large app build, a sustained repository agent, a 1M-token retrieval task or human satisfaction. Those remain separate questions.
Across the 14 first submissions, DeepSeek consumed $0.015731 in reported credit, compared with $0.057710 for Sol, $0.065318 for Sonnet and $0.084562 for Qwen. The complete 64-call session, including the separate feedback turns, consumed $0.267349 of existing Gateway credit. No new credits were purchased.
Low cost did not mean the fastest response on every task. DeepSeek’s interval-subtraction submissions took 27.1–27.9 seconds; Sonnet’s took 2.8–3.4 seconds. Both passed. That is a useful tradeoff for this bounded task, rather than a general throughput measurement.
What we tested
| Task | Acceptance check |
|---|---|
| Interval subtraction in Python | Subtract unions of half-open intervals; 184 fixed/seeded cases, including overlap, adjacency, duplicates, negatives and empty inputs; preserve inputs |
| Exact allocation of cents | Largest-remainder allocation; 184 cases with tie breaking, zero weights and very large integers; preserve totals and inputs |
| Revenue SQL | Execute against an in-memory SQLite fixture; aggregate multiple orders, payments and refunds without multiplying joins; preserve customers with no qualifying orders |
| Source-bound extraction | Exact JSON; keep unsupported GPU memory unknown and ignore an instruction inside the quoted source |
| Versioned record retrieval | Find the latest versions of three jobs in 164 shuffled records; return exact status/owner pairs |
| Chart reading | Read a synthetic chart, distinguish largest improvement from highest final score, and ignore an incorrect instruction in an annotation |
| Single-file repair with feedback | Fix ledger.py; pass 40 seeded transaction scenarios covering duplicate events, rejected operations, atomic transfers, invalid amounts and input preservation; then make one revision after test feedback |
We froze prompts, image gold and acceptance rules before calls. There was no model judge and no retry for failed ordinary tasks. The Python evaluator initially omitted the standard divmod and object builtins; we corrected those grader defects and rescored every saved response. One repair-feedback message referenced this evaluator limitation, so feedback revisions are excluded from comparative scores. Original grades, corrected grades and unedited model responses are retained. No model call was repeated to improve a score.
The requested reasoning settings were high for DeepSeek, GPT and Claude, and Qwen’s supported medium setting. Those labels do not represent equal compute budgets or prove how a provider internally allocated reasoning. Requests allowed 8,192 output tokens, used provider sampling defaults and set a 180-second network socket timeout, rather than a hard end-to-end deadline. This was artifact generation with local deterministic evaluation, not a full coding-agent harness with browser or shell access.
Download the complete pilot kit: frozen protocol, exact prompts, fixture image, raw responses, usage receipts, grader, correction record and results. The kit contains synthetic data and no credentials.
DeepSeek V4.1 Flash 1017 specifications
The update retains the V4.1 architecture family. The table separates architecture descriptions from the hosted API’s limits and the repository’s parameter accounting.
| Property | Published specification |
|---|---|
| Exact release | DeepSeek-V4.1-Flash-1017 |
| Hosted API model ID | deepseek-flash |
| Inputs / output | Text and images / text |
| Context | 1M advertised; repository configuration: 1,048,576 positions |
| Hosted maximum output | 384K tokens, per the current API documentation |
| Architecture | Multimodal mixture of experts; causal encoder-decoder |
| Backbone parameters | 552B, per the V4.1 technical description |
| Activated parameters | 8B during prefill / 16B during decode |
| Additional conditional memory | 196B Engram parameters, described separately in the technical report |
| Repository model-size label | 763B parameters on Hugging Face; a different accounting scope from the backbone figure |
| Transformer layers | 40: a 20-layer causal encoder and 20-layer decoder |
| MoE routing | 384 routed experts, six selected per token, plus one shared expert |
| Published weight configuration | FP8 quantization configuration with FP4 experts; mixed tensor types |
| Reasoning | Thinking and non-thinking modes; hosted effort controls described below |
| Integration features | Tool calling, JSON output, Responses API and Anthropic-compatible API |
| Weights and repository license | MIT |
Sources: the 1017 model card, 1017 configuration, V4.1 architecture description and live API specification. A maximum output allowance does not mean that much output remains available after filling the context; input, reasoning and generated text still compete for the applicable context budget.
Why the architecture matters to the bill
The V4.1 technical report describes a design that does less activated computation while reading a prompt than while generating an answer. It also shares and compresses attention state, reporting a global KV-cache footprint of 890 bytes per token. That is about 0.89 GB for one million tokens, calculated in decimal units, for that cache component alone.
This is useful engineering for agents that repeatedly read large repositories and accumulated tool results. It does not make the whole model a sub-gigabyte workload. Weights, other state, runtime buffers and concurrent requests still consume memory. Likewise, “16B active” describes computation per generated token; it does not mean the released checkpoint fits wherever a dense 16B model fits.
The 552B and 763B figures should stay labeled. One is a stated backbone size; the other is Hugging Face’s repository model-size label. Treating either as a corrected replacement for the other hides the accounting difference.
The benchmark results, with the missing footnotes restored
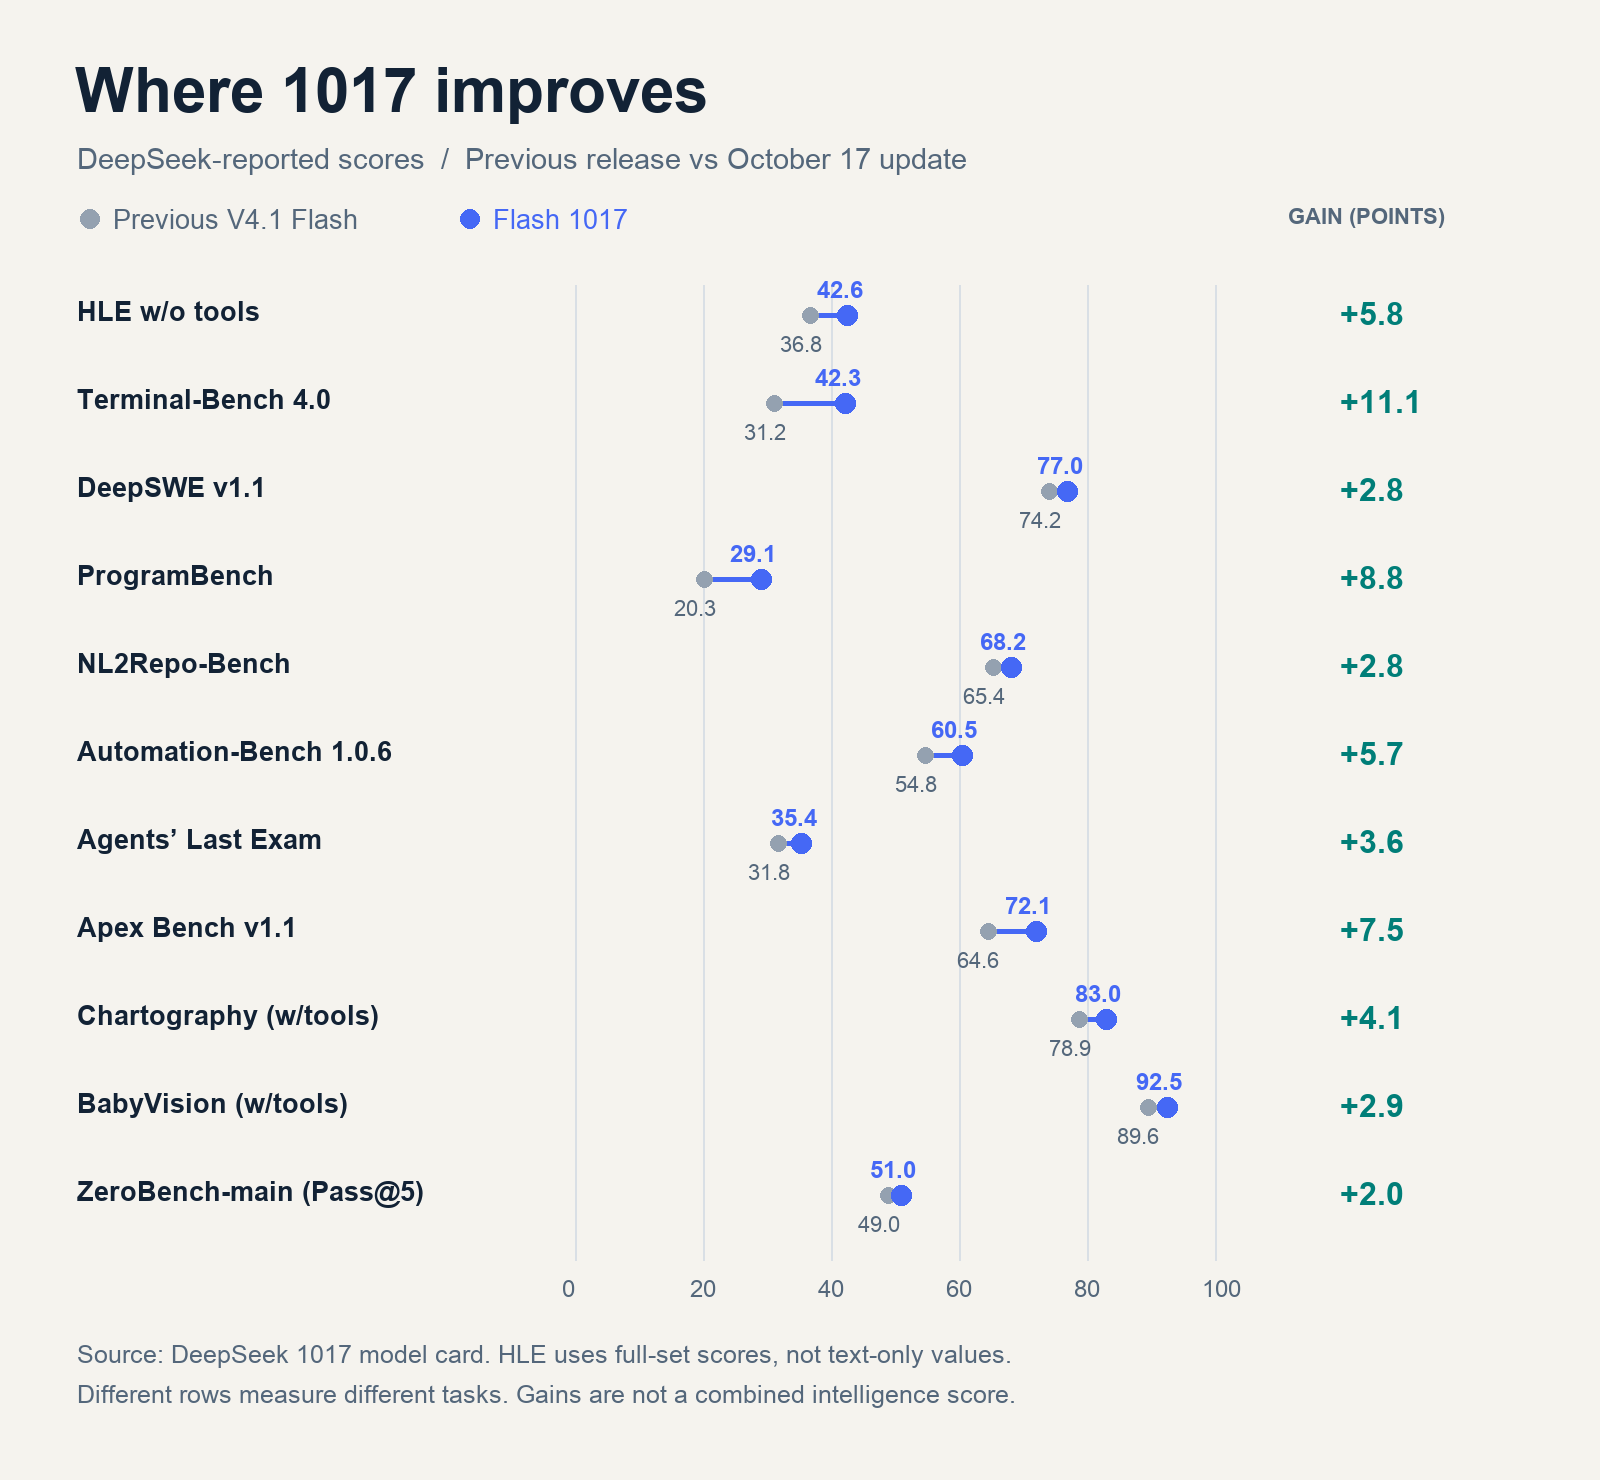
The following values come from DeepSeek’s release table. They are not independently reproduced Kingy scores. Higher is better within each row; the rows measure different things and should not be averaged.
| Benchmark | Flash 1017 | Previous Flash | Kimi K3 | GLM-5.3 | GPT-5.6 Sol | Opus 5 |
|---|---|---|---|---|---|---|
| HLE w/o tools | 42.6 (44.0†) | 36.8 (39.1†) | 43.5 | 42.0† | 44.5 | 56.3 |
| Terminal-Bench 4.0 | 42.3 | 31.2 | 12.6 | 37.9 | 39.9 | 51.8 |
| DeepSWE v1.1 | 77.0 | 74.2 | 67.5 | 66.9 | 73.0 | 74.0 |
| ProgramBench | 29.1 | 20.3 | 17.5 | 19.0 | 23.0 | 37.0 |
| NL2Repo-Bench | 68.2 | 65.4 | 58.0 | 58.0 | 56.8 | 75.3 |
| Automation-Bench v1.0.6 | 60.5 | 54.8 | 46.7 | 48.8 | 45.8 | 50.3 |
| Agents’ Last Exam | 35.4 | 31.8 | 27.6 | 28.5 | 26.7 | 28.6 |
| Apex Bench v1.1 | 72.1 | 64.6 | 47.8 | 56.6 | 54.3 | 65.8 |
| Chartography (w/tools) | 83.0 | 78.9 | 68.1 | — | 79.9 | 84.0 |
| BabyVision (w/tools) | 92.5 | 89.6 | 85.7 | — | 88.9 | 94.1 |
| ZeroBench-main (w/tools) | 51.0 | 49.0 | 41.0 | — | 53.0 | 52.0 |
† Text-only HLE subset. Compare 44.0 with 39.1 for DeepSeek’s text-only change; do not compare 44.0 directly with other models’ full-set scores. DeepSeek specifies Claude Code for Terminal-Bench 4.0 and Mini-SWE-V2 for DeepSWE v1.1. Its changelog specifies Pass@5 for ZeroBench-main. An em dash means no result was supplied, not zero.
Where the update looks strongest
Our calculations put the largest absolute increase at 11.1 score points on Terminal-Bench 4.0. ProgramBench rises 8.8 points, about 43% relative to its previous score. These are more substantial movements than DeepSWE’s 2.8-point increase. The relative percentage is a change in a particular benchmark score, not a promise that a developer will finish 43% more work.
The pattern suggests a useful hypothesis: 1017 may improve how a coding agent carries a task through tool use, execution and revision. A good private evaluation would deliberately include those stages. Measuring only the first code snippet would miss much of the behavior this release targets.
The table also leaves meaningful weaknesses visible. Against Opus 5, 1017 leads on four rows: DeepSWE, Automation-Bench, Agents’ Last Exam and Apex Bench. It trails on the other seven. Opus 5’s higher HLE and ProgramBench results make a blanket “DeepSeek beats Claude” headline difficult to defend.
What the scores cannot tell you
Harnesses determine which tools an agent can use, how it recovers from failures, how context is managed and when execution stops. The same weights can behave differently inside two coding products. The earlier V4.1 card itself reports different results across agent scaffolds, which is a reason to test your actual integration.
The 1017 table does not provide confidence intervals or a complete per-task failure analysis. A small score difference is therefore a ranking in this table, not proof of statistical significance. Pass@5 gives a model multiple attempts and cannot be read as first-attempt reliability. Visual results marked “with tools” also measure a larger workflow than an unaided image answer.
There is another practical gap: a fixed benchmark does not measure whether an agent understands an ambiguous brief, chooses a maintainable design, preserves an existing app’s behavior or satisfies a human reviewer. Those are precisely the failure modes that make a cheap coding session expensive.
How it compares with today’s frontier models
DeepSeek’s launch comparison is useful but incomplete for an October 17 purchase decision. Here is the current context, with each vendor’s results kept attached to its own evaluation.
| Alternative | What is established | What remains unproven against 1017 |
|---|---|---|
| GPT-6 Astra | OpenAI’s demanding-work model; text/image input, 1.05M context, 128K maximum output; standard input/output rates of $10/$50 per million tokens | Absent from DeepSeek’s launch table; no controlled Kingy head-to-head for this update |
| GPT-6.1 Sol | A lower-price OpenAI alternative at $2/$10; 1.05M context and 128K maximum output | Older GPT-5.6 Sol results cannot stand in for this model |
| Claude Sonnet 5.5 / Opus 5.5 | Anthropic lists $2/$10 for Sonnet and $4/$20 for Opus in its Sonnet 5.5 announcement | DeepSeek compares with Opus 5, not either 5.5 model |
| Gemini 4 Argon | Text, image, audio, video and PDF input; unified 1M context and long decode; introductory $2/$10 rates | DeepSeek is absent from Google’s Argon comparison; broader media support is a separate product advantage |
Sources: GPT-6 Astra specifications, GPT-6.1 Sol specifications, Sonnet and Opus 5.5 pricing, Argon specifications and Google’s pricing. These are token list prices, not subscription prices or equal-cost quality measurements.
There is some useful overlapping evidence. Google’s Argon model card reports DeepSWE v1.1 scores of 77.9 for Argon, 74.1 for Astra and 74.2 for Opus 5.5. Its Terminal-Bench 4.0 values are 57.4, 58.2 and 66.4 respectively. DeepSeek reports 77.0 and 42.3 on those named benchmarks.
Those separately reported numbers suggest that DeepSeek’s software-engineering result deserves attention, while the terminal result leaves considerable room to improve. They do not establish a controlled ranking across the two releases: the model snapshots, harnesses, budgets and evaluation details must match before the gaps can be interpreted that way. We deliberately keep them out of the shared launch chart.
For a buyer, the useful question is whether a more expensive model prevents enough failed runs and review work to justify its price. A premium model that reliably solves a difficult migration can be worth more than dozens of cheap attempts. A routine repository edit that passes the same acceptance tests is a poor place to pay a premium automatically.
API pricing: unchanged, with a large off-peak discount
DeepSeek’s current rate card lists the following US-dollar prices per million tokens. The 1017 upgrade keeps these rates.
| Token type | Off-peak | Peak |
|---|---|---|
| Input: cache miss | $0.15 | $0.30 |
| Input: cache hit | $0.003 | $0.006 |
| Output | $0.60 | $1.20 |
Peak periods are 01:00–04:00 and 06:00–10:00 UTC on weekdays, excluding Chinese public holidays. Other hours, including weekends, are off-peak. Cache-hit pricing requires an actual hit; budget uncached input unless your usage data supports a better assumption.
What a real workload might cost
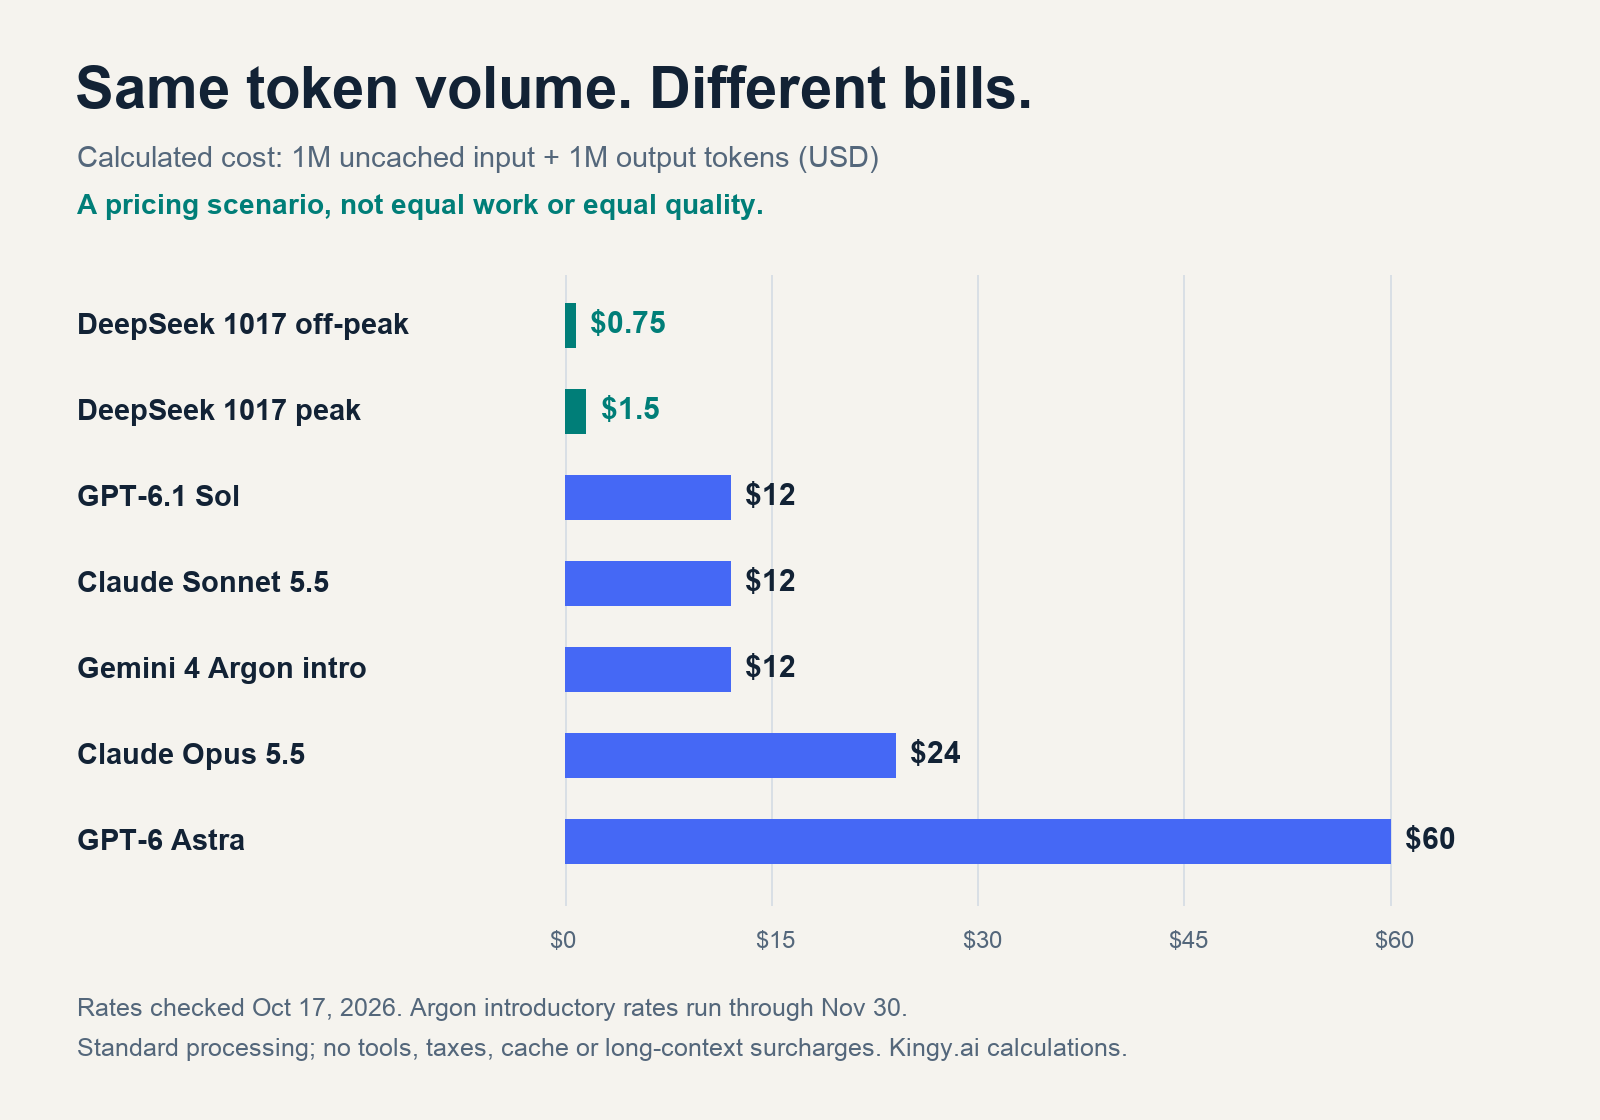
Consider a workload totaling one million uncached input tokens and 200,000 billable output tokens, distributed across requests below any long-context surcharge threshold. DeepSeek costs $0.27 off-peak or $0.54 at peak. The same token counts at $2/$10 cost $4; at Opus 5.5’s $4/$20, $8; at Astra’s $10/$50, $20. These are arithmetic examples, not measured task costs.
The larger chart uses equal totals of one million input and one million output tokens. The $0.75 DeepSeek off-peak bill is 16 times lower than the $12 scenario for the $2/$10 group. That ratio can change when models generate different amounts of reasoning, retry tasks or make different tool calls. Gemini’s standard introductory input/output rates rise to $4/$20 on December 1, 2026. OpenAI also applies higher Astra pricing above 272K input tokens per request; our example does not use that tier.
For planning, use this calculation: token cost = uncached input × uncached rate + cached input × cached rate + billable output × output rate, with counts expressed in millions. Add tool fees and execution infrastructure. Then divide by the number of outputs that pass your acceptance checks. That last step measures what the budget bought.
Search and Fetch add another meter
Alongside the model update, DeepSeek opened its Search and Fetch APIs. Each endpoint costs $0.75 per 1,000 successful requests. The temporary exemption is narrower: server-side calls through DeepSeek Harness, Claude Code and Codex are free for DeepSeek API users until October 31 at 16:00 UTC, equivalent to November 1 at 00:00 Beijing time. Do not assume standalone requests share that exemption.
At the published rates, 1,000 searches plus 1,000 fetches add $1.50 before token costs. For an inexpensive model, external actions can quickly become a meaningful share of the bill. DeepSeek’s lower token price does not remove the need for limits on agent loops.
Open weights: DeepSeek, Kimi K3, GLM-5.3 and a smaller Qwen
DeepSeek’s MIT release is a practical advantage for organizations that need control over inference or modification. “Open source” is often used loosely in model marketing. Here the concrete verified fact is that the 1017 repository and weights carry MIT; that does not establish that the full training dataset or training pipeline is available.
| Model | Deployment and license | How to interpret the comparison |
|---|---|---|
| DeepSeek V4.1 Flash 1017 | MIT weights; large MoE with native vision | A direct candidate for hosted coding agents and substantial self-hosted deployments |
| Kimi K3 | 2.8T total / 104B active; 1M context; custom Kimi K3 License | Direct launch-table rival; its scale and license require a different deployment review |
| GLM-5.3 | Open weights under the GLM-5.3 License; published local-serving guidance | Direct launch-table rival, particularly relevant to coding workflows |
| Qwen3.8-27B | 27B dense vision-language model; Apache 2.0; 262,144 native context, extendable to 1M | A much smaller local-deployment alternative; absent from DeepSeek’s 1017 table |
Sources: Kimi K3 model card, Kimi license, GLM-5.3 card, GLM license and Qwen3.8-27B card. Kimi and GLM have custom terms; verify the actual license for your intended service instead of assuming MIT-like conditions.
In DeepSeek’s own table, 1017 beats K3 on ten of eleven listed rows using the full HLE score, and leads GLM-5.3 on all seven comparable non-HLE rows. That is evidence from DeepSeek’s evaluation, not a universal open-model crown. GLM’s own card also illustrates why attribution matters: it reports AutomationBench v1.0.6 at 48.2, while DeepSeek’s comparison lists GLM at 48.8. We preserve each source’s number rather than manufacture a single reconciled score.
For a local buyer, a smaller model can be the better choice even with lower benchmark scores. It can offer lower hardware cost, easier updates and a simpler operating environment. Our earlier DeepSeek/Qwen trial records a specific previous-version comparison; it is not fresh evidence about 1017.
Self-hosting DeepSeek also requires more than a weight download. Runtime support, quantization fidelity, memory residency, prompt encoding and concurrency all matter. The 1017 card says the release does not include a Jinja chat template and points to its encoding implementation and the maintained deepseek-recipe toolkit. A convenient third-party quantization should be evaluated as that particular artifact, with its own quality and speed measurements. See our DeepSeek local hardware guide for the broader memory-planning issues.
Availability, model IDs and integration details
DeepSeek confirms the update is live on its chat website, app and API. Official weights are on Hugging Face and ModelScope. OpenRouter’s live model catalog also lists deepseek/deepseek-v4.1-flash-1017 as checked for this article. A catalog listing establishes advertised access, not guaranteed throughput. For our own pilot we successfully used the exact dated model through Vercel AI Gateway; those results describe that hosted route.
The direct API uses deepseek-flash. Legacy Flash aliases still route to the latest model according to DeepSeek’s documentation. That convenience also means an unchanged application configuration can receive changed model behavior. Record the date and resolved version when evaluating a rolling alias, and rerun regression checks after an upgrade.
The hosted thinking guide documents low, high and max, with thinking enabled and effort high by default. Its named controls differ from the numeric 1–100 effort described for the open model. For thinking-mode tool conversations, preserve the returned reasoning_content as instructed; dropping it can cause API errors. This integration detail can matter more than a small benchmark lead.
A minimal request using the OpenAI-compatible client looks like this. It is documentation-style sample code; our hosted pilot uses a separate harness.
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["DEEPSEEK_API_KEY"],
    base_url="https://api.deepseek.com",
)
response = client.chat.completions.create(
    model="deepseek-flash",
    messages=[{"role": "user", "content": "Review this patch for regressions."}],
    reasoning_effort="high",
    max_tokens=4096,
    extra_body={"thinking": {"type": "enabled"}},
)
print(response.choices[0].message.content)
For screenshots and charts, the vision guide documents image input via URLs, inline data or uploaded files. Supported image formats include JPEG, PNG, GIF and WebP. Image understanding should not be confused with native image generation, audio input or video generation. DeepSeek’s release demos generate projects using an agent workflow; the model itself produces text.
Who should test it, and what should pass first
My editorial view is that 1017 deserves an early place in a coding team’s evaluation queue. Its strongest case combines a low hosted price, available weights and reported gains on tasks that require an agent to act. The remaining question is how much of that improvement survives in your repository and chosen harness.
Use it first on bounded work: a bug with a reproducible failure, a small feature with clear tests, a command-line repair or a repository task with inspectable outputs. Keep the premium fallback available for tasks that repeatedly fail, briefs requiring substantial judgment and work where review time dominates token cost. For audio/video input, choose a model with documented support for that modality.
Before switching a production agent, run a small paired evaluation on real tasks. Freeze the starting repository, tool permissions and acceptance checks. Give each model the same information, then retain failed attempts as well as successes. Measure elapsed time, billable tokens, retries and reviewer corrections. Check whether the delivered project runs, whether existing tests still pass and whether the requested behavior is present.
The metric I would use to decide is cost per accepted result, alongside the time a person spends reviewing it. If 1017 passes the same checks at a lower total cost, route that class of work to it. If it needs repeated rescue, keep the task with the model that finishes it reliably.
Sources and evidence notes
The reader-supplied X post was a discovery lead. Release status, specifications and numerical claims were checked against the first-party documents linked throughout the article. The benchmark table is DeepSeek’s comparison; the current-frontier discussion uses separately attributed vendor documents. All dollar examples are calculated from listed rates checked October 17, 2026, exclude taxes and account-specific terms, and do not imply that equal token counts produce equal quality. Prices and rolling API aliases can change.
Trending on Kingy
Keep reading with the stories getting the most attention now.
The Kingy Brief
Get The Kingy Brief.
AI changes, original tests and one practical thing to try. Fridays at 09:00 Vancouver time.
Free · Double opt-in · Unsubscribe anytime
Sign up for The Kingy Brief on Beehiiv.
Signup help and newsletter schedule
Signup form provided by Beehiiv. After submitting, check your inbox for "Confirm your subscription to The Kingy Brief" and open its confirmation link. Check Spam or Promotions if you cannot find it.
Fridays at 09:00 Vancouver time: source-checked AI changes, original tests and one practical thing to try. We skip a week when there is not enough verified material. Free. Unsubscribe anytime.