
OpenAI gives professional AI two price points
OpenAI released GPT‑6.2 Astra and GPT‑6.2 Sol for ChatGPT Work, Codex, and its API. Astra is the flagship for demanding projects. Sol is the less expensive model for everyday work. OpenAI dated the announcement November 17. Coverage confirmed Astra’s release by 2:26 a.m. Philippine time on November 18.
The launch announcement gives readers two prices to pay attention to. Astra’s standard API input and output rates fell 20% from the original GPT‑6 Astra. Sol keeps its predecessor’s rates. OpenAI says both models can finish demanding tasks while generating fewer output tokens. For anyone who regularly pays for AI to draft, revise, or work through a problem, those savings could matter more than a new name in the model picker.
Astra aims for work you can hand over
A professional document can contain all the right facts and still need an hour of cleanup. The slide titles wander. The spreadsheet puts assumptions in the wrong cells. The report follows a structure nobody at the company uses. OpenAI says Astra is better at following supplied templates and observing the conventions of the work it’s asked to do.
Think of a team turning a project review into a deck for an executive meeting. Someone has to decide what goes on the first slide, which figures deserve a chart, and what can wait for the appendix. A model that respects the template and carries the right facts into it could save time on the second draft, where much of the work usually hides.
Sol takes the jobs that come around again
GPT‑6.2 Sol is built for work that arrives in a steady stream. A developer needs a test updated. A producer wants notes from several documents condensed into a brief. An operations team turns the same sort of source material into a report every Friday.
OpenAI says Sol keeps the rates of GPT‑6.1 Sol and can use fewer output tokens on demanding work. That gives the company a way to make the model cheaper to use for some jobs without cutting the posted rate. For recurring work, a small difference per request can add up. The effect is easiest to see when the inputs and the expected result stay fairly consistent.
What a million tokens costs
At standard API rates, Astra costs $8 per million input tokens, $0.40 per million cached input tokens, and $40 per million output tokens. Sol costs $2, $0.10, and $10 in those same categories. In each case, Sol’s rate is one quarter of Astra’s. OpenAI’s pricing documentation also specifies higher rates on requests above 272,000 input tokens.
Those figures describe how the API meters usage. The cost of a particular job depends on what goes in and how much the model generates. Take a standard request with 10,000 uncached input tokens and 2,000 billed output tokens. The token charge would be $0.16 on Astra or $0.04 on Sol, before tool fees or additional requests. A thousand identical requests alone would cost $160 and $40, respectively.
A shorter answer can mean a smaller bill
A token is a piece of text the system processes or generates. A short paragraph may take dozens of tokens, while a large set of source documents can take thousands. Jobs that call for extended reasoning or long deliverables can build up output charges even if the person asking made a short request.
OpenAI says Astra scored 6.2 percentage points higher than its predecessor on GDPval-v2, a professional-work evaluation, while using 22% fewer output tokens. That result gives the token-efficiency claim some context. It came from a particular set of tasks. For a team generating documents every day, the more telling measure would be how much billed output it takes to get a draft that someone can actually use.
The professional benchmark behind the headline
On Agents’ Last Exam, a benchmark of multistep professional tasks, OpenAI reports that Astra improved by 5.2 points over GPT‑6 Astra while costing less than a third as much per task. The test aims to capture jobs that require sustained work. That’s closer to assembling a deliverable from several sources than to answering a single quiz question.
The cost figure matters because the newer model’s list price fell by a smaller percentage. How much work a model does along the way can affect the final bill as much as the posted rate does. The comparison also gives readers a specific workload to attach to the claim. A different project, with a different mix of files and tools, can produce a different cost.
What independent testing found
Artificial Analysis scored Astra 62 and Sol 57 at maximum effort on its Intelligence Index. Its Astra result placed the model below Anthropic’s Claude Fable 5.2 on that index. The Decoder reported that Astra was among the strongest options when it considered both score and cost. The result is a more useful snapshot than a claim that one model wins.
A broad index can help narrow a shortlist. It blends several kinds of work into a single figure, so its ranking has limited power to explain which model will handle a particular job best. A software team may care about a change passing its test suite. A newsroom may care more about whether a draft preserves the meaning of a source.
Computer use moves into the creative workflow
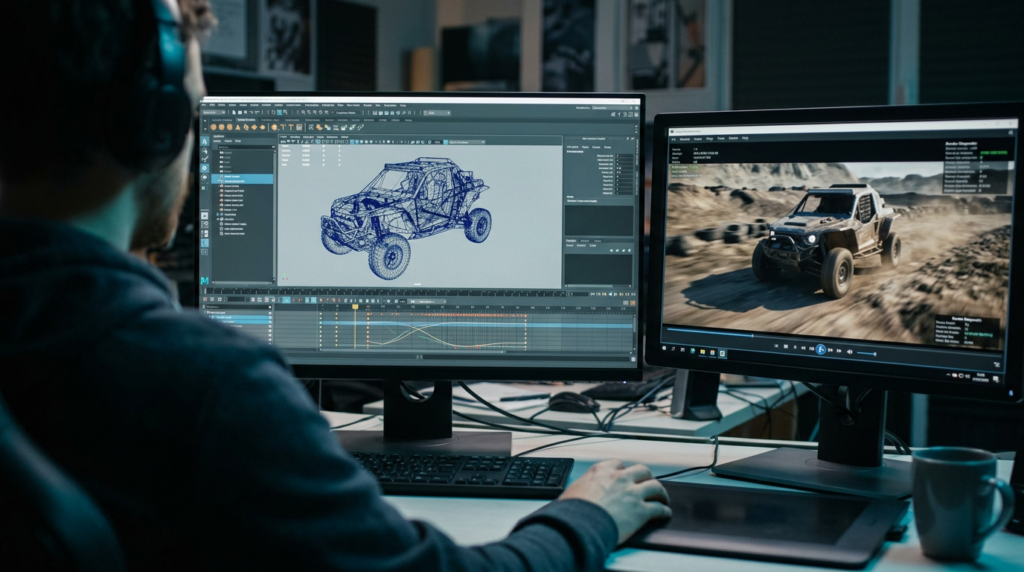
One of OpenAI’s demos follows Astra through a 3D project that combines a vehicle model, a physics solver, and an animation in Blender. Its most practical detail is that the work has several dependent steps. Geometry needs to make sense before the simulation can tell a useful story.
That’s the sort of handoff computer-use improvements aim to handle. In ordinary work, it might mean opening a spreadsheet, finding the right tab, and carrying a figure to the correct place in a presentation. A model has to keep track of the goal while it moves between tools and recover when a window or layout differs from what it expected.
Codex gets another choice for software projects
The two models give Codex users a choice about how much effort to put into a software task. OpenAI points to Astra for complex work such as tracing a bug across services. Sol is aimed at everyday coding and workflows that use tools. A small change in a familiar repository presents a different problem from a regression that appears in three services at once.
For a developer, the real output is the change that survives review. A patch can pass one test and still violate an assumption elsewhere. A short explanation can also save someone a long detour through unfamiliar files. These models will show their value in how well they handle that mix of investigation, small edits, and the occasional genuinely difficult fix.
What Astra brings to scientific work
OpenAI also reports a nine-percentage-point improvement over GPT‑6 Astra on Terminal-Bench-Science, at less than one third of the cost in that evaluation. The test covers scientific tasks carried out in a terminal. The reported gains apply to that benchmark.
One way to picture the appeal is a researcher sorting through analytical outputs before preparing a figure. The work can involve tracing which script produced a table and documenting choices so the figure can be reproduced later. Good assistance makes the work easier to inspect. Researchers still have to verify the inputs, methods, and conclusions before they use the output to support a claim.
OpenAI tightens the cybersecurity safeguards
OpenAI’s system card says both models meet the Critical threshold for cybersecurity capabilities in its Preparedness Framework. In response, the company tightened default restrictions for higher-risk cybersecurity assistance and requires additional vetting for expanded access. OpenAI acknowledges that the restrictions can affect some legitimate security-testing work.
The launch also emphasizes defensive uses such as writing secure code and helping teams review proposed repairs. The ordinary example is a developer who wants to understand whether an application handles sensitive data appropriately. A model can help flag code for review or explain the possible consequence of a change. The developer still needs to check that any repair addresses the weakness and preserves how the application is supposed to behave.
Where Astra and Sol are available
OpenAI’s launch post names Plus, Pro, Enterprise, and Edu users for access in ChatGPT Work and Codex. Its Help Center describes a phased rollout and lists additional eligible workspace types, including Business. Workspace settings can affect what an individual sees, and eligible Enterprise and Edu users may need their administrator to enable access.
Work is the place for longer, multistep tasks such as turning source files into a deliverable. Codex is the software development environment. The rollout applies to those two experiences, so users looking for either new model should check the picker there. API customers have a separate route through the new model IDs. Availability in a workspace and API billing are separate questions.
Ultrafast adds a speed option
OpenAI offered Ultrafast for both GPT‑6.2 models through the API at launch. Pro 500 subscribers can use it with either model. Pro 200 subscribers get an Ultrafast option for Sol in Codex. The company bills the speed tier differently from standard use, so the time saved comes with a higher charge or faster consumption of an included allowance.
The appeal depends on what people are waiting for. When a colleague is blocked until a set of changes is ready to review, shaving time off that job has a practical benefit. A report prepared overnight has more flexibility. The speed option makes the most sense as a choice tied to the job’s deadline, especially when the same team runs both urgent and routine work.
What developers should know about the API
Both models support Responses and Chat Completions. OpenAI’s API guide says tool calling requires Responses. That distinction matters for an application that looks up a file, retrieves an order status, or calls an internal service before answering. The model name is only one part of how the application reaches that result.
An application that processes a standard set of documents may also care about cached input. The lower cached rate applies when the system can reuse eligible material it has processed before. A stable block of instructions could qualify, for example, while the latest customer request brings in new text. The balance between reusable and fresh material changes what two apparently similar requests can cost.
How the two models fit into one project
Picture a small team preparing an internal report. It uses Sol to pull recurring themes from weekly notes and draft short descriptions of the charts. Then it uses Astra to bring together source documents that disagree about a timeline and shape the findings into a deck for review. The team can compare the draft against the original material before anyone shares it.
That example shows why the price gap is interesting. One project can include a pile of routine steps and a few decisions that demand careful reading. A lower price on the routine steps leaves more room in the budget for the tougher work. The model choice can follow the job at hand, even within a single afternoon.
The savings have to survive the second draft
The release gives OpenAI customers a less expensive Astra and an updated Sol at a familiar rate. The companies and individuals who run these models will find out how those numbers translate into work that arrives on time and needs fewer revisions. A credible benchmark result earns a closer look. The repeat job shows what happens after the demo.
For people writing reports, reviewing code, or building applications, the best outcome is easy to recognize. A colleague opens the file and sees the right numbers in the right places. A code reviewer understands the proposed fix at a glance. The bill for repeating that process next week fits the budget. Those are the results that could make GPT‑6.2 a meaningful upgrade.
Sources
- OpenAI — GPT‑6.2 Astra and Sol launch, pricing, and benchmarks
- Investor’s Business Daily — GPT‑6.2 Astra launch coverage
- The Decoder — API price changes and benchmark results
- Artificial Analysis — GPT‑6.2 Astra independent benchmark results
- Artificial Analysis — GPT‑6.2 Sol independent benchmark results
- OpenAI Deployment Safety Hub — GPT‑6.2 system card and cybersecurity safeguards
- OpenAI Help Center — ChatGPT Work, Codex, and Ultrafast access
- OpenAI API Documentation — GPT‑6.2 Astra model and pricing
- OpenAI API Documentation — GPT‑6.2 Sol model and pricing
- OpenAI API Documentation — GPT‑6.2 tool calling and migration