
Short answer: on a 24GB graphics card, Gemma 4 31B (Q4_K_M, 18.69 GB) is our pick: 92.5 on our 9-job board and 99% on Kingy Lab’s writing-to-rules tasks, and it just fits. On the board it can’t be separated from Qwen3.8 27B’s 2-bit file (the ranges overlap), which leaves far more room. On a 24GB Mac, Gemma 4 31B doesn’t fit; Qwen3.8 27B does, and we measured it on our own 24GB MacBook Pro at 12.8 to 13.8 tokens a second.
Lucy AI Studio sent free by Cephalon, which paid for an earlier Kingy AI video. Cephalon has no say in results. Mac and laptop bought by Kingy AI.
Who this page is for
People with a PC graphics card that has 24 GB of memory, and people with a 24GB Mac or other shared-memory computer. The two get different answers: by our fit rule the card can use 22.5 GB, the Mac 16.0 GB.
24GB graphics card: top picks
| Job | Our pick | File to download | Score | Speed |
|---|---|---|---|---|
| Coding and building apps | Gemma 4 31B or Qwen3.8 27B | gemma-4-31B-it-Q4_K_M.gguf (18.69 GB) or Qwen3.8-27B-UD-IQ2_S.gguf (8.37 GB) |
Gemma coding jobs 96.0; Qwen3.8 2-bit 98.5 (ranges overlap: a tie) | Speed not measured yet on a 24GB card |
| Writing to instructions | Gemma 4 31B | gemma-4-31B-it-Q4_K_M.gguf (18.69 GB) |
Kingy Lab writing-to-rules 99%; board all 9 jobs 92.5 | Speed not measured yet |
| Long documents and files | Qwen3.8 27B, 3-bit file | Qwen3.8-27B-UD-Q3_K_XL.gguf (13.15 GB) |
long-document and file jobs 100.0; all 9 jobs 89.8 (likely 79.8 to 99.9); Kingy Lab everyday 98% | Different file: Q4_K_M 49.1 tok/s (context not stated) 24GB GPU, Kingy measured Aug 17, 2026 (hub) |
| Faster replies | Gemma 4 26B A4B | gemma-4-26B-A4B-it-Q4_K_M.gguf (16.80 GB) |
all 9 jobs 85.2 (likely 77.6 to 92.9); Kingy Lab 93% | Speed not measured yet on a 24GB card; 54.5 tok/s on real jobs on our 128GB Lucy (Nov 14-15, 2026) |
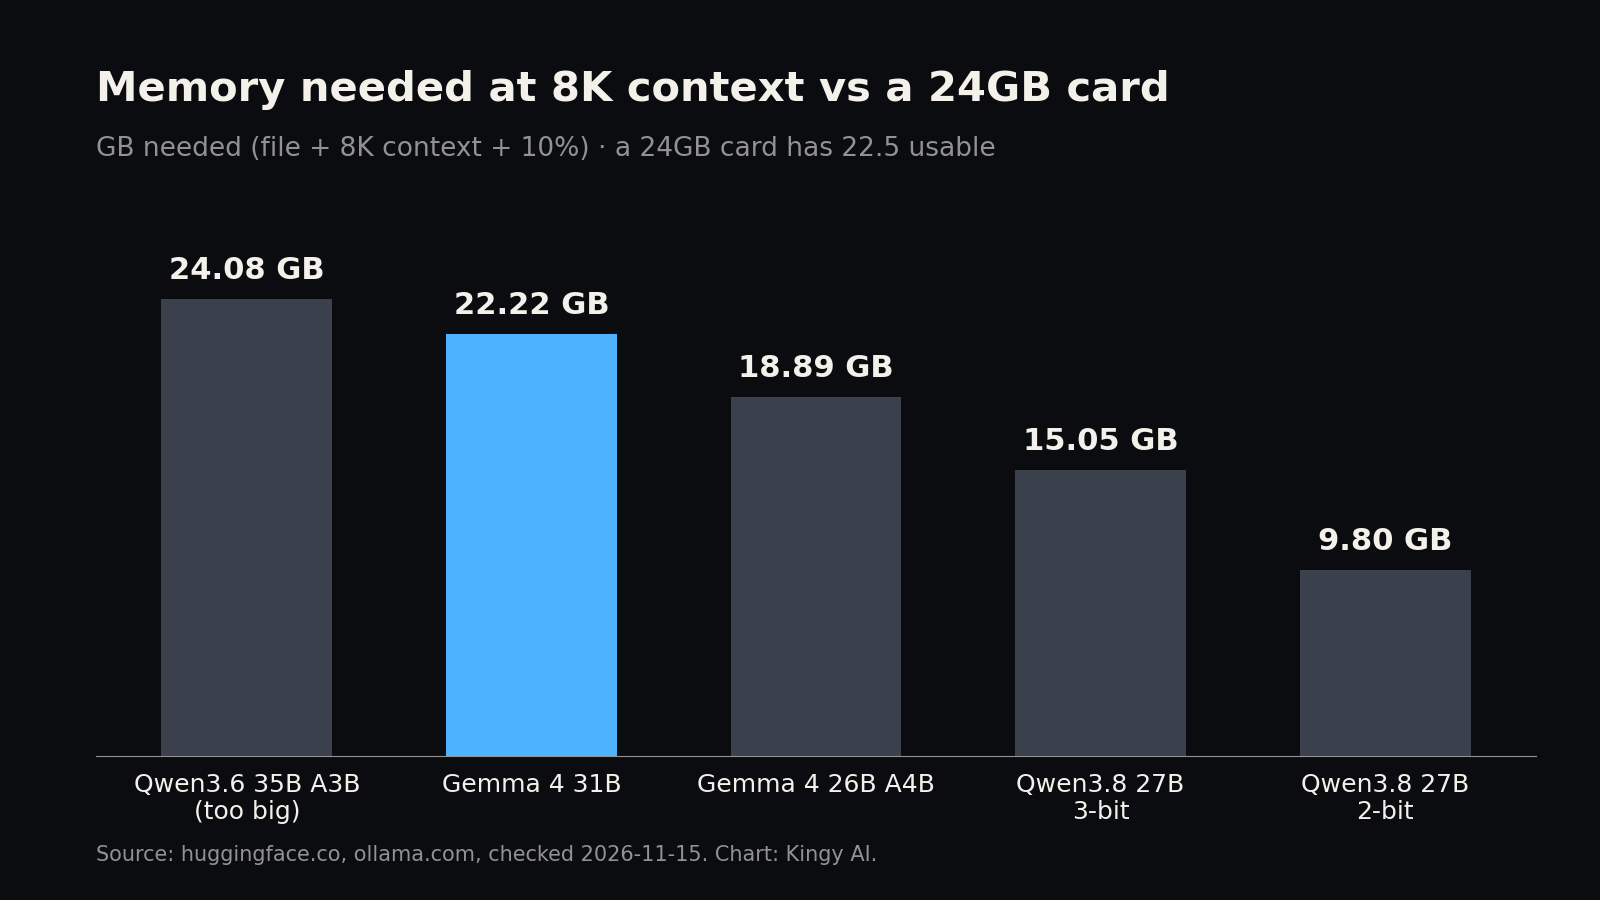
The catch with Gemma 4 31B: it needs 22.22 GB at 8K and the card has 22.5, so only 0.3 GB is spare. It does not fit with 32K (32,768 tokens) of conversation (24.43 GB). Qwen3.8 27B’s 3-bit file leaves 7.4 GB and fits 32K easily. On a 24GB card you could also run a bigger Qwen3.8 27B file (the 4-bit UD-Q4_K_XL is 17.66 GB in today’s download). We measured a different 4-bit file, Q4_K_M, at 49.1 tokens a second in August, but haven’t scored either on the board.
Not on the list: Qwen3.6 35B A3B, which tied for the top Kingy Lab score (98%), needs 24.08 GB, 1.6 GB more than a 24GB card has by our rule. It would run with some of it in system memory, but we haven’t measured that on a 24GB card.
| Model | File we scored | Memory needed, 8K context | 24GB card (22.5 GB usable) | Board score, all 9 jobs (on our Lucy) |
|---|---|---|---|---|
| Qwen3 4B | Qwen3-4B-Q4_K_M.gguf (2.50 GB) |
4.08 GB | Fits, 18.4 GB spare | 64.5 |
| Qwen3 8B | Qwen3-8B-Q4_K_M.gguf (5.03 GB) |
6.86 GB | Fits, 15.6 GB spare | 78.6 |
| Qwen3.8 27B, 2-bit file | Qwen3.8-27B-UD-IQ2_S.gguf (8.37 GB) |
9.80 GB | Fits, 12.7 GB spare | 96.1 |
| Qwen3.8 27B, 3-bit file | Qwen3.8-27B-UD-Q3_K_XL.gguf (13.15 GB) |
15.05 GB | Fits, 7.4 GB spare | 89.8 |
| Gemma 4 26B A4B | gemma-4-26B-A4B-it-Q4_K_M.gguf (16.80 GB) |
18.89 GB | Fits, 3.6 GB spare | 85.2 |
| Gemma 4 31B | gemma-4-31B-it-Q4_K_M.gguf (18.69 GB) |
22.22 GB | Fits, 0.3 GB spare | 92.5 |
| Qwen3.6 35B A3B | Ollama qwen3.6:35b (Q4_K_M) (21.72 GB) |
24.08 GB | No: needs 24.08 GB, 1.6 GB over | 90.1 |
24GB Mac: top picks
| Job | Our pick | File to download | Score | Speed |
|---|---|---|---|---|
| Best on code | Qwen3.8 27B, 3-bit file | Qwen3.8-27B-UD-Q3_K_XL.gguf (13.15 GB) |
all 9 jobs 89.8 (likely 79.8 to 99.9); Kingy Lab 97%; 13 of 14 hidden code tests on our Mac (2-bit: 10) | 12.8 tok/s with 8K loaded MacBook Pro M4 Pro 24 GB, Kingy measured Nov 3, 2026 |
| Top board score, more room | Qwen3.8 27B, 2-bit file | Qwen3.8-27B-UD-IQ2_S.gguf (8.37 GB) |
all 9 jobs 96.1 (likely 91.4 to 100.0) | 13.8 tok/s with 8K loaded MacBook Pro M4 Pro 24 GB, Kingy measured Nov 3, 2026 |
| Everyday, quick | Qwen3 8B | Qwen3-8B-Q4_K_M.gguf (5.03 GB) |
all 9 jobs 72.3 (likely 61.7 to 83.0) (on our Mac) | 33.2 tok/s with 8K loaded; 36.1 on real jobs MacBook Pro M4 Pro 24 GB, Kingy measured Nov 3 and 14, 2026 |
The 3-bit file leaves only 0.9 GB of the 16.0 GB our rule allows, so close other big apps; the 2-bit file leaves 6.2 GB, and the board can’t separate the two. Both make you wait about 70 seconds before answering an 8,192-token prompt on this Mac (our Nov 3 test). For quick everyday jobs, Qwen3 8B answered far sooner and matched ChatGPT on all ten everyday tasks in that test. Gemma 4 26B A4B (18.89 GB needed) and Gemma 4 31B (22.22 GB) don’t fit a 24GB Mac by our rule.
| Model | File we scored | Memory needed, 8K context | 24GB Mac (16.0 GB usable) | Board score, all 9 jobs (on our Lucy) |
|---|---|---|---|---|
| Qwen3 4B | Qwen3-4B-Q4_K_M.gguf (2.50 GB) |
4.08 GB | Fits, 11.9 GB spare | 64.5 |
| Qwen3 8B | Qwen3-8B-Q4_K_M.gguf (5.03 GB) |
6.86 GB | Fits, 9.1 GB spare | 78.6 |
| Qwen3.8 27B, 2-bit file | Qwen3.8-27B-UD-IQ2_S.gguf (8.37 GB) |
9.80 GB | Fits, 6.2 GB spare | 96.1 |
| Qwen3.8 27B, 3-bit file | Qwen3.8-27B-UD-Q3_K_XL.gguf (13.15 GB) |
15.05 GB | Fits, 0.9 GB spare | 89.8 |
| Gemma 4 26B A4B | gemma-4-26B-A4B-it-Q4_K_M.gguf (16.80 GB) |
18.89 GB | No: needs 18.89 GB, 2.9 GB over | 85.2 |
Speed
On the 24GB Mac, all speeds above are Kingy measured on one MacBook Pro (M4 Pro). On a 24GB card, our only measurement so far is the August Qwen3.8 27B Q4_K_M run; we’ll add card speeds here when we measure them. The chart shows how much memory each model needs against the card’s 22.5 GB:
How to run it
The easy way: LM Studio. It has a built-in model downloader. Open the Discover tab (Cmd+2 on a Mac, Ctrl+2 on Windows or Linux), paste the repository name shown for each model below into the search bar, and pick the file with the same quant name (LM Studio’s guide).
The direct way: llama.cpp, the engine we test with. Install it with winget install llama.cpp on Windows or brew install llama.cpp on a Mac (install guide). -hf downloads a model from Hugging Face and -c 8192 sets the 8K context our fit numbers assume. -hf also downloads and loads a model’s vision file if it has one (about 1.2 GB for Gemma 4); our fit numbers are for text only, so the commands below add --no-mmproj to skip it (server options).
- Gemma 4 31B:
llama-server -hf lmstudio-community/gemma-4-31B-it-GGUF:Q4_K_M -c 8192 --no-mmproj, or searchlmstudio-community/gemma-4-31B-it-GGUFin LM Studio and pick Q4_K_M. - Qwen3.8 27B, 3-bit file: Unsloth replaced many of its Qwen3.8 27B files, including both files we scored, on November 10 to 12, 2026 (commit history), so a plain download now gets a newer file than the one we scored. To use the exact file we tested, download
Qwen3.8-27B-UD-Q3_K_XL.gguffrom the August 20 revision, then runllama-server -m Qwen3.8-27B-UD-Q3_K_XL.gguf -c 8192. The newer file has the same name; we haven’t scored it. - Qwen3.8 27B, 2-bit file: Unsloth replaced many of its Qwen3.8 27B files, including both files we scored, on November 10 to 12, 2026 (commit history), so a plain download now gets a newer file than the one we scored. To use the exact file we tested, download
Qwen3.8-27B-UD-IQ2_S.gguffrom the August 20 revision, then runllama-server -m Qwen3.8-27B-UD-IQ2_S.gguf -c 8192. The newer file has the same name; we haven’t scored it. - Gemma 4 26B A4B:
llama-server -hf lmstudio-community/gemma-4-26B-A4B-it-GGUF:Q4_K_M -c 8192 --no-mmproj, or searchlmstudio-community/gemma-4-26B-A4B-it-GGUFin LM Studio and pick Q4_K_M. - Qwen3 8B:
llama-server -hf Qwen/Qwen3-8B-GGUF:Q4_K_M -c 8192 --no-mmproj, or searchQwen/Qwen3-8B-GGUFin LM Studio and pick Q4_K_M.
MLX on a Mac. Apple’s own MLX-LM runs models converted to MLX format: pip install mlx-lm, then mlx_lm.generate --model <an MLX model on Hugging Face> --prompt "hello" (or mlx_lm.chat for a chat session). MLX files are different downloads from the ones above, with different sizes, and we didn’t score or time them, so check the size before you download.
How we tested
Kingy tested every score on this page on our own machines. Nothing here is copied from a model maker’s chart.
- Board score. Kingy’s local AI board v0.2 gives each model the same 9 real jobs: a landing page, a budget tracker app, a browser game, a Python bug fix, a chart from a messy spreadsheet, questions about a long document, a job that means searching 37 files with tools, a motion title and a video cut. Scripts check each result; no AI judges another AI. Every job runs 3 times, so each score is the average of 27 runs, with the makers’ own settings and the exact files named on this page (checked by fingerprint). The main runs were on our Lucy AI Studio (AMD Ryzen AI Max+ 395, 128 GB), November 14 to 15, 2026 (UTC). If a check script stopped early on a run, the checks it didn’t reach count as fails. “Likely range” is a rough 95% range around the average: when two ranges overlap, we treat the board as unable to tell those two models apart.
- Writing and everyday scores come from Kingy Lab’s 120-task test (November 7 to 12, 2026), which marks 60 everyday jobs, 30 coding tasks and 30 writing tasks with rules to follow.
- Fit uses the same rule as our Local AI checker: memory needed = file size + room for 8,192 tokens (8K) of conversation (the “KV cache”, from each model’s official settings file) + 10%. We count a graphics card’s memory minus 1.5 GB for the screen and driver, and, as a cautious rule of our own, two-thirds of a Mac’s memory up to 36 GB (three-quarters above that), leaving the rest for macOS and your apps. macOS itself lets the graphics side use more (about 19 GB of our 24GB MacBook Pro), so a Mac may fit a little more than we say. For Qwen3.6 and Qwen3.8 we leave out a small fixed memory state (under 0.2 GB). GB means a billion bytes. File sizes come from Hugging Face and Ollama, checked November 15, 2026. A “No” here means it doesn’t fit in that memory by this rule.
- Speed is only shown where we measured it, with the chip and date. Everything else says “not measured yet”. We never estimate a speed on these pages. Speed on real jobs is how fast the model wrote during the 27 board runs: tokens written divided by the time spent writing, from llama.cpp’s own timings, counting every reply (including replies from runs we repeated after a dropped connection). It leaves out the time spent reading the prompt.
- The Mac runs are from our MacBook Pro M4 Pro 24 GB: llama-bench speeds on November 3, 2026 (llama.cpp 0.6.0), and a board run of Qwen3 8B on November 14, 2026, scored on the Lucy.
What we don’t know yet
- Board scores and speeds on a 24GB card. Not measured yet.
- Speeds on other 24GB Macs. Ours is an M4 Pro; other chips will differ.
- Whether bigger Qwen3.8 27B files (4-bit and up) score higher than the 2-bit and 3-bit files we scored.
- Image generation at 24 GB. Not measured, so no pick.
Not sure how much memory you have, or using a different chip? The Kingy Local AI checker asks for your machine and shows which of 50 popular models fit, with our measured speeds where we have them.
Sources
- Kingy local AI board v0.2 and Kingy speed tests, checked 2026-11-15: Kingy’s board v0.2 scores and speed tests behind this page (method above).
- Kingy Lab: Local AI Models Tested, checked 2026-11-15: Kingy Lab’s 120-task test of 8 open models on the Lucy, November 7 to 12, 2026 (writing, everyday and coding scores).
- Kingy measured: 24GB MacBook Pro test, Nov 3 2026, checked 2026-11-15: Kingy’s own speed and quality test on a 24GB MacBook Pro (M4 Pro), November 3, 2026.
- Kingy Can You Run It hub, checked 2026-11-15: Kingy’s Can You Run It hub: Qwen3.8 27B measured on a 24GB card, August 17, 2026.
- Kingy Local AI checker, checked 2026-11-15: The fit rule used on this page (Kingy verdict standard v0.1).
- huggingface.co, checked 2026-11-15: Qwen’s Qwen3 4B files and sizes on Hugging Face.
- huggingface.co, checked 2026-11-15: Qwen’s Qwen3 8B files and sizes on Hugging Face.
- huggingface.co, checked 2026-11-15: Unsloth’s Qwen3.8 27B files at the revision we scored (August 20, 2026).
- huggingface.co, checked 2026-11-15: Unsloth’s Qwen3.8 27B file history: many files, including both we scored, replaced November 10 to 12.
- huggingface.co, checked 2026-11-15: Gemma 4 26B A4B files and sizes (LM Studio Community).
- huggingface.co, checked 2026-11-15: Gemma 4 31B files and sizes (LM Studio Community).
- huggingface.co, checked 2026-11-15: Gemma 4 31B settings file, used for the context-memory figure.
- ollama.com, checked 2026-11-15: Ollama’s Qwen3.6 tags; the 35b tag is the file we scored.
- huggingface.co, checked 2026-11-15: Qwen3.6 35B A3B settings file, used for the context-memory figure.
- lmstudio.ai, checked 2026-11-15: LM Studio’s guide to downloading a model.
- github.com, checked 2026-11-15: llama.cpp install guide.
- github.com, checked 2026-11-15: llama.cpp server options (-hf, -m, -c).
- github.com, checked 2026-11-15: Apple’s MLX-LM project.
- ollama.com, checked 2026-11-15: Ollama download page.
Revision log
- November 15, 2026: First published. Picks from Kingy board v0.2 (November 14 to 15), Kingy Lab (November 7 to 12) and Kingy Mac measurements (November 3 and 14).