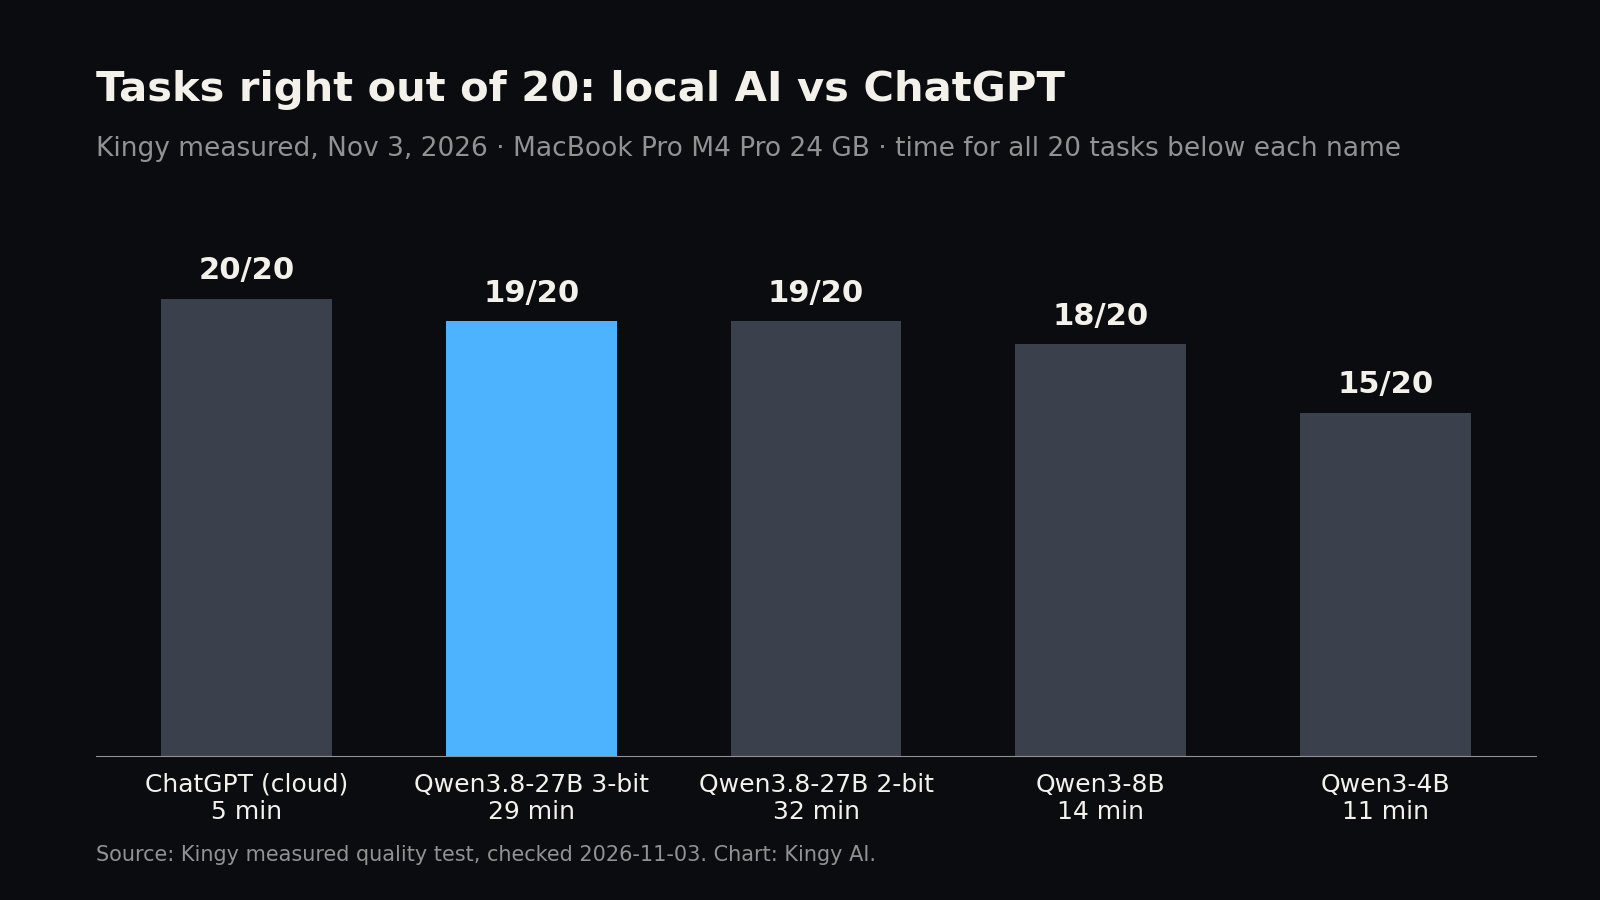
Short answer: on our own 24 GB MacBook Pro, free AI models running offline did nearly as well as ChatGPT on 20 graded tasks. ChatGPT scored 20/20. Qwen3.8-27B scored 19/20, Qwen3-8B 18/20 and the small Qwen3-4B 15/20. Everyday jobs were a tie. The real gaps were writing working code and speed: ChatGPT finished all 20 tasks in 5 minutes, and the 27B model took about half an hour. All numbers here are Kingy measured, on one Mac, on Nov 3, 2026.
We wanted a plain answer to a question people ask a lot: if you already own a decent Mac laptop, can a free local model stand in for ChatGPT? Benchmarks published by model makers don’t answer that, because they don’t use your machine or your kind of work. So we ran our own test, on our own laptop, with tasks that have one right answer a script can check.
What Kingy tested
- The Mac: a MacBook Pro with an Apple M4 Pro chip and 24 GB of memory, running macOS 26.3. macOS lets the graphics chip use about 19 GB of that for AI models.
- The local models: four files from Hugging Face, each checked against its published fingerprint (SHA-256): Qwen3-4B (2.50 GB), Qwen3-8B (5.03 GB), and two compressed versions of Qwen3.8-27B: a 3-bit file (UD-Q3_K_XL, 13.15 GB) and a 2-bit file (UD-IQ2_S, 8.37 GB).
- The program that ran them: llama.cpp version 0.6.0, installed with Homebrew, using the Mac’s graphics chip. The local models ran entirely on the Mac.
- The cloud side: ChatGPT’s gpt-6.1-sol model at medium thinking, run through OpenAI’s Codex CLI signed in with a ChatGPT plan.
The scores
Ten everyday tasks and ten harder ones. A script graded every answer against a single right answer worked out by code, so no one’s opinion decided a score.
| Model | Runs on | Everyday (10) | Hard (10) | Total | Time for all 20 |
|---|---|---|---|---|---|
| ChatGPT, gpt-6.1-sol | Cloud | 10 | 10 | 20/20 | 5 min |
| Qwen3.8-27B, 3-bit | This Mac | 10 | 9 | 19/20 | 29 min |
| Qwen3.8-27B, 2-bit | This Mac | 10 | 9 | 19/20 | 32 min |
| Qwen3-8B | This Mac | 10 | 8 | 18/20 | 14 min |
| Qwen3-4B | This Mac | 9 | 6 | 15/20 | 11 min |
Kingy measured, Nov 3, 2026. One run per task.
Where the local models were as good
The everyday set was pulling details from an invoice email, turning meeting notes into to-dos (with a cancelled item as a trap), rewriting a notice in plain words, fixing a short Python bug, budget sums, sorting customer messages, reading a sales table, answering from a 2,000-word handbook, writing an email that follows exact rules, and working out a date. The 8B and both 27B files got all ten right, the same as ChatGPT.
Where they fell short
- Writing code from scratch. One hard task asked for a small parser checked by 14 hidden tests. ChatGPT passed all 14. No local model passed: the 27B 3-bit came closest with 13, the 8B passed 11, the 27B 2-bit passed 10, and the 4B never produced the code.
- Following format rules. The smaller models often had the right number but skipped a required “ANSWER:” line, or ignored “use bullet points”. That matters if you paste their output into a spreadsheet or another tool.
- The 4B on harder work. It added up a messy spreadsheet wrong and sorted one name out of order. Fine for quick jobs, not for anything you won’t check.
How fast it is on this Mac
Speed is counted in tokens per second. A token is a piece of a word.
| Model file | Writes a reply | Writes a reply, 8K already in the chat | Waits before replying to an 8K prompt |
|---|---|---|---|
| Qwen3-4B (2.50 GB) | 68.3 tok/s | 47.5 tok/s | about 11 to 19 s |
| Qwen3-8B (5.03 GB) | 39.5 tok/s | 33.2 tok/s | about 20 to 28 s |
| Qwen3.8-27B 2-bit (8.37 GB) | 14.4 tok/s | 13.8 tok/s | about 66 to 71 s |
| Qwen3.8-27B 3-bit (13.15 GB) | 13.3 tok/s | 12.8 tok/s | about 67 to 72 s |
Kingy measured, Nov 3, 2026, plugged in, with llama.cpp’s own speed tool (llama-bench), three runs each. “8K” means 8,192 tokens, the length of a document several thousand words long. The wait is 8,192 tokens divided by how fast each model read the prompt.
We ran the speed test twice that day. The first run, that morning, was on battery with many apps open. The second, that evening, was plugged in with fewer apps open. The 27B numbers came out within about 2% of each other, so being on battery did not slow the big model. The 4B and 8B were about 11 to 13% faster in the morning run (76.7 and 45.3 tok/s). The likeliest reason is how busy the screen was, because drawing windows uses the same graphics chip. Expect your own numbers to move by around 10% depending on what else is running.
Speed is also why the quality test took so long. On most tasks the Qwen models think before they answer, and on the 27B that thinking runs at about 13 tokens a second. A typical single task took ChatGPT 13 to 15 seconds and the 27B about a minute or two. The slowest local answer took 4 minutes.
Which one should you use on a 24 GB Mac?
Can you run Qwen3-8B on a 24 GB MacBook Pro? Yes. MacBook Pro M4 Pro 24 GB · Qwen3-8B Q4_K_M · llama.cpp 0.6.0 · 33.2 tok/s at 8K context · Kingy measured Nov 3, 2026
Can you run Qwen3.8-27B on a 24 GB MacBook Pro? Yes, but slow. MacBook Pro M4 Pro 24 GB · UD-Q3_K_XL · llama.cpp 0.6.0 · 12.8 tok/s at 8K context, about 70 s before it starts on an 8K prompt · Kingy measured Nov 3, 2026
Can you run Qwen3-4B on a 24 GB MacBook Pro? Yes. MacBook Pro M4 Pro 24 GB · Qwen3-4B Q4_K_M · llama.cpp 0.6.0 · 47.5 tok/s at 8K context · Kingy measured Nov 3, 2026
- For everyday writing, sorting and reading jobs, Qwen3-8B is the sweet spot here. It matched ChatGPT on all ten everyday tasks, replies faster than you can read, and leaves room for your other apps.
- For harder reasoning, the 27B is a little better but much slower. The 2-bit file scored the same as the 3-bit one in our test and is about 5 GB smaller, though its code was weaker (10 tests passed against 13).
- For code you need to work first time, the cloud model still won in our test.
- Bigger 27B files: by our memory formula, the 16.46 GB 4-bit file (UD-Q4_K_M) should just fit under the Mac’s roughly 19 GB limit, but we did not try it, because with normal apps open it would leave almost nothing spare. Not tested by Kingy.
For other machines, see the Can You Run It at Home hub. For which Qwen3.8-27B file to download, see our Qwen3.8-27B GGUF guide and hardware requirements. This is the same laptop model we used for our 24 GB Mac fit test in August.
How we tested, and what we changed
All task texts were written for this test, and each answer was worked out by code, not typed in by hand. Before any model ran, we checked the grader against an answer key and against planted wrong answers. That caught two typos in the answer key and a quoting bug in the code tests, all fixed before the test.
Three grading rules were loosened after we saw the answers. Each change applied to every model, and we’re listing them because they changed the totals:
- A task was due “before Nov 9”, so Nov 8 is now accepted as well as Nov 9. This helped ChatGPT and both 27B files.
- On the long handbook task, “2 days” is now accepted as well as “2”, as the shorter handbook task already allowed. This helped ChatGPT.
- Our contradiction task was flawed: three statements only clash as a group, so any pair of them is now accepted. This helped the 27B 3-bit.
Under the original strict rules, the totals would have been ChatGPT 18, Qwen3.8-27B 2-bit 18, Qwen3-8B 18, Qwen3.8-27B 3-bit 17 and Qwen3-4B 15. So ChatGPT’s one-point lead depends on how strictly answer formats are graded. Its clear wins are the code task and speed.
Local settings: temperature 0.6, top-p 0.95, top-k 20, a fixed seed, thinking capped at 2,048 tokens. The quality test ran with other apps open; the everyday set ran on battery and the hard set plugged in. Our external drive disconnected once during the hard set, so two runs were restarted from scratch after their files were re-checked.
Limits of this test
- One machine. Everything here is one MacBook Pro M4 Pro with 24 GB. A 16 GB Mac, a gaming PC or a bigger Mac will give different speeds, and may fit different files.
- A small sample. Twenty tasks, one run each. Treat a one-point gap as noise.
- Not quite the ChatGPT app. Codex wraps the model in its own coding-assistant instructions, so this is close to, but not the same as, chatting in the ChatGPT app. On the time-zone task, ChatGPT searched the web and ran a command before answering. The local models answered from memory and also got it right.
- Quality and speed only. We did not score privacy, cost or working offline, which are the main reasons people run AI at home.
- Versions move. Homebrew’s current llama.cpp is 0.8.0. We used 0.6.0 for both tests so the numbers stay comparable.
What’s next
We plan to run the same tasks and speed test on an RTX 5070 gaming laptop and on a Ryzen AI Max+ 395 computer with 128 GB, and add them to this page as dated updates.
Sources
- Kingy measured: speed tests (Nov 3, 2026, on battery and plugged in) and the 20-task quality test (Nov 3, 2026), as described in How we tested
- Qwen/Qwen3-4B-GGUF on Hugging Face, file size and fingerprint, checked Nov 3, 2026
- Qwen/Qwen3-8B-GGUF on Hugging Face, file size and fingerprint, checked Nov 3, 2026
- unsloth/Qwen3.8-27B-GGUF on Hugging Face, file sizes and fingerprints, checked Nov 3, 2026
- llama.cpp on GitHub, checked Nov 3, 2026
- Homebrew llama.cpp package, install route and current version, checked Nov 3, 2026
- OpenAI Codex CLI, sign-in with ChatGPT, checked Nov 3, 2026
Revision log
- Nov 3, 2026: first published.
The Kingy Brief
Get the free AI price sheet.
25 AI plans and models on one page, from official pricing pages, updated every month. Free when you join The Kingy Brief: AI changes, original tests and one practical thing to try, Fridays at 09:00 Vancouver time.
Free · Double opt-in · Unsubscribe anytime
Sign up for The Kingy Brief on Beehiiv.
Signup help and newsletter schedule
Signup form provided by Beehiiv. After submitting, check your inbox for "Confirm your subscription to The Kingy Brief" and open its confirmation link. Your price sheet download is on the page that opens. Check Spam or Promotions if you cannot find it.
Fridays at 09:00 Vancouver time: source-checked AI changes, original tests and one practical thing to try. We skip a week when there is not enough verified material. Free. Unsubscribe anytime.