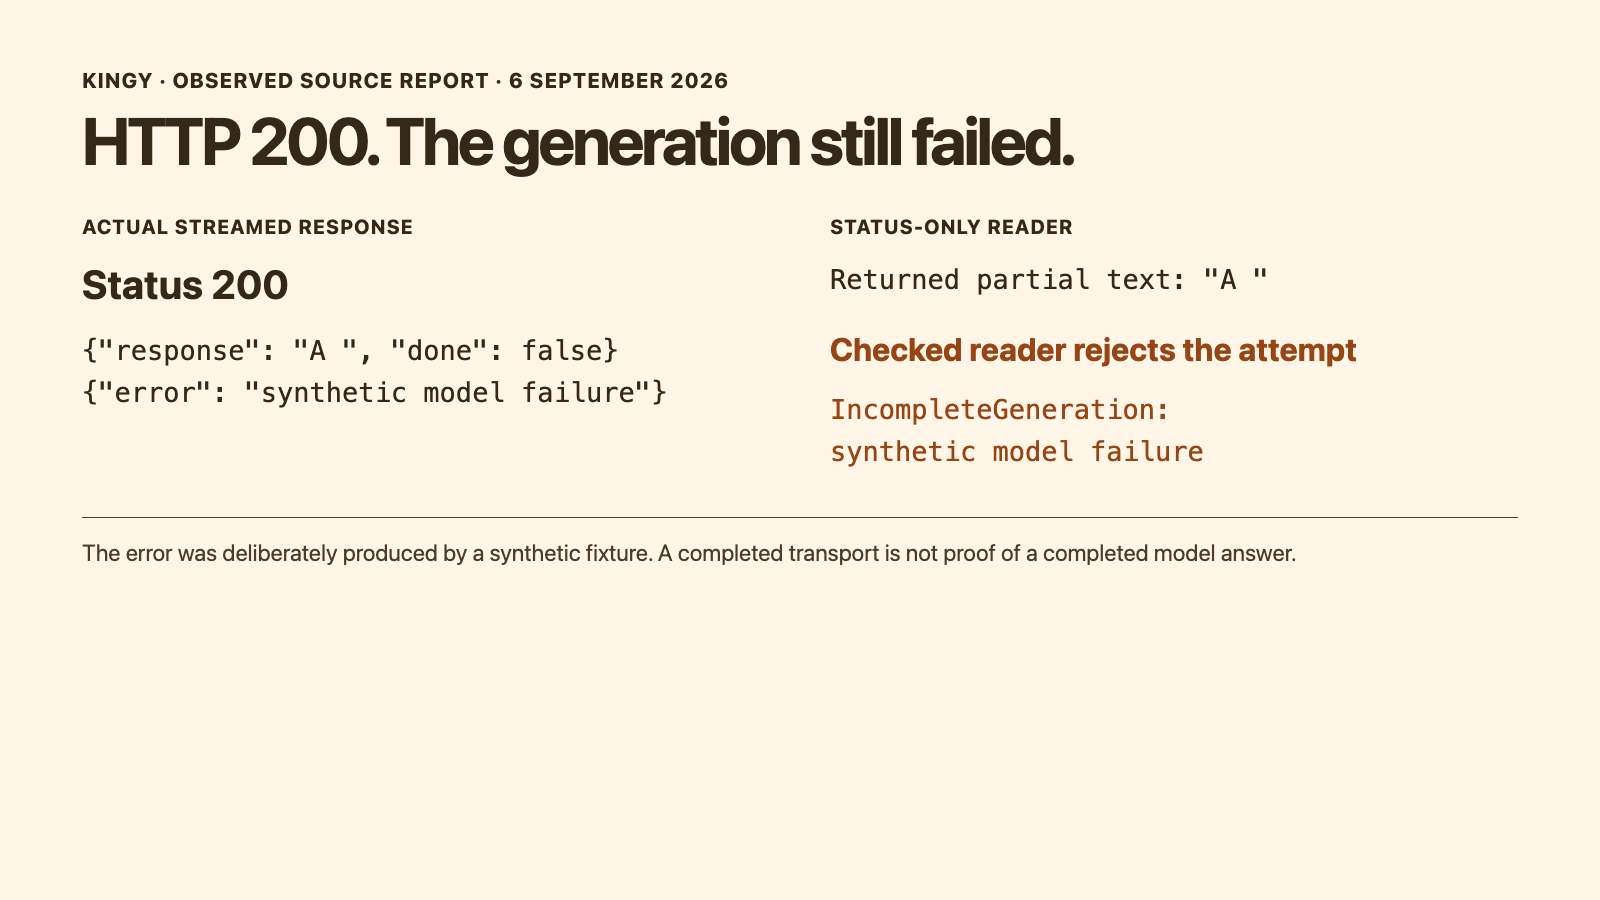
A successful HTTP status does not establish that a streamed generation finished. Check the events inside the response and require the completion marker before treating the answer as complete.
Kingy test scope: On September 6, 2026, our Python 3.14.0 client test used a synthetic loopback server to return HTTP 200 followed by a deliberate error event. We also tested a stream ending without a completion marker. No real model failure, GPU issue, Ollama release, or inference success rate was measured.
Why status-only checks miss it
Ollama documents that errors during streaming arrive as NDJSON objects with an error property. Once streaming starts, the response status is not changed. That means an application which checks only HTTP 200 can miss a later failure. Official error reference
Our deliberately incomplete fixture sent one text fragment followed by an error. This naive reader returned A and discarded the error event:
answer = "".join(
    json.loads(line).get("response", "")
    for line in response
)
The fixture’s HTTP status was 200 throughout. That reproduced the client bug: a partial answer was available with no failure surfaced to its caller.
The tested fix
The downloadable client lab provides read_native_generate. It processes each native generate event in order and:
- Raises
IncompleteGenerationif an event contains an error. - Requires
done: truebefore returning the collected answer. - Raises
IncompleteGenerationif the response ends before completion.
from ollama_client_lab import read_native_generate, IncompleteGeneration

try:
    answer = read_native_generate(response)
except IncompleteGeneration as exc:
    # Mark this attempt failed; do not publish a partial answer.
    print("Generation incomplete:", exc)
In the recorded test, the fixed reader rejected both the deliberate error and the missing-completion case. The same reader accepted the complete fixture in the Extra data test. Recorded results
Reproduce without running a model
Save the lab script locally and run:
python3 ollama_client_lab.pyThe script binds a temporary local port, performs nine synthetic requests, writes no model files, and closes its server. Look for http-200-incomplete with pass: true. This is a protocol-level client test, not a model benchmark.
Recovery and limits
Keep the attempt in a failed state and inspect the actual error before deciding whether to retry. Preserve only the diagnostic data you need. If you display partial text while streaming, label it incomplete on failure. Do not feed it into a downstream publishing or file-writing step as a finished answer.
This fix detects failure; it does not solve the underlying cause. A timeout, proxy disconnection, model loading problem, or user cancellation may need different handling. A completion marker also does not prove factual correctness or that the model satisfied the request. Tool-call responses and OpenAI-compatible event streams need their own readers.
Related: Fix Extra data · Match endpoint and response shape. Kingy Local Lab can help estimate memory fit before a separate real-model test.
Keep the test in context
These are client-protocol examples. For hardware fit estimates, use Local Lab; for the related setup walkthrough, read Kingy’s OpenClaw and UGREEN guide.