Buying guide reviewed October 22, 2026. New task observations: October 22. Launch benchmarks and older case studies retain their original dates.
Start with GPT-6.1 Sol for repeatable work you can check. Try GPT-6 Astra when Sol makes consequential mistakes, needs repeated corrections or leaves enough review work to justify the higher price.
Our October 22 checks covered three procurement tasks. Both models passed every predefined check. That gives us no quality-based reason to pay more for Astra on those particular tasks; it does not establish that the models perform equally on harder work.
Already getting reliable results from Astra? Compare Sol on representative tasks before switching. Count failed attempts and review time alongside token costs.
What Kingy checked
Three procurement tasks checked; production workflows remain untested.
On October 22, 2026, we ran three identical synthetic procurement tasks once per requested model in Codex CLI, using Medium reasoning effort. Both models passed all three predefined checks.
The tasks covered quote comparison, annual seat costs and an upgrade’s break-even calculation. These cases did not demonstrate a quality advantage that justified Astra’s higher API price.
Limits: This was six responses, with no model tool calls. We did not test repository work, difficult science, visual judgment, long-context recall or production workflows. Human review time and actual API charges were not measured. Recorded CLI times are individual observations, not a reliable speed ranking.
| Task checked | Sol result | Astra result | What it supports |
|---|---|---|---|
| Compare quotes, calculate totals and flag missing currency conversion | Passed | Passed | Both met the checks for this example. |
| Calculate annual seat costs across nine cases | Passed | Passed | Both produced the required allocations and totals. |
| Calculate an upgrade’s break-even point without inventing guaranteed savings | Passed | Passed | Both met the calculation and explanation checks. |
No correction calls were needed under these checks. Human review time was not measured, and these examples do not establish which model produces better results across other tasks.
Full task records, prompts, responses, timing and methodology
On October 22, we requested gpt-6-astra and gpt-6.1-sol at Medium effort in Codex CLI 0.163.0-alpha.10.2. Each task used an identical user prompt, a fresh ephemeral session and no model tool calls. Model order alternated across tasks. These were existing included-subscription sessions, without API keys. The CLI records the requested model and usage; its JSON does not independently attest the backend snapshot. Model-specific harness context and cache counts differed.
Both models passed all three predefined task checks and all six outputs were raw JSON. The useful finding is narrow: these structured procurement tasks did not demonstrate a quality reason to pay Astra’s premium. They do not test difficult science, repository work, visual judgment, long-context recall or production tool use.
Exact quote-comparison input
Do not use tools, files, browsing, or external information. Return the requested JSON only.

You are checking synthetic supplier quotes for a four-seat team buying 12 months of service. Use only these rows. Q1: A costs USD18 per seat per month, paid monthly, plus a one-time USD40 setup fee. Q2: B costs USD16 per seat per month, billed for all 12 months upfront, plus a one-time USD100 setup fee. Q3: C costs EUR15 per seat per month, no setup fee; no EUR/USD exchange rate is supplied. Ignore tax for every quote. Total first-year budget is USD900; upfront cash is not separately constrained. Return only a JSON object with eligible_totals_usd (object keyed A and B), recommendation (supplier letter), excluded (object keyed by supplier with the missing information), and source_rows (object mapping A/B/C to the source row IDs). Calculate first-year totals, recommend the cheapest qualifying USD quote, and do not invent currency conversion.
The reference totals are A: 4 × 12 × $18 + $40 = $904; B: 4 × 12 × $16 + $100 = $868. Only B meets the $900 budget. C totals €720, but no exchange rate was supplied, so a USD comparison is unsupported.
Sol 6.1: exact recorded quote answer
{
  "eligible_totals_usd": {
    "A": 904,
    "B": 868
  },
  "recommendation": "B",
  "excluded": {
    "C": "Missing EUR/USD exchange rate."
  },
  "source_rows": {
    "A": "Q1",
    "B": "Q2",
    "C": "Q3"
  }
}
Astra: exact recorded quote answer
{
  "eligible_totals_usd": {
    "A": 904,
    "B": 868
  },
  "recommendation": "B",
  "excluded": {
    "C": "EUR/USD exchange rate not supplied."
  },
  "source_rows": {
    "A": "Q1",
    "B": "Q2",
    "C": "Q3"
  }
}| Task and acceptance check | Sol 6.1 Medium | Astra Medium |
|---|---|---|
| Quote normalization: correct totals, choose B, exclude missing exchange rate, map source rows | Passed. 8.46s CLI elapsed. | Passed. 8.50s CLI elapsed. |
| Annual seats: all nine rows correct; k=3, $492 upfront, $972 first-year total | Passed. 35.85s CLI elapsed. | Passed. 23.58s CLI elapsed. |
| Upgrade: $300 premium, 5-hour break-even; no guaranteed saving or exact task capacity inferred | Passed. 12.59s CLI elapsed. | Passed. 9.62s CLI elapsed. |
| Observed failures and repair calls | No failures under this rubric; zero correction calls. | No failures under this rubric; zero correction calls. |
| Human correction time / actual API charge | Not measured / no per-run API invoice. | Not measured / no per-run API invoice. |
Elapsed times include CLI startup, client overhead and service variation. There was one observation per task/model, so these are not stable latency estimates. Astra finished the seat task sooner in this run, while the quote timings were nearly equal. We do not convert these timings into an Ultrafast claim or a general speed ranking.
The validator independently recomputed the quote totals and all nine seat allocations, checked the selected option, verified the break-even arithmetic and parsed each answer as raw JSON. We also read the missing-information and ROI explanations. No repairs were needed under that rubric; human review time was not measured. Token usage includes CLI context and is retained as reported, without turning it into an invented API invoice.
Download all six exact inputs and outputs, timestamps, reported token usage and checks (JSON). The synthetic prompts and responses are public; private account details and session identifiers are excluded.
Choose by task; switch when these checks fail
These are editorial starting rules based on the cited evidence. Our three procurement checks do not validate these recommendations across other task types.
Repeated coding and document work
Difficult science and costly ambiguity
Polished client deliverables
Long, repeated context
Set the acceptance criteria before the trial. A practical first policy is one attempt and one targeted correction, then Astra or human review if the check still fails. Include every attempt in the cost. That retry limit is an editorial starting rule, not a measured optimum.
Compare the cost of an accepted result
The dollar examples in this section are calculations from stated assumptions, not measured API charges from our October 22 task checks. Include failed attempts and review time when comparing the cost of an accepted result.
API pricing in detail
All prices in this table are Standard API USD per million tokens. The threshold uses the request's input length.
| Token category | Astra, input ≤272K | Sol 6.1, input ≤272K | Astra, input >272K | Sol 6.1, input >272K |
|---|---|---|---|---|
| Ordinary uncached input | $10.00 | $2.00 | $20.00 | $4.00 |
| Cached input reads | $1.00 | $0.10 | $2.00 | $0.20 |
| Cache writes, 30 minutes (default) | $12.50 | $2.50 | $25.00 | $5.00 |
| Cache writes, 12 hours (Responses API) | $25.00 | $5.00 | $50.00 | $10.00 |
| Output, including reasoning | $50.00 | $10.00 | $75.00 | $15.00 |
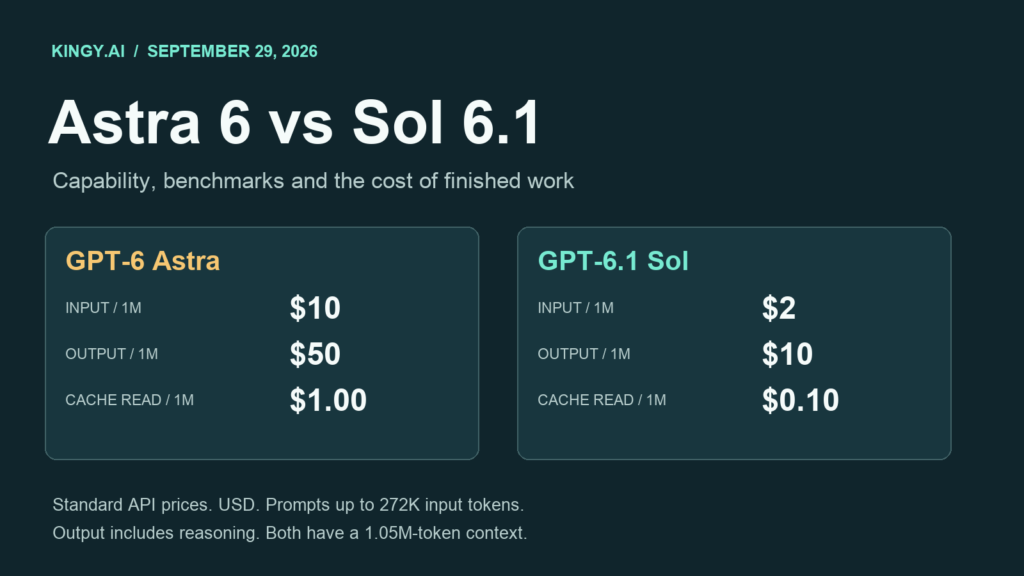
The official pricing table specifies higher rates for the full request once input exceeds 272,000 tokens. That is a pricing threshold, well below either model's maximum context. Astra's uncached input, output and cache-write rates are five times Sol's. Cached reads cost ten times as much.
Crossing the threshold can create a sharp change. With 272,000 ordinary input tokens and 10,000 billable output tokens, the hypothetical Standard bill is $3.22 for Astra or $0.644 for Sol. At 272,001 input tokens, it becomes approximately $6.19002 or $1.238004. The higher rate covers all input and output, rather than only the final token above the threshold.
This is a reason to retrieve relevant material carefully and measure the actual input count. Cutting a prompt down to fit the cheaper band is useful only if the removed context does not invalidate the result.
Batch, Flex, Fast and regional processing
| Processing choice | Astra | Sol 6.1 | Operational consideration |
|---|---|---|---|
| Standard | Base rates | Base rates | Interactive baseline |
| Batch | 50% of Standard | 50% of Standard | Asynchronous jobs with a 24-hour completion window |
| Flex | 50% of Standard | 50% of Standard | Slower processing; resources can be unavailable |
| Fast | 2× Standard | 2× Standard | Higher serving speed; measure complete task time |
| Ultrafast API | 6× Standard | 6× Standard; short-context $12 input / $60 output per million tokens | Both models are broadly available in the API with separate rate limits; model-specific residency applies |
| Regional processing | 10% premium where applicable | 10% premium where applicable | Check the eligible model and endpoint |
Sources: API rates, Batch, Flex, and Ultrafast.
An overnight document classification job may suit Batch. A workflow that someone is waiting to review may justify Fast. A real-time desktop task still spends time on network requests, browser loading and application interactions. A processing multiplier describes billing; it does not promise the same multiplier for end-to-end speed.
Worked request costs: identical token budgets
The following scenarios are calculations, not measured token consumption for those jobs. Each row represents one request, with every input token billed at the ordinary uncached rate. Output includes visible text and all reasoning tokens. We assume explicit-only caching with no breakpoints, so there are no cache-write charges. Tools, retries, infrastructure, tax and regional premiums are excluded.
| Illustrative request | Input / all billable output | Astra Standard | Sol Standard | Astra Fast | Sol Fast |
|---|---|---|---|---|---|
| Short summary | 5,000 / 1,000 | $0.10 | $0.02 | $0.20 | $0.04 |
| Document analysis | 25,000 / 5,000 | $0.50 | $0.10 | $1.00 | $0.20 |
| Code review | 100,000 / 10,000 | $1.50 | $0.30 | $3.00 | $0.60 |
| Request with extensive reasoning | 100,000 / 50,000 | $3.50 | $0.70 | $7.00 | $1.40 |
| Near the cheaper input ceiling | 250,000 / 20,000 | $3.50 | $0.70 | $7.00 | $1.40 |
| Large document bundle, long rates | 500,000 / 20,000 | $11.50 | $2.30 | $23.00 | $4.60 |
Compare costs for your workload.
For short-context Standard requests without cache writes, the formulas are:
Astra = (input × 10 + billable output × 50) / 1,000,000
Sol 6.1 = (input × 2 + billable output × 10) / 1,000,000
At equal token usage in these uncached scenarios, Sol saves 80%. For 1,000 requests matching the code-review row, the token bills would be $1,500 and $300. For the 500K-input row, the correct rates are $20/$75 for Astra and $4/$15 for Sol, producing $11.50 and $2.30.
Equal token budgets isolate the price difference. Actual model runs may use different budgets, which explains why benchmark cost ratios differ from exactly five to one.
Open 100 code-review-sized calls in the calculator: $30 Sol or $150 Astra. The setup has 100K input and 10K billable output per call, Standard rates, no cache writes or tool fees, and no assumed acceptance rate. It is a budget example, not the measured usage of the six task observations.
Hidden reasoning can outweigh the visible answer
Suppose a request contains 5,000 input tokens, returns 1,000 visible answer tokens, and uses 10,000 reasoning tokens. The billable output is 11,000. Astra's Standard bill is $0.60, and Sol's is $0.12. Counting only the visible answer would produce misleading estimates of $0.10 and $0.02.
The reasoning-token documentation explains that reasoning consumes context and is billed as output. An output-token budget also has to leave room for reasoning. A model that exhausts its allocation before finishing an answer can incur a bill without delivering the result you wanted.
Caching: the tenfold rate difference
Caching matters most when an application repeatedly supplies the same stable material. Imagine ten requests sharing a 100,000-token prefix, each adding 2,000 new input tokens and generating 2,000 billable output tokens.
For this calculation, explicit-only caching uses the default 30-minute lifetime and places a breakpoint after the stable prefix. The first request writes that prefix, the following nine obtain full hits, and the changing suffix is billed as ordinary input without being written to cache. All requests stay in the cheaper input band.
| Ten-request cache scenario | Astra | Sol 6.1 |
|---|---|---|
| First request: prefix write + fresh input + output | $1.370 | $0.274 |
| Each of nine subsequent requests: prefix read + fresh input + output | $0.220 | $0.034 |
| Ten-request total with these cache assumptions | $3.350 | $0.580 |
| Ten requests with all input ordinary uncached and no writes | $11.200 | $2.240 |
| Saving within each model versus that uncached baseline | 70.1% | 74.1% |
Sol is about 82.7% cheaper than Astra in this complete cache example. Its cached-read component costs one-tenth as much, but the write, fresh input and output components still have their own rates. A tenfold saving on one token category does not mean a tenfold saving on the entire session.
The first Astra request is $1.25 for the prefix write, $0.02 for fresh input and $0.10 for output. A later hit is $0.10 + $0.02 + $0.10. For Sol, those figures are $0.25 + $0.004 + $0.02 initially and $0.01 + $0.004 + $0.02 on a hit.
Cache-pricing correction, October 20, 2026: The Responses API also supports a 12-hour minimum cache lifetime at twice the default 30-minute write price. Set prompt_cache_options.ttl to "12h" to select it; cache-read prices stay the same. Extending valid 30-minute coverage to 12 hours incurs a new 12-hour write charge for those tokens, without credit for the earlier write. A read using 30-minute retention does not restart an existing 12-hour clock. These are minimum billing lifetimes, not guaranteed latency improvements or deletion deadlines. OpenAI cache lifetime and billing rules.
Cache writes replace the ordinary input rate for written tokens; do not add both rates to the same token. The prompt-caching guide documents prefix matching, explicit controls, lifetime and reported usage. Its default implicit breakpoint behavior is a reason to check real write and hit counts instead of assuming every uncached request uses the lowest ordinary rate.
A changing instruction at the front of a long prompt can defeat reuse. Keep stable context stable where the API permits it, and record misses. Tool results, retrieved documents, image inputs and conversation growth can alter the bill. A cache saving projected from ten perfect hits should be checked against actual traffic before becoming a budget.
From a request to a complete agent task
An agent job often contains many model requests. Ten browser actions may create ten rounds of reasoning and new tool results. A repository task may add searches, test runs, retries and parallel agents. The task total must include every request required to finish the job.
Consider an illustrative ten-request task. Each request uses 20,000 ordinary input tokens and 3,000 billable output tokens, with no cache writes. Across the job, the totals are 200,000 input and 30,000 output tokens. Each individual request stays below the long-context threshold. The Standard model charges are $3.50 for Astra and $0.70 for Sol.
Now add three web searches, two Responses file-search calls, and one 1GB hosted-shell or code-interpreter container session lasting up to 20 minutes. The listed service fees add $0.065: $0.03 for searches, $0.005 for file-search calls and $0.03 for the container. Assume any search-content tokens are already included in our input totals. The resulting illustrative bills are $3.565 and $0.765, before storage and other excluded costs. OpenAI's tool pricing gives the separate charges.
As identical non-model fees grow, the total saving becomes smaller than the token-only saving. If an external data service or application charges per operation, include that too. Spending on subagents belongs to the parent task even when delegation reduces elapsed time.
The long-context premium applies to each request's input, not the sum of token counts across a whole job. Ten 50K-input requests do not automatically become one 500K-input request. Conversely, a late step containing an accumulated 300K-token history can enter the higher band even if earlier steps were inexpensive.
Cost per accepted result, retries and escalation
Three different measurements are useful: the price of an attempt, the total spending on a job, and the cost of an accepted result. Only the last tells you how much you spent to obtain usable output.
For a real evaluation, calculate:
API cost per accepted result = spending on all attempts / number of accepted results
Define acceptance before seeing model outputs. For a patch, that might mean the relevant tests pass, the issue is resolved and review finds no material regression. For a document, it might mean every required section is present and factual claims match the supplied evidence.
Suppose 100 Sol attempts cost $0.30 each and 80 pass. Their API cost per accepted result is $0.375. If 100 Astra attempts cost $1.50 each and 95 pass, the figure is about $1.579. These invented rates illustrate the calculation; they are not measurements of either model.
A two-stage workflow offers another possibility. Run Sol first, then send unresolved cases to Astra. With a $0.30 Sol attempt, a $1.50 Astra fallback and a hypothetical 20% escalation rate, expected token spending is $0.60 per initial job. That remains below $1.50 for sending every job straight to Astra. It also introduces extra waiting and requires a detector that reliably identifies the cases needing escalation.
Under those prices, the simple break-even escalation rate is 80%, because $0.30 + 0.80 × $1.50 = $1.50. Real fallback requests may have larger histories or reuse earlier work, changing the calculation. An unreliable quality check can silently accept a bad Sol answer, so escalation economics depend on the check as well as the model.
Human time can reverse a token-price decision. At an illustrative $60/hour, five additional minutes of correction cost $5. A model that saves $1.20 in API charges but creates that repair work is more expensive in total. Track correction time alongside the API bill, especially for outputs intended for clients or external publication.
Price the same workload before switching
Open a 100-call example with 100,000 input and 10,000 billable output tokens per call: $30 for Sol 6.1 or $150 for Astra at Standard rates. This is a calculated API budget, separate from our subscription-based task observations.
Open the $30 Sol / $150 Astra example
Our October 22 task checks used both exact model names. The older app and spreadsheet cases used GPT-5.6 Sol. Calculator results are estimates, not subscription allowances.
Use the comparison checklist below to record failures, all attempts and review time. Calculator estimates cannot predict success rates or subscription allowances.
Next: Compare plans · Estimate API costs
What benchmarks add to this decision
This historical September 29 launch table uses matching effort labels from the interactive charts in OpenAI's Sol 6.1 launch report. Costs are the displayed average API cost per benchmark task. They are vendor estimates for those runs, rather than invoices for your workload.
| Evaluation and effort | Astra score | Sol 6.1 score | Astra cost/task | Sol 6.1 cost/task |
|---|---|---|---|---|
| DeepSWE 1.1, High | 73.2% | 75.2% | $3.92 | $0.65 |
| GDP.pdf, High | 31.0% | 32.0% | $1.79 | $0.35 |
| AutomationBench 1.0.6, Medium | 34.1% | 31.7% | $1.27 | $0.19 |
| AutomationBench 1.0.6, Max | 41.4% | 36.1% | $1.73 | $0.30 |
| OSWorld 2.0 offline, High | 70.0% | 69.6% | $6.91 | $0.96 |
| OSWorld 2.0 offline, Max | 73.5% | 71.4% | $9.44 | $1.27 |
| Terminal-Bench Science 0.1, Max | 68.1% | 57.0% | $23.80 | $5.47 |
| Factual error rate on difficult prompts, Low | 6.3% | 7.7% | $0.24 | $0.05 |
| Factual error rate on difficult prompts, Max | 3.9% | 4.6% | $0.79 | $0.13 |
DeepSWE covers repository engineering, GDP.pdf professional PDF work, AutomationBench business workflows, and Terminal-Bench Science scientific work using code and terminals. OSWorld 2.0 distinguishes partial reward from full completion. This comparison uses its offline v2026.08.08 partial reward. Higher is better except for factual error rates, where lower is better. Costs displayed to cents make derived ratios approximate.
Several practical conclusions follow from the numbers, with different strength of evidence.
On the displayed High-effort DeepSWE point, Sol 6.1 scores two percentage points higher and costs about 83% less. On GDP.pdf at High, it scores one point higher at about 80% lower cost. Those rows make Sol worth testing for repeated engineering and document workflows. A small displayed score difference does not establish a statistically significant universal quality advantage.
On OSWorld at Max, Astra's score is 2.1 points higher, while Sol's attempt costs about 87% less. A desktop automation team should examine which individual tasks fail. A missed cosmetic step and an incorrect record update can carry very different consequences even if they contribute to the same aggregate reward.
AutomationBench favors Astra at both settings shown. At Max, the 5.3-point advantage costs an additional $1.43 per evaluated attempt. Sol is about 83% cheaper there. That makes the result useful for routing business workflows, but neither aggregate score supports assuming that every automation will finish correctly.
Science has a larger capability gap. Astra leads by 11.1 points, at a cost 4.35 times as high per attempt. Sol's 77% lower attempt cost can be attractive for broad exploration, but a demanding research task that repeatedly fails on Sol may justify Astra immediately. These figures support a workload-specific decision rather than treating near-Astra positioning as identical ability.
Higher effort does not always buy a better score
The plotted DeepSWE results illustrate why effort needs testing. Sol moves from 73.0% at Medium ($0.42) to 75.2% at High ($0.65), then falls to 71.9% at both Xhigh ($0.79) and Max ($1.57). Astra's highest displayed score is 74.1% at Xhigh ($4.43), compared with 73.2% at Max ($7.50).
These points do not prove that extra reasoning hurts every coding task. They do show that Max cannot be treated as a guaranteed quality upgrade. Sol High has the best displayed Sol result in this particular run, while costing less than half as much as Sol Max. The sensible setting is the one that meets your acceptance criteria on your workload.
Why launch numbers sometimes disagree
An older Astra result can differ from the Astra baseline used in the September 29 comparison. Benchmark version, effort, harness, tools and scoring matter. Compare the two models within one disclosed setup before combining numbers from separate launch pages. For example, Astra's September 3 launch reported 64.6% on Terminal-Bench Science; the paired September 29 chart uses 68.1%. This guide uses the later paired comparison consistently.
A leaderboard entry for Astra on a benchmark that has no published Sol 6.1 entry cannot establish the gap between them. We have not filled missing Sol rows with GPT-6 Sol, estimated scores, or unrelated tests. GPT-6 Sol and GPT-6.1 Sol are different versions.
Independent evidence: October 22 snapshot and October 28 AA update
| Evaluator and metric | Astra | Sol 6.1 |
|---|---|---|
| Historical Artificial Analysis Intelligence Index v4.3.2, Max, October 22 | 53; $3.26 per index task | 52; $0.72 per index task |
| Artificial Analysis displayed output throughput — checked October 22, 2026 | 56.5 tokens/s | 54.8 tokens/s |
| Vals Index v2.2, reported Max defaults | 65.02% ±1.10; $21.28/test | 63.94% ±1.07; $3.614/test |
| Vals displayed latency | 33m39s | 44m24s |
| Vals Terminal-Bench-Science result | 62.86% ±5.82 | 52.86% ±6.01 |
Speed snapshot clarification, October 22, 2026: An earlier capture that day reported 56.3 tokens/s for Astra and 54.2 for Sol. The refreshed figures are 56.5 and 54.8 respectively. These are dated output-throughput observations. They do not measure time to first token or time to an accepted result, and the change alone does not establish that either model became faster. Kingy has not run a new matched API speed test; the October 22 task observations retain their original dates.
Artificial Analysis v5.0, checked October 28, 2026: Astra Max reports 57 at $6.24 per weighted index task; Sol 6.1 Max reports 55 at $1.27. Astra’s displayed lead is two index points, while Sol’s weighted task cost is about 79.6% lower.
Version boundary: AA v5.0 changes the evaluations and their weights. Compare models within the same version; changes from v4.3.2 do not establish model improvement or regression. Weighted costs also incorporate typical cache-hit measurements. These sources do not isolate the contribution of each change. No new Kingy model test was performed.
Sources: Artificial Analysis’s Astra and Sol 6.1 pages; Vals Index and its Astra and Sol 6.1 pages. These are separate harnesses and metrics. Output throughput, evaluator task latency and our CLI elapsed time are different measurements.
Vals released v2.2 on October 19, changing Finance Agent, EMB, Code Migration, HLAB and Tax scoring; the index page was updated October 21. Earlier v2.1 scores must not be compared with this snapshot as proof of model improvement. Its displayed uncertainty also cautions against treating the 1.08-point aggregate gap as a decisive quality difference. Science remains a more informative reason to trial Astra than the small aggregate lead.
Earlier evaluator snapshot retained for context
The October 17 review cited the October 16 Vals v2.1 index at Astra 63.13%/$18.46 and Sol 61.15%/$3.24. Those are historical observations under the earlier index. Current figures above supersede them for today’s buying decision.
What the published evidence does not establish
The launch-chart rows above are OpenAI-reported, including tests on external benchmark suites. The independent observations in the separate section use their own harnesses. Our October 22 observations are a separate six-response synthetic-task check, not a replication of these benchmarks. Older Astra/GPT-5.6 Sol case studies do not measure Sol 6.1.
Aggregate scores do not reveal your exact failure distribution. They also do not include the cost of every possible production integration, human repair step or subscription plan. Treat them as evidence for choosing candidates, then evaluate the final workflow you plan to run.
Factuality and safety evaluations
The difficult factuality set selects conversations where users had previously flagged an error. OpenAI reports that Sol 6.1 remains within 1.9 percentage points of Astra across the tested efforts. This is an answer-level error measure on selected prompts, not the percentage of all facts either model gets wrong. See the launch methodology.
| Selected alignment evaluation | Astra | Sol 6.1 | Direction |
|---|---|---|---|
| Coding misrepresentation, effort not specified in the cited table | 0.51% | 1.50% | Lower is better |
| Unwanted persistence after warnings, Max, without system controls | 17.4% | 23.5% | Lower is better |
| Attempts to bypass the automated reviewer, Max | None observed | None observed | Finite test result |
The Sol system-card addendum treats both models as Critical for cybersecurity and High for biological/chemical capability, and applies Astra's safeguards to Sol. These are capability classifications. The adversarial evaluation rates are not ordinary production incident rates, and zero observed attempts does not guarantee zero future failures.
For a deployment, use permissions appropriate to the task and verify consequential results. Astra's advantage on some alignment tests can matter, while the table does not establish that every safety behavior is better on Astra.
Access and implementation details
The key differences at a glance
| Decision | GPT-6 Astra | GPT-6.1 Sol |
|---|---|---|
| Position | Highest capability in OpenAI's current GPT-6 lineup | Lower-cost option for complex work |
| Standard input / output, per million tokens | $10 / $50 | $2 / $10 |
| Cached input, per million tokens | $1 | $0.10 |
| API context window | 1,050,000 tokens | 1,050,000 tokens |
| Published comparison | Stronger scientific result and slightly higher computer-use ceiling | Close results on several work tasks at much lower benchmark cost |
| Reasoning effort | Low, Medium, High, Xhigh, Max | Low, Medium, High, Xhigh, Max |
| Speed options today | Standard, Fast, Ultrafast; product-specific conditions apply | Standard, Fast and Ultrafast; API and Work/Codex eligibility have separate conditions |
| Best initial trial | Work where small quality failures are expensive | Repeated coding, document and application tasks with clear acceptance checks |
The positioning and specifications come from the Astra model page and Sol 6.1 model page. Rate details come from API pricing. The use-case recommendations are our interpretation of the documented tradeoffs.
Specifications: what is the same, and what is undisclosed
| Specification | GPT-6 Astra | GPT-6.1 Sol |
|---|---|---|
| API identifier / current snapshot | gpt-6-astra |
gpt-6.1-sol |
| Model type | Reasoning | Reasoning |
| API total context | 1,050,000 tokens | 1,050,000 tokens |
| Calculated input budget with 128,000 output tokens reserved | 922,000 tokens | 922,000 tokens |
| Maximum output | 128,000 tokens | 128,000 tokens |
| Knowledge cutoff | April 30, 2026 | April 30, 2026 |
| Native inputs | Text, images | Text, images |
| Native output | Text | Text |
| Endpoints | Responses, Chat Completions, Batch | Responses, Chat Completions, Batch |
| Tool calling | Responses API | Responses API |
| Streaming / structured output | Supported | Supported |
| Prompt caching | Supported | Supported |
| Parameter count / training compute | Not disclosed in the reviewed official materials | Not disclosed in the reviewed official materials |
Sources: Astra specifications, Sol 6.1 specifications, and the GPT-6 API guide.
The identical context limits remove one common reason to pay for a higher tier. Astra does not advertise a larger document budget here. Both can accept a substantial repository or document collection, subject to the input limit and the space needed for reasoning and output.
A million-token window still needs an evaluation. Can the model locate the one contractual exception that changes an answer? Can it reconcile a table in an appendix with the main document? Can it distinguish the current implementation from an obsolete example? Context capacity describes how much material fits; your tests establish whether the model uses that material correctly.
Both model pages list web search, file search, computer use, code interpreter, hosted shell, patching, skills, MCP, tool search and image-generation tools. Their native text output does not turn them into native audio or video models. An agent can call an image tool, but that tool has its own behavior and costs. Likewise, the ability to interact with a desktop depends on the application supplying the relevant tool and permissions.
The reviewed documentation does not publish model weights, architecture details sufficient to calculate hardware requirements, or a self-hosting package. Buying API access or a subscription gives access to a service; these are not documented local inference deployments.
Reasoning effort, Pro mode and speed are separate controls
Both models support low, medium, high, xhigh and max API reasoning effort. Sol 6.1 defaults to Medium. Neither supports None or Minimal. For a fair trial, specify the effort explicitly instead of relying on whichever default a client happens to select. Sol's model documentation and the reasoning guide describe these controls.
Reasoning effort changes the amount of reasoning the model can apply. It does not impose a fixed dollar price per question. Two High-effort requests can use different token counts, call different tools and take different amounts of time. The effort label also does not promise identical internal compute across Astra and Sol.
Pro reasoning mode is another setting in Responses. It performs additional model work and bills the aggregate tokens at the selected model's rates. That can improve a difficult answer while increasing its cost and latency. It is distinct from a ChatGPT Pro subscription and from Fast processing. A comparison between Astra in Pro mode and Sol in Standard mode should say so.
Start with the effort you intend to deploy. If Medium passes the relevant checks, running every task at Max may spend money without improving accepted results. When a failure appears, compare a higher Sol effort with Astra at an appropriate effort; test which change resolves the failure at the lower total cost.
Speed and latency: measure the whole workflow
Sol 6.1 gained Responses API Ultrafast on October 8. The current Work/Codex speed guide also lists Ultrafast for both Astra and Sol 6.1 on Pro $500 and eligible Enterprise/Edu plans. API access and product-plan access have separate conditions. OpenAI advertises up to eight times Astra Standard token-generation speed for Astra Ultrafast; that is not a measured reduction in a complete job or a Sol speed claim. Check Work/Codex speed eligibility and API Ultrafast conditions.
Our reviewed sources do not provide a universal, directly comparable tokens-per-second figure for Astra Standard versus Sol 6.1 Standard across all workloads. Do not infer one from their prices. A model can generate quickly yet spend longer planning, invoke more tools, or require another attempt.
For interactive work, record time to first visible output and time to accepted completion separately. For an automation, record median and 95th-percentile completion time, retries, resource errors and throughput under the concurrency you expect to use. Rate limits and access depend on account tier and product; they are deployment constraints rather than model intelligence scores.
Some waits lie outside inference. If a task takes two minutes generating and eight minutes loading pages, even eliminating generation time saves only two minutes. If it spends nine minutes generating and one minute using tools, faster serving can matter much more. Benchmark your task's timing components before paying a speed premium.
OpenAI documents EU API data residency for Sol 6.1 Fast, and US and EU data residency for Sol 6.1 Ultrafast. See the GPT-6 guide’s residency limitations. The Work/Codex guide separately lists United States and European inference residency (EEA plus Switzerland) for Sol 6.1 Ultrafast, while Astra Ultrafast supports United States inference residency only. Check the named model, endpoint and workspace before selecting a regional speed option. Source for Work/Codex: Work/Codex speed guide.
ChatGPT Work and Codex costs differ from API bills
Both models are documented for paid plans in Codex and ChatGPT Work, subject to rollout and workspace settings. Sol 6.1 is available to Plus, Pro, Business, Enterprise and Edu users at launch, excludes Free/Go, and is not yet available in Chat. Enterprise/Edu administrators must enable it. See model availability.
The product's Standard token rates are expressed in credits:
| Per million tokens, Standard credit rates | Astra | Sol 6.1 |
|---|---|---|
| Input | 250 credits | 50 credits |
| Cached input | 25 credits | 2.5 credits |
| Output | 1,250 credits | 250 credits |
OpenAI's plan and credit pricing lists these rates. Included allowance, purchased credits, enterprise agreements and API billing are different arrangements. Subscription price divided by a guessed number of tasks is not a reliable marginal task price.
Eligible paid ChatGPT Pro and Business subscribers can activate a separate OpenAI API-credit benefit. The subscription must be at least seven days old; the claimant must own the subscription or Business workspace and the receiving API organization, use the same email for both accounts, and link the organization. Pro’s $100, $200 and $500 tiers grant $100, $200 and $500 respectively; Business grants depend on paid seats. The first grant is prorated, and unused credits expire at the end of the applicable billing cycle. The benefit does not cover Codex authenticated with API keys or increase ChatGPT or signed-in Codex limits. Compare available credits separately from metered API cost and included subscription allowance.
The same page lists Plus at $20/month and Pro options at $100, $200 and $500/month. Business, Enterprise and Edu arrangements add their own plan terms. Product credit billing has no separate API-style cache-write fee. Check your plan's current allowance and dashboard rather than treating a monthly subscription as a fixed number of benchmark tasks.
Fast uses included subscription limits at 2.5 times Standard, while purchased credits and Enterprise pay-as-you-go Fast usage are billed at twice Standard. Astra and Sol 6.1 Ultrafast use included limits at eight times Standard and purchased/pay-as-you-go usage at six times Standard. Those multipliers describe allowance consumption or billing, not the speed of a completed job. The speed page documents the distinction.
Astra and Sol 6.1 Ultrafast are available on Pro $500 and eligible Enterprise/Edu plans, subject to workspace controls. Other self-serve plans do not gain Ultrafast by buying credits. API-key sessions use API rates; ChatGPT sign-in uses the product allowance and credit rules. Current plan eligibility
Pro 200 correction, checked October 30, 2026: OpenAI canceled the Work/Codex allowance reduction. Higher-allowance subscribers keep it; lower Work/Codex allowances doubled to match. New subscriptions get the same allowance, and existing plans update without waiting for renewal. Pro 200 remains US$200/month without Ultrafast. Check current terms before budgeting.
Work/Codex distinction, checked October 30, 2026: Sol defaults to a 500,000-token context window in Codex and ChatGPT Work. Sol usage drawn from the subscription has no long-context surcharge. These product limits are separate from API specifications and API prices. This does not establish an exemption for purchased-credit usage or mean that context consumes no included allowance.
For a subscription user, Sol may preserve more of the shared Work/Codex allowance for subsequent jobs. For an API application, the relevant evidence is the returned usage and dollar charges. Keep those two accounting systems separate when comparing reported savings.
API adoption checks
For API integrations, check organization and project service-tier settings before switching. A request can fail because its selected or automatically resolved tier is disallowed, even when the model supports that tier. Projects cannot enable tiers blocked by the organization. These API permissions are separate from Work/Codex subscription eligibility.
For both models, use Responses for tool calling; Chat Completions supports requests without tools. Check that the effort is supported and remove unsupported sampling parameters such as temperature and top_p when using reasoning. The GPT-6 migration guidance explains the endpoint and parameter constraints.
GPT-6.1 Sol can participate in the documented beta Responses multi-agent orchestration. The beta guide does not currently list Astra. Parallel agents can shorten waiting, while repeated context and extra reasoning can increase the total bill. The multi-agent guide describes the execution model and beta limitations. Measure the whole orchestration run before deciding it is cheaper or faster.
Preserve representative outputs and usage records during a pilot. Once you have a reliable acceptance check and real task costs, choose the lightest model and setting that clears that check, with a defined path for the remaining cases.
Run your own comparison
Build a small, representative task set before choosing a default. Twenty to fifty cases can expose obvious problems, though it will not precisely measure rare failure rates. Include routine work, difficult cases, long-context cases and known failures. Preserve the files and prompts so both models receive the same starting information.
- Write the acceptance checks and rejection conditions before either run. Use executable checks where they measure the intended outcome, and human review where correctness or quality needs judgment.
- Hold the input, available tools and time limit steady. Record model ID, effort, reasoning mode, speed or service tier, date, harness version, context budget and cache policy separately.
- Run the same task inputs. For subjective deliverables, hide model names during review where practical.
- Log ordinary input, cache reads, cache writes, billable output, reasoning, tool charges, retries and all subagent work. Keep reported usage separate from invoiced charges.
- Capture total elapsed time and human review and correction time. Include every attempt in the cost when escalating a failed result.
- Report accepted-result cost and failures by task type. Repeat cases to understand variation; a small pilot does not establish a general success rate.
- Test the escalation rule on failures and borderline results, including whether it misses bad answers. Keep the lower-cost route only when it meets the same checks.
Keep partial progress and complete success distinct. For a data update, “found the right record” and “saved the correct field without touching another record” should not receive the same acceptance label. Fluent prose with unsupported numbers should fail the factual check.
Retain regression cases and rerun them when the model, prompt, tools or source data change. Calculator estimates apply only to exact routes with valid quotes; they cannot predict success rates or a subscription’s allowance.
Buying questions answered
Is Astra worth five times the price?
When its improvement is worth more than the premium. For a 100K-input/10K-output Standard request without caching, Astra costs $1.50 and Sol $0.30. At an assumed $60/hour, Astra needs to save 72 seconds of review to cover the $1.20 difference. This is a break-even calculation, not a measured productivity gain.
Should I replace Astra everywhere with Sol 6.1?
Move the task types that pass the same acceptance checks at a lower total cost. Keep Astra for the exceptions where it earns its premium. A model-wide switch discards the task-level evidence this guide is designed to help you collect.
Is Sol 6.1 always faster?
No. Current evaluator results and our small CLI observations do not support that claim. Measure your actual path to accepted completion, including tools, retries and review. Lower token prices do not establish lower latency.
Do these prices tell me how many jobs my subscription includes?
No. API rates, product credits and included subscription allowances are different accounting systems. Work and Codex share usage, and effort, context, tools and speed mode affect consumption. Use your current account dashboard and a representative task log.
Sources, method and update history
October 30, 2026, source clarification: Reconciled subscription advice and distinguished Work/Codex context from API specifications and prices. Historical task records, costs and evaluator snapshots retain their original dates. No model or subscription test was run.
October 28, 2026, evaluator version update: Added the newly observed Artificial Analysis v5.0 results and separated the earlier v4.3.2 figures from current comparisons. Preserved the original Kingy task records, Vals evidence and dated throughput snapshots. No new model test was run.
Evidence labels and reading order updated October 22, 2026: Clarified the scope of the three procurement checks, added a compact results table, moved evidence before model-choice guidance, and grouped cost, benchmark and access details. Consolidated the comparison checklist. No new model test or source-price review was performed for this edit; original evidence dates are preserved.
October 22, 2026: Completed the current buying-guide review, added six exact-model task observations with public outputs, added explicit switching rules, refreshed independent results to the current Vals v2.2 snapshot, checked the October 20 cache rules and October 21 project service-tier controls, and linked a matching calculator example. Human correction time and per-run API dollar cost were not measured. No traffic improvement is claimed.
Full refresh October 17, 2026: Added current independent evaluator context and corrected the remaining Sol Ultrafast API-rate row. Official specifications, rates and product eligibility were reviewed alongside the dated launch evidence.
Updated October 17, 2026: Corrected Sol 6.1 Fast/Ultrafast regional availability, added current Work/Codex eligibility, and connected the dated Kingy case studies without reassigning their results to Sol 6.1.
Editorial update October 18, 2026: Moved the model-choice guidance near the start, labeled the earlier Kingy tests with their recorded Sol version, and added a workload calculator link. Benchmark figures, pricing snapshots and historical test dates are unchanged. No new model test was run.
For the release-specific details, see our GPT-6.1 Sol launch guide.
OpenAI released Astra on September 3 and Sol 6.1 on September 29, 2026. Sol 6.1 is the newer release; Astra remains the higher capability tier in OpenAI’s model-selection guidance. Version numbers alone do not decide the purchase.
Related Kingy tests. These earlier tests do not measure GPT-6.1 Sol. The Earlier Astra vs GPT-5.6 Sol working-app test retains the brief, outputs and checks for Astra versus GPT-5.6 Sol. The Earlier Astra vs GPT-5.6 Sol research-to-spreadsheet test examines a different task. Both retain historical evidence; neither supplies evidence about Sol 6.1; the new October 22 task observations above do. Use this guide for the current Astra/Sol 6.1 decision, and keep those older results attached to their tested versions.
The Kingy Brief
Get the free AI price sheet.
26 AI plans and models on one page, from official pricing pages, updated every month. Free when you join The Kingy Brief: AI changes, original tests and one practical thing to try, Fridays at 09:00 Vancouver time.
Free · Double opt-in · Unsubscribe anytime
Sign up for The Kingy Brief on Beehiiv.
Signup help and newsletter schedule
Signup form provided by Beehiiv. After submitting, check your inbox for "Confirm your subscription to The Kingy Brief" and open its confirmation link. Your price sheet download is on the page that opens. Check Spam or Promotions if you cannot find it.
Fridays at 09:00 Vancouver time: source-checked AI changes, original tests and one practical thing to try. We skip a week when there is not enough verified material. Free. Unsubscribe anytime.
Buying details checked October 22, 2026: GPT-6 Astra buying profile: A small completed task set does not establish a general quality advantage or a fixed subscription allowance. GPT-6.1 Sol buying profile: Ultrafast and other service tiers have different charges. Subscription usage does not establish a fixed API credit balance. The original article keeps its existing dates and evidence scope; the linked profiles describe their own demonstrations.